mcpClients) {
return chatClientBuilder.defaultToolCallbacks(new SyncMcpToolCallbackProvider(mcpClients)).build();
}
```
To add OAuth2 to our MCP Client, we configure a Spring Security `SecurityFilterChain` to turn on OAuth2, as well as a custom `WebClient.Builder` used by the MCP client:
```java theme={null}
@Bean
SecurityFilterChain securityFilterChain(HttpSecurity http) throws Exception {
return http.authorizeHttpRequests(auth -> auth.anyRequest().permitAll())
.oauth2Client(Customizer.withDefaults())
.csrf(CsrfConfigurer::disable)
.build();
}
/**
* Overload Boot's default {@link WebClient.Builder}, so that we can inject an
* oauth2-enabled {@link ExchangeFilterFunction} that adds OAuth2 tokens to requests
* sent to the MCP server.
*/
@Bean
WebClient.Builder webClientBuilder(McpSyncClientExchangeFilterFunction filterFunction) {
return WebClient.builder().apply(filterFunction.configuration());
}
```
To add tokens to MCP Client request, we need a custom `ExchangeFilterFunction` that decides which OAuth2 tokens it uses, depending on the context (user interaction or app initialization).
It can look a bit confusing for Spring Security beginners, but feel free to use it as-is:
```java theme={null}
/**
* A wrapper around Spring Security's
* {@link ServletOAuth2AuthorizedClientExchangeFilterFunction}, which adds OAuth2
* {@code access_token}s to requests sent to the MCP server.
*
* The end goal is to use access_token that represent the end-user's permissions. Those
* tokens are obtained using the {@code authorization_code} OAuth2 flow, but it requires a
* user to be present and using their browser.
*
* By default, the MCP tools are initialized on app startup, so some requests to the MCP
* server happen, to establish the session (/sse), and to send the {@code initialize} and
* e.g. {@code tools/list} requests. For this to work, we need an access_token, but we
* cannot get one using the authorization_code flow (no user is present). Instead, we rely
* on the OAuth2 {@code client_credentials} flow for machine-to-machine communication.
*/
@Component
public class McpSyncClientExchangeFilterFunction implements ExchangeFilterFunction {
private final ClientCredentialsOAuth2AuthorizedClientProvider clientCredentialTokenProvider = new ClientCredentialsOAuth2AuthorizedClientProvider();
private final ServletOAuth2AuthorizedClientExchangeFilterFunction delegate;
private final ClientRegistrationRepository clientRegistrationRepository;
// Must match registration id in property
// spring.security.oauth2.client.registration..authorization-grant-type=authorization_code
private static final String AUTHORIZATION_CODE_CLIENT_REGISTRATION_ID = "authserver";
// Must match registration id in property
// spring.security.oauth2.client.registration..authorization-grant-type=client_credentials
private static final String CLIENT_CREDENTIALS_CLIENT_REGISTRATION_ID = "authserver-client-credentials";
public McpSyncClientExchangeFilterFunction(OAuth2AuthorizedClientManager clientManager,
ClientRegistrationRepository clientRegistrationRepository) {
this.delegate = new ServletOAuth2AuthorizedClientExchangeFilterFunction(clientManager);
this.delegate.setDefaultClientRegistrationId(AUTHORIZATION_CODE_CLIENT_REGISTRATION_ID);
this.clientRegistrationRepository = clientRegistrationRepository;
}
/**
* Add an {@code access_token} to the request sent to the MCP server.
*
* If we are in the context of a ServletRequest, this means a user is currently
* involved, and we should add a token on behalf of the user, using the
* {@code authorization_code} grant. This typically happens when doing an MCP
* {@code tools/call}.
*
* If we are NOT in the context of a ServletRequest, this means we are in the startup
* phases of the application, where the MCP client is initialized. We use the
* {@code client_credentials} grant in that case, and add a token on behalf of the
* application itself.
*/
@Override
public Mono filter(ClientRequest request, ExchangeFunction next) {
if (RequestContextHolder.getRequestAttributes() instanceof ServletRequestAttributes) {
return this.delegate.filter(request, next);
}
else {
var accessToken = getClientCredentialsAccessToken();
var requestWithToken = ClientRequest.from(request)
.headers(headers -> headers.setBearerAuth(accessToken))
.build();
return next.exchange(requestWithToken);
}
}
private String getClientCredentialsAccessToken() {
var clientRegistration = this.clientRegistrationRepository
.findByRegistrationId(CLIENT_CREDENTIALS_CLIENT_REGISTRATION_ID);
var authRequest = OAuth2AuthorizationContext.withClientRegistration(clientRegistration)
.principal(new AnonymousAuthenticationToken("client-credentials-client", "client-credentials-client",
AuthorityUtils.createAuthorityList("ROLE_ANONYMOUS")))
.build();
return this.clientCredentialTokenProvider.authorize(authRequest).getAccessToken().getTokenValue();
}
/**
* Configure a {@link WebClient} to use this exchange filter function.
*/
public Consumer configuration() {
return builder -> builder.defaultRequest(this.delegate.defaultRequest()).filter(this);
}
}
```
And with that, we have everything we need! Asking our LLM weather-related questions will trigger a call our Weather MCP tool:
```java theme={null}
var chatResponse = chatClient.prompt("What is the weather in %s right now?".formatted(query))
.call()
.content();
```
If you'd like to try it for yourself, we have [a fully packaged demo application](https://github.com/Kehrlann/spring-ai-mcp-authorization-demo/) available on GitHub.
## What's next?
This is a first step implementing full, end-to-end authorization.
By using Spring's powerful extensibility, we can add OAuth2 to our MCP Clients and Servers, but it requires writing some code.
The Spring team is hard at work building a simpler integration, with the delightful configuration-driven Boot user experience.
We are also working on fine-grained permissions for MCP Servers.
In more advanced use-cases, not all tools/resources/prompts in an MCP Server will require the same permissions: the "thing-reader" tool will be available to every user, but the "thing-writer" is only available to admins.
***
\[1]: [Model Context Protocol](https://docs.spring.io/spring-ai/reference/1.0/api/mcp/mcp-overview.html), or MCP for short, is a protocol allow AI models to interact with and access external tools and resources in a structured way. Spring AI provides [out-of-the box support](https://docs.spring.io/spring-ai/reference/api/mcp/mcp-overview.html) for both MCP Servers and MCP Clients.
# Dynamic Tool Updates in Spring AI's Model Context Protocol
Source: https://springaicommunity.mintlify.app/blog/mcp/mcp-dynamic-tool-updates
The Model Context Protocol (MCP) is a powerful feature in Spring AI that enables AI models to access external tools and resources through a standardized...
The Model Context Protocol (MCP) is a powerful feature in Spring AI that enables AI models to access external tools and resources through a standardized interface. One interesting capabilities of MCP is its ability to dynamically update available tools at runtime.
This blog post explores how Spring AI implements dynamic tool updates in MCP, providing flexibility and extensibility to AI-powered applications.
The related example code is available here: [Dynamic Tool Update Example](https://github.com/spring-projects/spring-ai-examples/tree/main/model-context-protocol/dynamic-tool-update)
## Understanding the Model Context Protocol
![]() Before diving into dynamic tool updates, let's understand what MCP is and why it matters:
[The Model Context Protocol (MCP)](https://modelcontextprotocol.io/introduction) is a standardized interface that allows AI applicaitons and Agents to: **Access external tools** , **Retrieve resources** , **Use prompt templates** .
MCP follows a [client-server architecture](https://modelcontextprotocol.io/docs/concepts/architecture): **MCP Servers** - expose tools, resources, and prompts; **MCP Clients** - connect to servers and use their capabilities; **AI Models** - interact with the world through these clients
Spring AI provides a comprehensive implementation of MCP with both [client](https://docs.spring.io/spring-ai/reference/api/mcp/mcp-client-boot-starter-docs.html) and [server](https://docs.spring.io/spring-ai/reference/api/mcp/mcp-server-boot-starter-docs.html) components, making it easy to integrate AI capabilities into Spring applications.
### The Dynamic Tool Update Feature
One powerful aspects of the MCP is the ability to dynamically update the available tools at runtime. This means:
* MCP Servers can add or remove tools without restarting
* MCP Clients can detect these changes
* AI models can immediately use the new capabilities
## How Dynamic Tool Updates Work
The dynamic tool update process involves several components working together:
### Server-Side Implementation
Spring AI's `@Tool` annotation makes it easy to expose methods as MCP tools:
```java theme={null}
public class MathTools {
@Tool(description = "Adds two numbers")
public int sumNumbers(int number1, int number2) {
return number1 + number2;
}
// ...
}
```
The framework automatically:
1. Extracts method parameters as tool inputs
2. Generates appropriate JSON schemas
3. Handles parameter validation and conversion
On the server side, Spring AI's MCP implementation provides a straightforward way to add MCP tools at start time and dynamically at runtime:
```java theme={null}
@SpringBootApplication
public class ServerApplication {
//1. Tools added at start time by the Spring AI MCP Server Boot starter
@Bean
public ToolCallbackProvider weatherTools(WeatherService weatherService) {
return MethodToolCallbackProvider.builder().toolObjects(weatherService).build();
}
//2. Runtime tool addition
@Bean
public CommandLineRunner commandRunner(McpSyncServer mcpSyncServer) {
return args -> {
// Wait for some tool update signal
// Add math tools dynamically
List newTools = McpToolUtils
.toSyncToolSpecifications(ToolCallbacks.from(new MathTools()));
for (SyncToolSpecification newTool : newTools) {
mcpSyncServer.addTool(newTool);
}
};
}
}
```
In this example:
1. The server initially exposes only weather forecast tools
2. When a custom tool-update signal is received the `McpSyncServer.addTool()` method is used to dynamically register new tools
The `McpSyncServer` class provides methods for tool management:
* `addTool(SyncToolSpecification)` - Adds a new tool
* `removeTool(String)` - Removes a tool by name
* `notifyToolsListChanged()` - Notifies clients about tool changes
> **NOTE:** you can add and/or remove Tools only after the Clinet/Server connection has been initialized.
### Client-Side Implementation
The MCP protocol includes a notification system that allows servers to inform clients about changes to available tools. This notification system ensures that clients always have an up-to-date view of the server's capabilities.
On the client side, Spring AI provides mechanisms to detect and react to tool changes:
```java theme={null}
@Bean
McpSyncClientCustomizer customizeMcpClient() {
return (name, mcpClientSpec) -> {
mcpClientSpec.toolsChangeConsumer(tv -> {
logger.info("\nMCP TOOLS CHANGE: " + tv);
latch.countDown();
});
};
}
```
The client registers a listener that is invoked whenever the server's available tools change. This allows the client to:
1. Be notified when tools are added or removed
2. Update its internal state accordingly
3. Make the new tools immediately available to the AI model
Currently Spring AI doesn't maintain internal state about the updated tools, but you can use the customization listener to implement smart tool caching or similar.
### Tool Discovery and Usage
The client can discover available tools at any time:
```java theme={null}
List toolDescriptions = chatClientBuilder.build()
.prompt("What tools are available?")
.toolCallbacks(tools)
.call()
.entity(new ParameterizedTypeReference>() {});
```
A key insight from the Spring AI MCP implementation is:
> **TIP**: The client implementation relies on the fact that the [ToolCallbackProvider#getToolCallbacks](https://github.com/spring-projects/spring-ai/blob/9e71b163e315199fe7b46495d87a0828a807b88f/mcp/common/src/main/java/org/springframework/ai/mcp/SyncMcpToolCallbackProvider.java#L132) implementation for MCP will always retrieves the current list of MCP tools from the server.
> This means that whenever a client requests the available tools, it will always get the most up-to-date list from the server, without needing to restart or reinitialize the client.
## Practical Applications
Dynamic tool updates in MCP enable several powerful use cases:
### 1. Feature Flags for AI Capabilities
You can implement feature flags that control which AI capabilities are available:
```java theme={null}
if (featureFlags.isEnabled("advanced-math")) {
mcpSyncServer.addTool(advancedMathTools);
}
```
### 2. Context-Aware Tool Loading
Load tools based on the current context or user permissions:
```java theme={null}
if (userHasPermission(currentUser, "admin-tools")) {
mcpSyncServer.addTool(adminTools);
}
```
### 3. Progressive Enhancement
Start with basic tools and add more advanced capabilities as needed:
```java theme={null}
// Start with basic tools
mcpSyncServer.addTool(basicTools);
// Add advanced tools when the user reaches a certain level
userService.onUserLevelUp(user -> {
if (user.getLevel() >= 5) {
mcpSyncServer.addTool(advancedTools);
}
});
```
### 4. Dynamic Plugin Architecture
Implement a plugin system where new capabilities can be added at runtime:
```java theme={null}
pluginRegistry.onPluginLoaded(plugin -> {
if (plugin.hasMcpTools()) {
mcpSyncServer.addTool(plugin.getMcpTools());
}
});
```
## Conclusion
Spring AI's handling of dynamic tool updates in the Model Context Protocol provides a mechanism for extending AI capabilities at runtime. This feature enables more flexible, extensible, and resource-efficient AI applications.
Key takeaways:
1. **Standardized Interface**: MCP provides a consistent way for AI models to interact with external tools and resources.
2. **Dynamic Updates**: Tools can be added or removed at runtime without requiring application restarts.
3. **Automatic Discovery**: Clients can detect changes to available tools and make them immediately available to AI models.
4. **Simple API**: Spring AI provides a clean, annotation-based API for defining and managing MCP tools.
By leveraging dynamic tool updates in Spring AI's MCP implementation, developers can create more adaptable AI applications that can evolve their capabilities based on runtime conditions, user needs, and system requirements.
## Resources
* [Spring AI Documentation](https://docs.spring.io/spring-ai/reference/)
* [Model Context Protocol Tools Specification](http://localhost:3000/specification/2024-11-05/server/tools)
* [Spring AI Examples Repository](https://github.com/spring-projects/spring-ai-examples)
# Connect Your AI to Everything: Spring AI's MCP Boot Starters
Source: https://springaicommunity.mintlify.app/blog/mcp/mcp-intro
The Model Context Protocol (MCP) standardizes how AI applications interact with external tools and resources.
![]() The Model Context Protocol (MCP) standardizes how AI applications interact with external tools and resources.
Spring joined the MCP ecosystem early as a key contributor, helping to develop and maintain the [official MCP Java SDK](https://modelcontextprotocol.io/sdk/java/mcp-overview) that serves as the foundation for Java-based MCP implementations.
Building on this contribution, Spring AI has embraced MCP with comprehensive support through dedicated [Boot Starters](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-overview.html#_spring_ai_mcp_integration) and [MCP Java Annotations](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-annotations-overview.html), making it easier than ever to build sophisticated AI-powered applications that can seamlessly connect to external systems.
This blog introduces core MCP components and demonstrates building both MCP Servers and Clients using Spring AI, showcasing basic and advanced features. The complete source code is available at: [MCP Weather Example](https://github.com/tzolov/spring-ai-mcp-blogpost).
> **Note:** This content applies only to Spring AI `1.1.0-SNAPSHOT` or Spring `AI 1.1.0-M1+` versions.
## What is the Model Context Protocol?
The [Model Context Protocol (MCP)](https://modelcontextprotocol.org/docs/concepts/architecture) is a standardized protocol that enables AI models to interact with external tools and resources in a structured way.
Think of it as a bridge between your AI models and the real world - allowing them to access databases, APIs, file systems, and other external services through a consistent interface.
You can bootstrap AI applications with MCP support using [Spring Initializr](https://start.spring.io).
For comprehensive details, see the [Spring AI MCP Overview](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-overview.html) documentation.
### MCP Client-Server Architecture
![isolated]()
The Model Context Protocol follows a Client-Server architecture that ensures a clear separation of concerns.
The MCP Server exposes specific capabilities (tools, resources, prompts) from third-party services.
MCP clients are instantiated by host applications to communicate with particular MCP servers. Each client handles one direct communication with one server.
The Host is the AI application users interact with, while clients are the protocol-level components that enable server connections.
The MCP protocol ensures complete, language-agnostic interoperability between clients and servers.
You can have Clients written in Java, Python, or TypeScript communicating with servers in any language and vice versa.
This architecture establishes distinct boundaries and responsibilities between client and server-side development, naturally creating two distinct developer communities:
**AI Application/Host Developers**
Handle the complexity of orchestrating multiple MCP servers (connected via MCP Clients) and integrating with AI models. AI developers build AI applications that:
* Use MCP Clients to consume capabilities from multiple MCP Servers
* Handle AI model integration and prompt engineering
* Manage conversation context and user interactions
* Orchestrate complex workflows across different services
* Focus on creating compelling user experiences
**MCP Server (Provider) Developers**
Focus on exposing specific capabilities (tools, resources, prompts) from third-party services as MCP Servers. Server developers create servers that:
* Wrap third-party services and APIs (databases, file systems, external APIs)
* Expose service capabilities through standardized MCP primitives (tools, resources, prompts)
* Handle authentication and authorization for their specific services
Such separation ensures that Server developers can concentrate on wrapping their domain-specific services without worrying about AI orchestration. At the same time the AI application developers can leverage existing MCP servers without understanding the intricacies of each third-party service.
The division of labor means that a database expert can create an MCP server for PostgreSQL without needing to understand LLM prompting, while an AI application developer can use that PostgreSQL server without knowing SQL internals. The MCP protocol acts as the universal language between them.
**Spring AI** embraces this architecture with [MCP Client](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-client-boot-starter-docs.html) and [MCP Server](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-server-boot-starter-docs.html) Boot Starters.
This means Spring developers can participate in both sides of the MCP ecosystem - building AI applications that consume MCP servers and creating MCP servers that expose Spring-based services to the wider AI community.
### MCP Features
![MCP Capabilities]()
Shared between the Client and the Server, MCP provides an extensive set of features that enable seamless communication between AI applications and external services:
* Expose [tools](https://modelcontextprotocol.io/specification/2025-06-18/server/tools) that AI models can invoke
* Share [resources](https://modelcontextprotocol.io/specification/2025-06-18/server/resources) and data with AI applications
* Provide [prompt](https://modelcontextprotocol.io/specification/2025-06-18/server/prompts) templates for consistent interactions
* Offers argument [autocompletion](https://modelcontextprotocol.io/specification/2025-06-18/server/utilities/completion) suggestions for prompts and resource URIs
* Handle real-time notifications and [progress](https://modelcontextprotocol.io/specification/2025-06-18/basic/utilities/progress) updates
* Support client-side [sampling](https://modelcontextprotocol.io/specification/2025-06-18/client/sampling), [elicitation](https://modelcontextprotocol.io/specification/2025-06-18/client/elicitation), [structured logging](https://modelcontextprotocol.io/specification/2025-06-18/server/utilities/logging) and [progress tracking](https://modelcontextprotocol.io/specification/2025-06-18/basic/utilities/progress)
* Support various transport protocols: [STDIO](http://localhost:3000/specification/2025-06-18/basic/transports#stdio), [Streamable-HTTP](http://localhost:3000/specification/2025-06-18/basic/transports#streamable-http), and [SSE](http://localhost:3000/specification/2024-11-05/basic/transports#http-with-sse)
> **Important:** Tools are owned by the LLM, unlike other MCP features such as prompts and resources. The LLM—not the Host—decides if, when, and in what order to call tools. The Host only controls which tool descriptions are offered to the LLM.
#### Client Features
MCP Clients enable AI applications to consume capabilities from MCP Servers:
* **Roots**: Expose filesystem "roots" to servers
* **Sampling**: Standardized way for servers to request LLM sampling from LLMS via clients
* **Elicitation**: Standardized way for servers to request additional information from users through the client during interactions.
* **Progress Tracking Listener**: Monitor long-running operations with real-time progress updates
* **Structured Logging Listener**: Receive detailed log messages from servers for debugging and monitoring
* **Change Notifications Listeners**: Get notified when server capabilities (tools, resources, prompts) are updated
#### Server Features
MCP Servers expose capabilities and services to AI applications:
* **Tools**: Publish functions that AI models can invoke through standardized interfaces
* **Resources**: Provide access to data sources, files, and external systems
* **Prompts**: Share reusable prompt templates with parameter support
* **Completion**: Argument autocompletion suggestions for prompts and resource URIs
* **Real-time Notifications**: Send updates about capability changes to connected clients
* **Progress Reporting**: Emit progress updates for long-running operations
* **Structured Logging**: Send detailed log messages to clients for transparency
## Build an MCP Server
Let's build a [Streamable-HTTP MCP Server](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-streamable-http-server-boot-starter-docs.html) that provides real-time weather forecast information.
#### Spring Boot Server application
Create a new (`mcp-weather-server`) Spring Boot application:
```java theme={null}
@SpringBootApplication
public class McpServerApplication {
public static void main(String[] args) {
SpringApplication.run(McpServerApplication.class, args);
}
}
```
with Spring AI MCP Server dependency:
```xml theme={null}
org.springframework.ai
spring-ai-starter-mcp-server-webmvc
```
```bash theme={null}
spring.ai.mcp.server.protocol=STREAMABLE
```
You can start the server with either `STREAMABLE`, `STATELESS` or `SSE` transport.
To enable the `STDIO` transport you need to set `spring.ai.mcp.server.stdio=true`.
#### Weather Service
Leverage the free [Weather REST API](https://open-meteo.com/) to build a service that can retrieve weather forecasts by location coordinates.
Add @McpTool and @McpToolParam annotations to register the `getTemperature` method as an MCP Server Tool:
```java theme={null}
@Service
public class WeatherService {
public record WeatherResponse(Current current) {
public record Current(LocalDateTime time, int interval, double temperature_2m) {}
}
@McpTool(description = "Get the temperature (in celsius) for a specific location")
public WeatherResponse getTemperature(
@McpToolParam(description = "The location latitude") double latitude,
@McpToolParam(description = "The location longitude") double longitude) {
return RestClient.create()
.get()
.uri("https://api.open-meteo.com/v1/forecast?latitude={latitude}&longitude={longitude}¤t=temperature_2m",
latitude, longitude)
.retrieve()
.body(WeatherResponse.class);
}
}
```
#### Build & Run
```bash theme={null}
./mvnw clean install -DskipTests
java -jar target/mcp-weather-server-0.0.1-SNAPSHOT.jar
```
This starts the mcp-weather-server on port `8080`.
#### Using the MCP Server
Once the MCP Weather Server is up and running, you can interact with it using various MCP compliant client applications:
**[MCP Inspector](https://modelcontextprotocol.io/legacy/tools/inspector)**
The MCP Inspector is an interactive developer tool for testing and debugging MCP servers.
To start the inspector run:
```bash theme={null}
npx @modelcontextprotocol/inspector
```
In the browser UI, set the Transport Type to `Streamable HTTP` and the URL to `http://localhost:8080/mcp`.
Click `Connect` to establish the connection.
Then list the tools and run the getTemperature.
![MCP Capabilities]()
**[MCP Java SDK](https://modelcontextprotocol.io/sdk/java/mcp-client#client-features)**
Use the MCP Java SDK client to programmatically connect to the server:
```java theme={null}
var client = McpClient.sync(
HttpClientStreamableHttpTransport
.builder("http://localhost:8080").build())
.build();
client.initialize();
CallToolResult weather = client.callTool(
new CallToolRequest("getTemperature",
Map.of("latitude", "47.6062",
"longitude", "-122.3321")));
```
**Other MCP compliant AI Applications/SDKs**
Connect your MCP server to popular AI applications:
* [Cline](https://docs.cline.bot/mcp/mcp-overview) - AI coding assistant for VS Code
* [VS Code MCP](https://code.visualstudio.com/docs/copilot/customization/mcp-servers) - GitHub Copilot MCP integration
* [Cursor MCP](https://docs.cursor.com/en/context/mcp)
* [Non-Java MCP client](https://modelcontextprotocol.io/docs/develop/build-client) - Build MCP Client using with other (non-Java) SDKs
* ...
**[Claude Desktop](https://claude.ai/download)**
To integrate with Claude Desktop, using the local [STDIO transport](https://modelcontextprotocol.io/specification/2025-06-18/basic/transports#stdio), add the following configuration to your Claude Desktop settings:
```json theme={null}
{
"mcpServers": {
"spring-ai-mcp-weather": {
"command": "java",
"args": [
"-Dspring.ai.mcp.server.stdio=true",
"-Dspring.main.web-application-type=none",
"-Dlogging.pattern.console=",
"-jar",
"/path/to/mcp-weather-server-0.0.1.jar"]
}
}
}
```
*Replace `/absolute/path/to/` with the actual path to your built JAR file.*
Follow the [MCP server installation for Claude Desktop](https://www.anthropic.com/engineering/desktop-extensions) for further guidance. The free version of the Claude Desktop doesn't support Sampling!
### Advanced Server Features
Let's extend our MCP Weather Server to demonstrate advanced MCP capabilities including Logging, Progress Tracking, and Sampling.
These features enable rich interactions between servers and clients:
* **Logging**: Send structured log messages to connected clients for debugging and monitoring
* **Progress Tracking**: Report real-time progress updates for long-running operations
* **Sampling**: Request the client's LLM to generate content based on server data
In this enhanced version, our weather server will log its operations to the client for transparency, report progress as it fetches and processes weather data
and request the client's LLM to generate an epic poem about the weather forecast
Here's the updated server implementation:
```java theme={null}
@Service
public class WeatherService {
public record WeatherResponse(Current current) {
public record Current(LocalDateTime time, int interval, double temperature_2m) {}
}
@McpTool(description = "Get the temperature (in celsius) for a specific location")
public String getTemperature(
McpSyncServerExchange exchange, // (1)
@McpToolParam(description = "The location latitude") double latitude,
@McpToolParam(description = "The location longitude") double longitude,
@McpProgressToken String progressToken) { // (2)
exchange.loggingNotification(LoggingMessageNotification.builder() // (3)
.level(LoggingLevel.DEBUG)
.data("Call getTemperature Tool with latitude: " + latitude + " and longitude: " + longitude)
.meta(Map.of()) // non null meta as a workaround for bug: ...
.build());
WeatherResponse weatherResponse = RestClient.create()
.get()
.uri("https://api.open-meteo.com/v1/forecast?latitude={latitude}&longitude={longitude}¤t=temperature_2m",
latitude, longitude)
.retrieve()
.body(WeatherResponse.class);
String epicPoem = "MCP Client doesn't provide sampling capability.";
if (exchange.getClientCapabilities().sampling() != null) {
// 50% progress
exchange.progressNotification(new ProgressNotification(progressToken, 0.5, 1.0, "Start sampling")); // (4)
String samplingMessage = """
For a weather forecast (temperature is in Celsius): %s.
At location with latitude: %s and longitude: %s.
Please write an epic poem about this forecast using a Shakespearean style.
""".formatted(weatherResponse.current().temperature_2m(), latitude, longitude);
CreateMessageResult samplingResponse = exchange.createMessage(CreateMessageRequest.builder()
.systemPrompt("You are a poet!")
.messages(List.of(new SamplingMessage(Role.USER, new TextContent(samplingMessage))))
.build()); // (5)
epicPoem = ((TextContent) samplingResponse.content()).text();
}
// 100% progress
exchange.progressNotification(new ProgressNotification(progressToken, 1.0, 1.0, "Task completed"));
return """
Weather Poem: %s
about the weather: %s°C at location: (%s, %s)
""".formatted(epicPoem, weatherResponse.current().temperature_2m(), latitude, longitude);
}
}
```
1. **McpSyncServerExchange** - the `exchange` parameter provides access to server-client communication capabilities. It allows the server to send notifications and make requests back to the client.
2. **@ProgressToken** - the `progressToken` parameter enables progress tracking. The client provides this token, and the server uses it to send progress updates.
3. **Logging Notifications** - sends structured log messages to the client for debugging and monitoring purposes.
4. **Progress Updates** - reports operation progress (50% in this case) to the client with a descriptive message.
![MCP Capabilities]()
5. **Sampling Capability** - the most powerful feature - the server can request the client's LLM to generate content.
This allows the server to leverage the client's AI capabilities, creating a bidirectional AI interaction pattern.
The enhanced weather service now returns not just weather data, but a creative poem about the forecast, demonstrating the powerful synergy between MCP servers and AI models.
## Build an MCP Client
Let's build an AI application that uses an LLM and connects to MCP Servers via MCP Clients.
#### Client Configuration
Create a new Spring Boot project (`mcp-weather-client`) with the following dependencies:
```xml theme={null}
org.springframework.ai
spring-ai-starter-mcp-client
org.springframework.ai
spring-ai-starter-model-anthropic
```
```yml theme={null}
spring:
main:
web-application-type: none
ai:
# Set credentials for your Anthropic API account
anthropic:
api-key: ${ANTHROPIC_API_KEY}
# Connect to the MCP Weather Server using streamable-http client transport
mcp:
client:
streamable-http:
connections:
my-weather-server:
url: http://localhost:8080
```
Note that the configuration has assigned the `my-weather-server` name to the server connection.
#### Spring Boot Client Application
Create a client application that uses `ChatClient` connected to an LLM and to the MCP Weather Server:
```java theme={null}
@SpringBootApplication
public class McpClientApplication {
public static void main(String[] args) {
SpringApplication.run(McpClientApplication.class, args).close(); // (1)
}
@Bean
public ChatClient chatClient(ChatClient.Builder chatClientBuilder) { // (2)
return chatClientBuilder.build();
}
String userPrompt = """
Check the weather in Amsterdam right now and show the creative response!
Please incorporate all creative responses from all LLM providers.
""";
@Bean
public CommandLineRunner predefinedQuestions(ChatClient chatClient, ToolCallbackProvider mcpToolProvider) { // (3)
return args -> System.out.println(
chatClient.prompt(userPrompt) // (4)
.toolContext(Map.of("progressToken", "token-" + new Random().nextInt())) // (5)
.toolCallbacks(mcpToolProvider) // (6)
.call()
.content());
}
}
```
1. **Application Lifecycle Management** - the application starts, executes the weather query, displays the result, and then exits cleanly.
2. **ChatClient Configuration** - creates a configured [ChatClient](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/chatclient.html) bean using Spring AI's auto-configured builder. The builder is automatically populated with:
* The AI model configuration (Anthropic Claude in our case)
* Default settings and configurations from application.properties
3. **CommandLineRunner** - runs automatically after the application context is fully loaded. It injects the configured ChatClient for AI model interaction and the `ToolCallbackProvider` which contains all registered MCP tools from connected servers.
4. **AI Prompt** - instructs the AI model to get Amsterdam's current weather. The AI model automatically discovers and calls the appropriate MCP tools based on the prompt.
5. **Progress Token** - uses the `toolContext` to pass a unique `progressToken` to MCP tools annotated with @McpProgressToken parameter.
6. **MCP Tool Integration** - this crucial line connects the ChatClient to all available MCP tools:
* `mcpToolProvider` is auto-configured by Spring AI's MCP Client starter
* Contains all tools from connected MCP servers (configured via `spring.ai.mcp.client.*.connections.*`)
* The AI model can automatically discover and invoke these tools during conversation
#### Client MCP Handlers
Create a service class to handle MCP notifications and requests from the server.
These handlers are the **client-side counterparts** to the advanced server features we implemented above, enabling bidirectional communication between the MCP Server and Client:
```java theme={null}
@Service
public class McpClientHandlers {
private static final Logger logger = LoggerFactory.getLogger(McpClientHandlers.class);
private final ChatClient chatClient;
public McpClientHandlers(@Lazy ChatClient chatClient) { // Lazy is needed to avoid circular dependency
this.chatClient = chatClient;
}
@McpProgress(clients = "my-weather-server") // (1)
public void progressHandler(ProgressNotification progressNotification) {
logger.info("MCP PROGRESS: [{}] progress: {} total: {} message: {}",
progressNotification.progressToken(), progressNotification.progress(),
progressNotification.total(), progressNotification.message());
}
@McpLogging(clients = "my-weather-server")
public void loggingHandler(LoggingMessageNotification loggingMessage) {
logger.info("MCP LOGGING: [{}] {}", loggingMessage.level(), loggingMessage.data());
}
@McpSampling(clients = "my-weather-server")
public CreateMessageResult samplingHandler(CreateMessageRequest llmRequest) {
logger.info("MCP SAMPLING: {}", llmRequest);
String llmResponse = chatClient
.prompt()
.system(llmRequest.systemPrompt())
.user(((TextContent) llmRequest.messages().get(0).content()).text())
.call()
.content();
return CreateMessageResult.builder().content(new TextContent(llmResponse)).build();
}
}
```
##### Understanding the Handler Components:
1. **Progress Handler** - Receives real-time progress updates from the server's long-running operations. Triggered when the server calls `exchange.progressNotification(...)`. For example the weather server sends 50% progress when starting sampling, then 100% when complete. Commonly used to display progress bars, update UI status, or log operation progress.
2. **Logging Handler** - Receives structured log messages from the server for debugging and monitoring. Triggered when the server calls `exchange.loggingNotification(...)`. For example the weather server logs "Call getTemperature Tool with latitude: X and longitude: Y". Used to debug server operations, audit trails, or monitoring dashboards.
3. **Sampling Handler** - The Most Powerful Feature. It enables the server to request AI-generated content from the client's LLM. Used for bidirectional AI interactions, creative content generation, dynamic responses. Triggered when the server calls `exchange.createMessage(...)` with sampling capability check. The execution flow looks like this:
* If client supports sampling, requests a poem about the weather
* Client handler receives the request and uses its ChatClient to interact with the LLM and generate the poem
* Generated poem is returned to the server and incorporated into the final tool response
##### Key Design Patterns:
* **Annotation-Based Routing**: The `clients = "my-weather-server"` attribute ensures handlers only process notifications from the specific MCP server connection defined in your configuration: `spring.ai.mcp.client.streamable-http.connections.[my-weather-server].url`.
If your application connects to multiple MCP servers, use the `clients` attribute to assign each handler to the corresponding MCP Client:
```java theme={null}
@McpProgress(clients = {"weather-server", "database-server"}) // Handle progress from multiple servers
public void multiServerProgressHandler(ProgressNotification notification) {
// Handle progress from both servers
}
@McpSampling(clients = "specialized-ai-server") // Handle sampling from specific server
public CreateMessageResult specializedSamplingHandler(CreateMessageRequest request) {
// Handle sampling requests from specialized AI server
}
```
* The **@Lazy** annotation on ChatClient prevents circular dependency issues that can occur when the ChatClient also depends on MCP components
* **Bidirectional AI Communication**: The sampling handler creates a powerful pattern where:
* The server (domain expert) can leverage the client's AI capabilities
* The client's LLM generates creative content based on server-provided context
* This enables sophisticated AI-to-AI interactions beyond simple tool invocation
This architecture makes the MCP Client a **reactive participant** in server operations, enabling sophisticated interactions rather than just passive tool consumption.
#### Multiple MCP Servers
Connect to multiple MCP servers using different transports.
Here's how to add the [Brave Search MCP Server](https://github.com/brave/brave-search-mcp-server) for web search alongside your weather server:
![MCP Demo]()
```yaml theme={null}
spring:
ai:
anthropic:
api-key: ${ANTHROPIC_API_KEY}
mcp:
client:
streamable-http:
connections:
my-weather-server:
url: http://localhost:8080
stdio:
connections:
brave-search:
command: npx
args: ["-y",
"@modelcontextprotocol/server-brave-search"]
```
It uses the STDIO client transport.
Now your LLM can combine weather data and web search in a single prompt:
```java theme={null}
String userPrompt = """
Check the weather in Amsterdam and show the creative response!
Please incorporate all creative responses.
Then search online to find publishers for poetry and list top 3.
""";
```
#### Build & Run
Make sure that your MCP Weather Server is up and running.
Then build and start your client:
```bash theme={null}
./mvnw clean install -DskipTests
java -jar target/mcp-weather-client-0.0.1-SNAPSHOT.jar
```
## Conclusion
The combination of Spring's proven development model with MCP's standardized protocol creates a powerful foundation for the next generation of AI applications.
Whether you're building chatbots, data analysis tools, or development assistants, Spring AI's MCP support provides the building blocks you need.
This introduction covered the essential MCP concepts and demonstrated how to build both MCP Servers and Clients using Spring AI's Boot Starters with basic Tool functionality. However, the MCP ecosystem offers much more sophisticated capabilities that we'll explore in upcoming blog posts:
* **Java MCP Annotations Deep Dive**: Learn how to leverage Spring AI's annotation-based approach for creating more maintainable and declarative MCP implementations, including advanced annotation patterns and best practices.
* **Beyond Tools - Prompts, Resources & Completions**: Discover how to implement the full spectrum of MCP capabilities including shared prompt templates, dynamic resource provisioning, and intelligent autocompletion features that make your MCP servers more user-friendly and powerful.
* **Authorization support - securing MCP Servers**: Secure your MCP Servers with OAuth 2, and ensure only authorized users can access tools, resources and other capabilities. Add authorization support to your MCP Clients, so they can obtain OAuth 2 tokens to authenticate with secure MCP servers.
Ready to get started? Check out the [example applications](https://github.com/spring-projects/spring-ai-examples/tree/main/model-context-protocol) and explore the full potential of AI integration with Spring AI and MCP.
## Additional Resources
* [Model Context Protocol Specification](https://modelcontextprotocol.io/specification/) - Official MCP protocol documentation
* [MCP Java SDK](https://modelcontextprotocol.io/sdk/java/mcp-overview) - MCP Java SDK documentation
* [MCP Weather Example Code](https://github.com/tzolov/spring-ai-mcp-blogpost)
* [Spring AI MCP Overview](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-overview.html) - Complete architectural overview and concepts
* [MCP Client Boot Starter](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-client-boot-starter-docs.html) - Client configuration and usage guide
* [MCP Server Boot Starter](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-server-boot-starter-docs.html) - Server setup and configuration
* [STDIO and SSE Servers](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-stdio-sse-server-boot-starter-docs.html) - Traditional transport mechanisms
* [Streamable-HTTP Servers](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-streamable-http-server-boot-starter-docs.html) - Modern HTTP-based transport
* [Stateless Streamable-HTTP Servers](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-stateless-server-boot-starter-docs.html) - Cloud-native deployment options
* [Spring AI MCP Java Annotations](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-annotations-overview.html) - Annotation-based method handling for MCP servers and clients in Java
* [Client Annotations](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-annotations-client.html) - Declarative way to implement MCP client handlers using Java annotations
* [Server Annotations](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-annotations-server.html) - Declarative way to implement MCP server functionality using Java annotations
* [Special Parameters](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/mcp/mcp-annotations-special-params.html) - Special parameter types that provide additional context and functionality to annotated methods
***
*For the latest updates and comprehensive documentation, visit the [Spring AI Reference Documentation](https://docs.spring.io/spring-ai/reference/).*
# Introducing the Model Context Protocol Java SDK
Source: https://springaicommunity.mintlify.app/blog/mcp/mcp-java-sdk-released
> This blog post is co-authored with [David Soria Parra](https://github.com/dsp-ant), [Christian Tzolov](https://github.com/tzolov), and [Dariusz...
> This blog post is co-authored with [David Soria Parra](https://github.com/dsp-ant), [Christian Tzolov](https://github.com/tzolov), and [Dariusz Jędrzejczyk](https://github.com/chemicL).
# What is MCP
The Model Context Protocol (MCP), an open protocol developed by [Anthropic](https://www.anthropic.com/), is transforming the way AI applications connect and share context. It has garnered extensive support across AI applications, functioning as a standardized interface for Large Language Models (LLMs) to interact with data sources, tools, and AI agents. Whether you're building autonomous systems that need to access databases, orchestrating complex AI workflows, or creating systems where multiple agents collaborate, MCP provides the foundational layer that makes these integrations seamless.
What sets MCP apart is its focus on composability and interoperability. Beyond just connecting to data sources, MCP enables developers to build rich, interactive AI systems where agents can share context, access tools, and work together through a consistent interface. This means you can quickly plug into a growing ecosystem of pre-built integrations while maintaining the flexibility to switch between different LLM providers, making it an ideal foundation for building sophisticated AI applications.
# Introducing the MCP Java SDK
What began as an experimental project last November has turned into an exciting collaboration with the Spring AI team and Anthropic.
We're thrilled to announce that the experimental project has been moved into the official MCP Java SDK.\
This SDK is the latest language binding of the protocol, alongside the Python, TypeScript, and Kotlin SDKs, on [modelcontextprotocol.io](https://modelcontextprotocol.io). Java has long been the language of the enterprise, and the MCP Java SDK makes it easier for organizations to develop cutting-edge AI applications.
The MCP Java SDK provides a comprehensive foundation for integrating AI models with external tools and data sources. Key features of the SDK include:
### Client and Server Implementations
* Supports both synchronous and asynchronous MCP communication.
* Enables protocol version compatibility negotiation for smooth interoperability.
### Tool and Resource Management
* Discover, register, and execute tools dynamically.
* Receive real-time list change notifications for tools and resources.
* Manage resources using URI templates for structured access and subscriptions.
### Prompt Handling and AI Sampling Support
* Retrieve and manage prompts to customize AI model behavior.
* Supports sampling strategies to fine-tune AI interactions.
### Multiple Transport Implementations
* Stdio-based transport for direct process communication.
* Java HttpClient-based SSE client transport for HTTP-based streaming.
* Servlet-based SSE server transport for streaming over HTTP in a traditional server environment.
* Spring-based transports for seamless Spring Boot integration:
* Spring WebFlux-based SSE transport for reactive applications.
* Spring WebMVC-based SSE transport for servlet-based applications.
Please check out the [documentation](https://modelcontextprotocol.io/sdk/java/mcp-overview) for more information on getting started, and visit the [GitHub repository](https://github.com/modelcontextprotocol/java-sdk) to open issues and join discussions.
# Spring AI and MCP
The Spring AI project extends the MCP Java SDK by adding developer productivity enhancements for integration with Spring Boot applications. With Spring Boot starters, developers can quickly configure MCP clients and servers using Spring’s dependency injection and configuration management, making it easier to integrate AI-driven workflows into their applications.
#### Client Starters
* `spring-ai-mcp-client-spring-boot-starter` – Core client starter supporting STDIO and HTTP-based SSE transport.
* `spring-ai-mcp-client-webflux-spring-boot-starter` – WebFlux-based SSE transport implementation for reactive applications.
#### Server Starters
* `spring-ai-mcp-server-spring-boot-starter` – Core server starter supporting STDIO transport.
* `spring-ai-mcp-server-webmvc-spring-boot-starter` – Spring MVC-based SSE transport implementation for servlet-based applications.
* `spring-ai-mcp-server-webflux-spring-boot-starter` – WebFlux-based SSE transport implementation for reactive applications.
Here’s an example of how to declaratively configure an STDIO-transported client application. In `application.yml`, define the following configuration:
```yaml theme={null}
spring:
ai:
mcp:
client:
stdio:
servers-configuration: classpath:mcp-servers.json
```
And the referenced JSON file defines the server to connect to in the Claude Desktop format.
```json theme={null}
{
"mcpServers": {
"filesystem": {
"command": "npx",
"args": [
"-y",
"@modelcontextprotocol/server-filesystem",
"/Users/username/Desktop",
"/Users/username/Downloads"
]
}
}
}
```
When the client application starts, it will launch the MCP server, establish STDIO communication channels, and manage the server lifecycle.
Spring AI M6 also introduces the `@Tool` annotation, which simplifies the creation of MCP servers. For more information, please read the [Spring AI Reference documentation on MCP.](https://docs.spring.io/spring-ai/reference/api/mcp/mcp-overview.html)
# Next Steps
We look forward to feedback on GitHub and are very grateful for the support of the Anthropic team.
# Securing Spring AI MCP servers with OAuth2
Source: https://springaicommunity.mintlify.app/blog/mcp/mcp-server-oauth2
Spring AI offers [support for Model Context Protocol](https://docs.spring.io/spring-ai/reference/1.0/api/mcp/mcp-overview.html), or MCP for short, which allows...
Spring AI offers [support for Model Context Protocol](https://docs.spring.io/spring-ai/reference/1.0/api/mcp/mcp-overview.html), or MCP for short, which allows AI models to interact with and access external tools and resources in a structured way.
With Spring AI, developers can create their own MCP Servers and expose capabilities to AI models in just a few lines of code.
## Authorization and security in MCP
MCP Servers can run locally, using the STDIO transport.
To expose an MCP server to the outside world, it must expose a few standard HTTP endpoints.
While MCP Servers used privately might not require strict authentication, enterprise deployments need robust security and permission management for exposed endpoints.
This challenge is addressed in the [newest version of the MCP specification (2025-03-26)](https://spec.modelcontextprotocol.io/specification/2025-03-26/), which was released last week.
It lays the foundation for securing communications between Clients and Servers, leveraging the widespread [OAuth2 framework](https://oauth.net/2/).
While we won't do a full review of OAuth2 in this blog post, a quick refresher might prove useful.
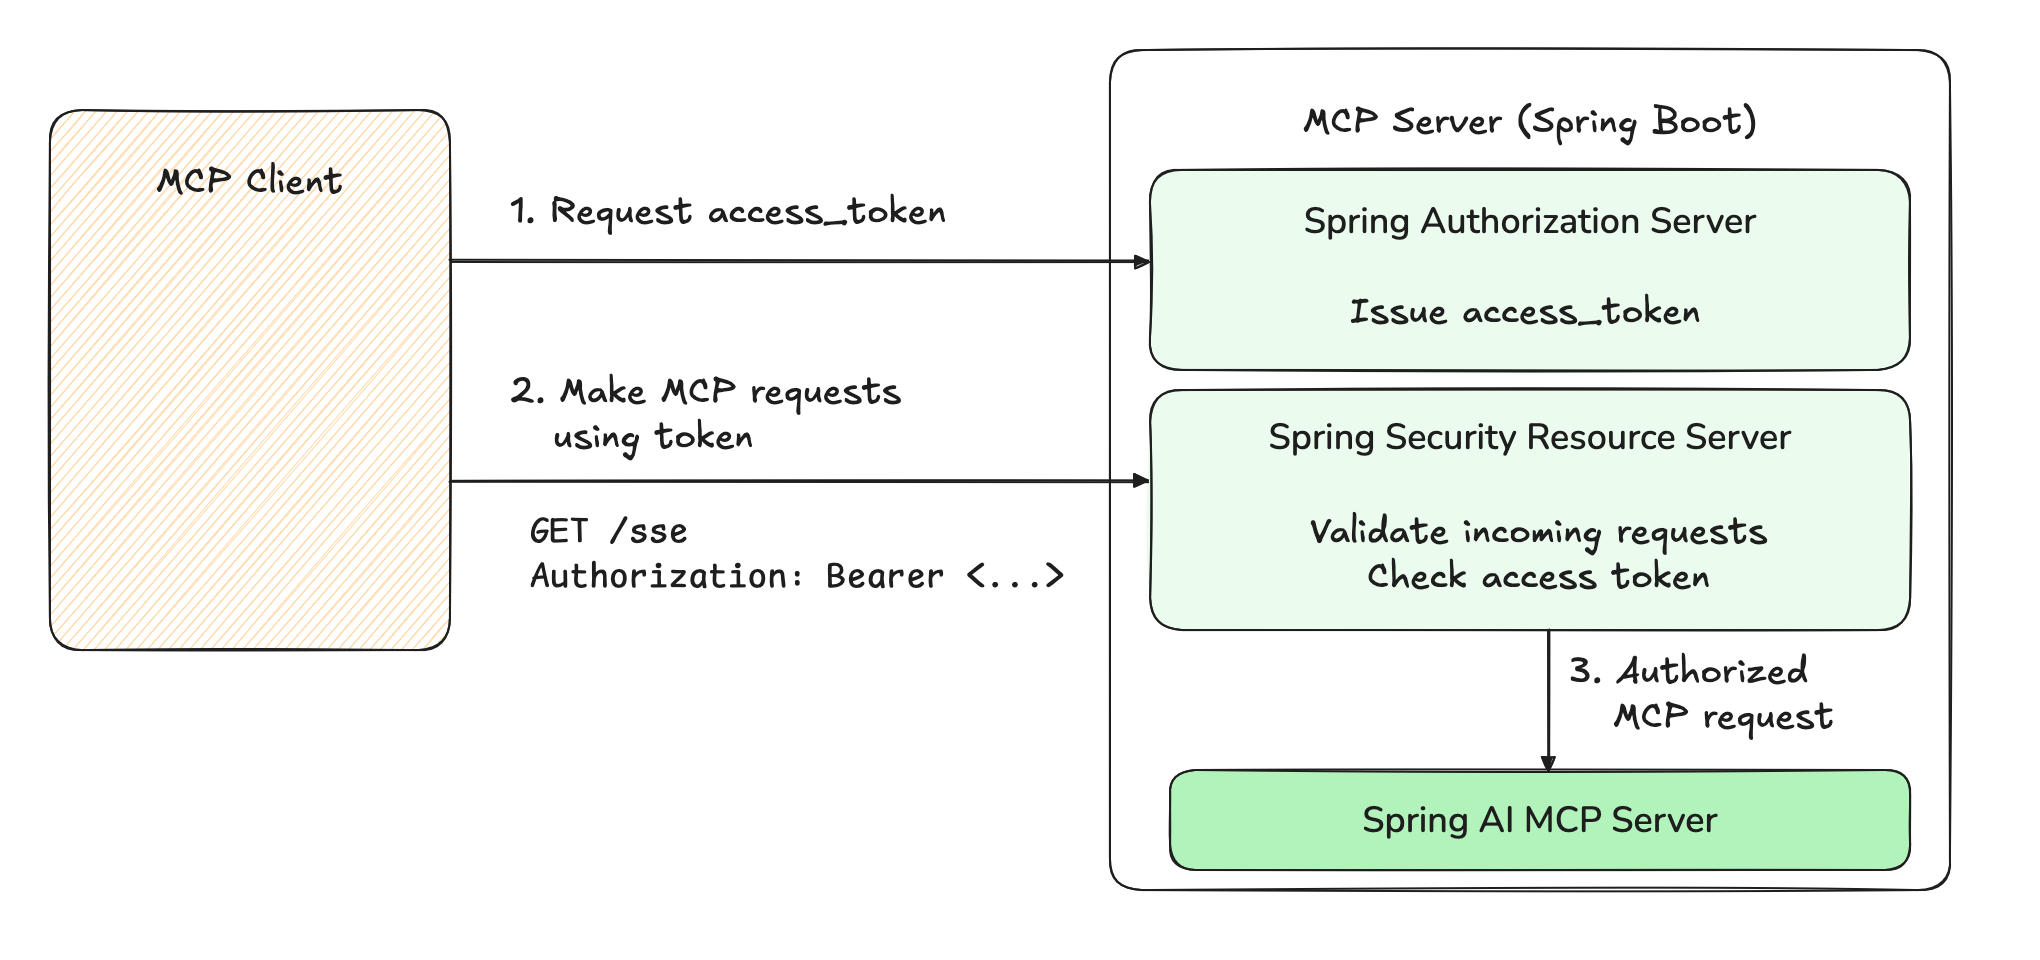
In the draft of the spec, the MCP Server is both a Resource Server and an Authorization Server.
As a Resource Server, it performs authorization checks on incoming requests by checking the `Authorization` header.
The header MUST contain an OAuth2 `access_token`, which is a string representing the "permissions" of the Client.
That token may be a JSON Web Token (JWT) or an opaque string that does not carry information by itself.
If the token is missing or invalid (malformed, expired, wrong recipient, ...), the Resource Server rejects the request.
Using those tokens, a typical request might look like:
```shell theme={null}
curl https://mcp.example.com/sse
-H "Authorization: Bearer "
```
As an Authorization Server, the MCP Server must also be able to issue `access_token`s for clients in a secure fashion.
Before issuing a token, the Server will verify the Client's credentials, and, in some cases, the identity of the user trying to access the Server.
The Authorization Server will decide the characteristics of the token: its expiry, scope, intended audiences, etc.
Using Spring Security and Spring Authorization Server, we can easily add both capabilities to an existing Spring MCP Server.
## Adding OAuth2 to your Spring MCP server
In this example, we will add OAuth 2 support to a sample MCP Server - the ["Weather" MCP tool](https://github.com/spring-projects/spring-ai-examples/tree/main/model-context-protocol/weather/starter-webmvc-server) from our Spring AI examples repository.
We will not explore the client-side of the interaction, only ensure our server can issue tokens and validate them.
First, we import the required Boot starters in `pom.xml`:
```xml theme={null}
org.springframework.boot
spring-boot-starter-oauth2-resource-server
org.springframework.boot
spring-boot-starter-oauth2-authorization-server
```
Then, we configure an OAuth2 Client in our `application.properties`, so that we can request access tokens:
```properties theme={null}
spring.security.oauth2.authorizationserver.client.oidc-client.registration.client-id=mcp-client
spring.security.oauth2.authorizationserver.client.oidc-client.registration.client-secret={noop}secret
spring.security.oauth2.authorizationserver.client.oidc-client.registration.client-authentication-methods=client_secret_basic
spring.security.oauth2.authorizationserver.client.oidc-client.registration.authorization-grant-types=client_credentials
```
This is the simplest possible client.
We can interact with the authorization server directly by making POST requests, no browser needed, and use the hard-coded credentials `mcp-client` / `secret`.
The last step is to enable the authorization server and resource server features.
We do so by creating a configuration class for our security features, for example `SecurityConfiguration`, in which we expose a `SecurityFilterChain` bean:
```java theme={null}
import static org.springframework.security.oauth2.server.authorization.config.annotation.web.configurers.OAuth2AuthorizationServerConfigurer.authorizationServer;
@Configuration
@EnableWebSecurity
class SecurityConfiguration {
@Bean
SecurityFilterChain securityFilterChain(HttpSecurity http) throws Exception {
return http.authorizeHttpRequests(auth -> auth.anyRequest().authenticated())
.with(authorizationServer(), Customizer.withDefaults())
.oauth2ResourceServer(resource -> resource.jwt(Customizer.withDefaults()))
.csrf(CsrfConfigurer::disable)
.cors(Customizer.withDefaults())
.build();
}
}
```
This filter chain will do a number of things:
* Ensure every request is authenticated. With this, our MCP Server will only allow requests with an `access_token`.
* Enable both Spring Authorization Server and Spring Resource Server.
* Turn off CSRF (Cross-Site Request Forgery). An MCP server is not designed for browser-based interactions, and does not require CSRF.
* Turn on CORS (Cross-Origin Resource Sharing) support, so we can demo the server with the MCP inspector.
With this, our application is secured, and will only accept requests that have an access token.
Otherwise, requests will be rejected, with an `HTTP 401 Unauthorized` error. For example:
```shell theme={null}
curl http://localhost:8080/sse --fail-with-body
#
# Response:
#
# curl: (22) The requested URL returned error: 401
```
To use our MCP server, we need to obtain an access token first.
We use the `client_credentials` OAuth2 grant, which is used in "machine to machine" or "service account" scenarios:
```shell theme={null}
curl -XPOST http://localhost:8080/oauth2/token --data grant_type=client_credentials --user mcp-client:secret
#
# Response:
#
# {"access_token":"","token_type":"Bearer","expires_in":299}%
```
Copy the value of the `access_token`. It starts with letters "ey".
We can now use this access token to make requests, and they should succeed.
For example using `curl`, your can replace `YOUR_ACCESS_TOKEN` by the value you copied above:
```shell theme={null}
curl http://localhost:8080/sse -H"Authorization: Bearer YOUR_ACCESS_TOKEN"
#
# Response:
#
# id:918d5ebe-9ae5-4b04-aae8-c1ff8cdbb6e0
# event:endpoint
# data:/mcp/message?sessionId=918d5ebe-9ae5-4b04-aae8-c1ff8cdbb6e0
```
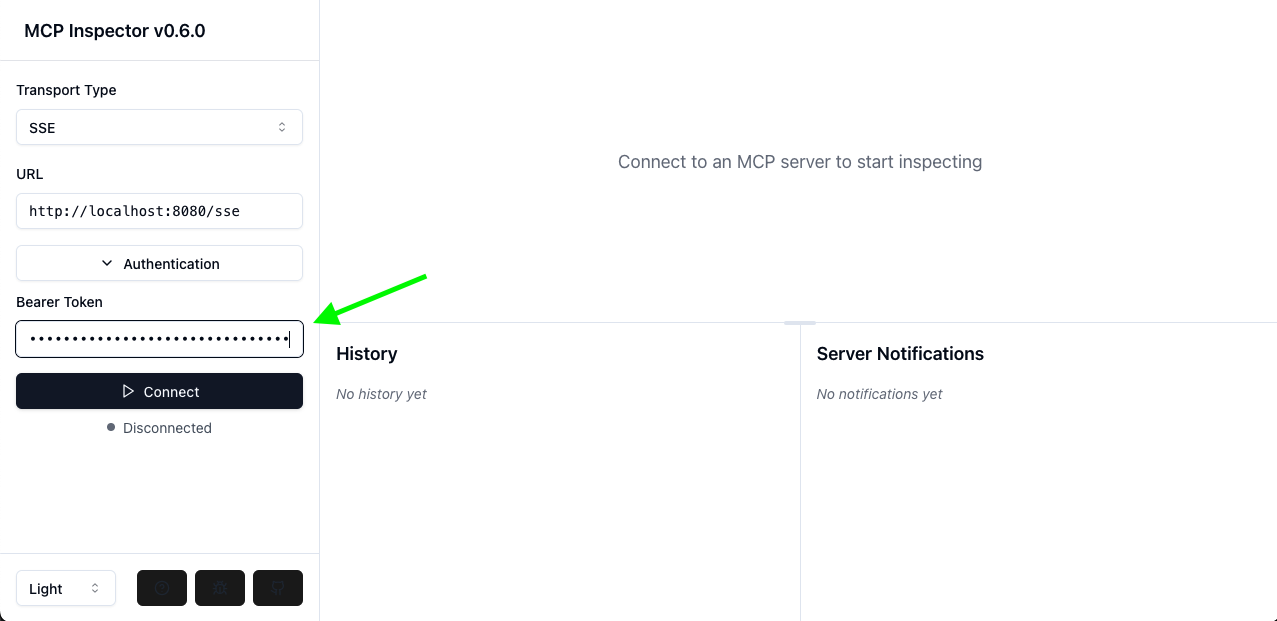
It is also possible to use the access token directly in the [MCP inspector](https://modelcontextprotocol.io/docs/tools/inspector), since version `0.6.0`.
Simply spin up the inspector, and paste the access token in the "Authentication > Bearer" field on the left-hand menu.
Then click Connect: you should be able to make MCP calls.
If you would like to run this yourself, you can check out [the sample code](https://github.com/spring-projects/spring-ai-examples/tree/main/model-context-protocol/weather/starter-webmvc-oauth2-server) in the `spring-ai-examples` repository.
## What's next?
In this example, we have implemented foundational OAuth2 capabilities in the MCP Server.
The obvious next step is to update MCP Client and allow it to authenticate with the Server, and use the "authorization code" OAuth2 grant.
With this flow, users can log in with their own credentials, and obtain user-bound tokens, allowing for more fine-grained permissions, for example with Roles-Based Access Control (RBAC).
We will also explore using an external OAuth2 Authorization Server for issuing tokens, and only implementing the Resource Server capabilities in our MCP Servers.
# Securing MCP Servers with Spring AI
Source: https://springaicommunity.mintlify.app/blog/mcp/mcp-server-security
[Model Context Protocol](https://modelcontextprotocol.io/), or MCP for short, has taken over the AI world.
![]() [Model Context Protocol](https://modelcontextprotocol.io/), or MCP for short, has taken over the AI world.
If you've been following our blog, you've probably read the introduction to the
topic, [Connect Your AI to Everything: Spring AI's MCP Boot Starters](https://spring.io/blog/2025/09/16/spring-ai-mcp-intro-blog).
The security aspects of MCP have been evolving fast, and the latest version of the spec is getting more and more support
from the ecosystem.
To meet the needs of Spring users, we have incubated a dedicated project on
Github: [spring-ai-community/mcp-security](https://github.com/spring-ai-community/mcp-security/).
This week, we pushed our first releases, and you can now add them to your Spring AI 1.1.x-based applications.
In this post, we'll explore:
* [Securing MCP Servers with OAuth2](#securing-mcp-servers-with-oauth-2)
* [Building an MCP-compatible Spring Authorization Server](#mcp-compatible-spring-authorization-server)
* [Securing MCP Servers with API Keys](#beyond-oauth-2-api-keys) instead of OAuth2
## Securing MCP Servers with OAuth 2
According to the [Authorization section](https://modelcontextprotocol.io/specification/2025-06-18/basic/authorization)
of the MCP specification, MCP Servers exposed over HTTP must be secured with OAuth 2 access tokens.
Any call to an MCP Server must have a header `Authorization: Bearer `, where the access token is obtained
from an authorization server (think: Okta, Github, ...) on behalf of the user.
The MCP Server must also explicitly advertise the authorization servers it trusts, so MCP clients can discover them
dynamically, register themselves with the auth servers, and obtain tokens.
We'll discuss authorization servers later on, but for now we'll assume you have an auth server configured and running at
``, and we'll hook our MCP Server to it.
If you need to setup an authorization server, see [next section](#mcp-compatible-spring-authorization-server).
First, add the required dependencies to your project:
*Maven:*
```xml theme={null}
org.springframework.ai
spring-ai-starter-mcp-server-webmvc
org.springaicommunity
mcp-server-security
0.0.3
org.springframework.boot
spring-boot-starter-oauth2-resource-server
```
*Gradle:*
```groovy theme={null}
implementation("org.springframework.ai:spring-ai-starter-mcp-server-webmvc")
implementation("org.springaicommunity:mcp-server-security:0.0.3")
implementation("org.springframework.boot:spring-boot-starter-oauth2-resource-server")
```
Ensure that MCP server is enabled in your `application.properties`, and inject your authorization server URL:
```properties theme={null}
spring.ai.mcp.server.name=my-cool-mcp-server
# Supported protocols: STREAMABLE, STATELESS
spring.ai.mcp.server.protocol=STREAMABLE
# Choose any property name you'd like
# You MAY use the usual Spring well-known "spring.security.oauth2.resourceserver.jwt.issuer-uri".
authorization.server.url=
```
We will add a simple MCP tool that greets the user, based on an input language ("english", "french", ...) and on
the user's name.
```java theme={null}
@Service
public class MyToolsService {
@McpTool(name = "greeter", description = "A tool that greets you, in the selected language")
public String greet(
@ToolParam(description = "The language for the greeting (example: english, french, ...)") String language
) {
if (!StringUtils.hasText(language)) {
language = "";
}
var authentication = SecurityContextHolder.getContext().getAuthentication();
var name = authentication.getName();
return switch (language.toLowerCase()) {
case "english" -> "Hello, %s!".formatted(name);
case "french" -> "Salut %s!".formatted(name);
default -> ("I don't understand language \"%s\". " +
"So I'm just going to say Hello %s!").formatted(language, name);
};
}
}
```
In this example, the tool will look up the name of the user from the `SecurityContext`, and create a personalised
greeting.
The name of the user will be the `sub` claim from the JWT access token used to authenticate the request:
And, last but not least, we add a configuration class for security, for example `McpServerSecurityConfiguration`:
```java theme={null}
@Configuration
@EnableWebSecurity
class McpServerSecurityConfiguration {
@Value("${authorization.server.url}")
private String authServerUrl;
@Bean
SecurityFilterChain securityFilterChain(HttpSecurity http) throws Exception {
return http
// Enforce authentication with token on EVERY request
.authorizeHttpRequests(auth -> auth.anyRequest().authenticated())
// Configure OAuth2 on the MCP server
.with(
McpServerOAuth2Configurer.mcpServerOAuth2(),
(mcpAuthorization) -> {
// REQUIRED: the authserver's issuer URI
mcpAuthorization.authorizationServer(this.authServerUrl);
// OPTIONAL: enforce the `aud` claim in the JWT token.
mcpAuthorization.validateAudienceClaim(true);
}
)
.build();
}
}
```
Run the application with `./mvnw spring-boot:run` or `./gradlew bootRun`. It should start on port 8080.
If you try to access the MCP server at `http://localhost:8080/mcp`, you will get an `WWW-authenticate` indicating the
OAuth2 resource metadata URL:
```shell theme={null}
curl -XPOST -w '%{http_code}\n%header{www-authenticate}' http://localhost:8080/mcp
#
# Will print out:
#
# 401
# Bearer resource_metadata=http://localhost:8080/.well-known/oauth-protected-resource/mcp
```
The metadata URL itself will indicate to potential clients where the authorization server is located:
```shell theme={null}
curl http://localhost:8080/.well-known/oauth-protected-resource/mcp
#
# Will print out:
#
# {
# "resource": "http://localhost:8080/mcp",
# "authorization_servers": [
# ""
# ],
# "resource_name": "Spring MCP Resource Server",
# "bearer_methods_supported": [
# "header"
# ]
# }
```
This is not very useful to a human, but it helps other programs find the authentication entry points for your MCP
Server.
Every AI-based app has their own unique way of adding an MCP server, but a good tool to debug your server is the
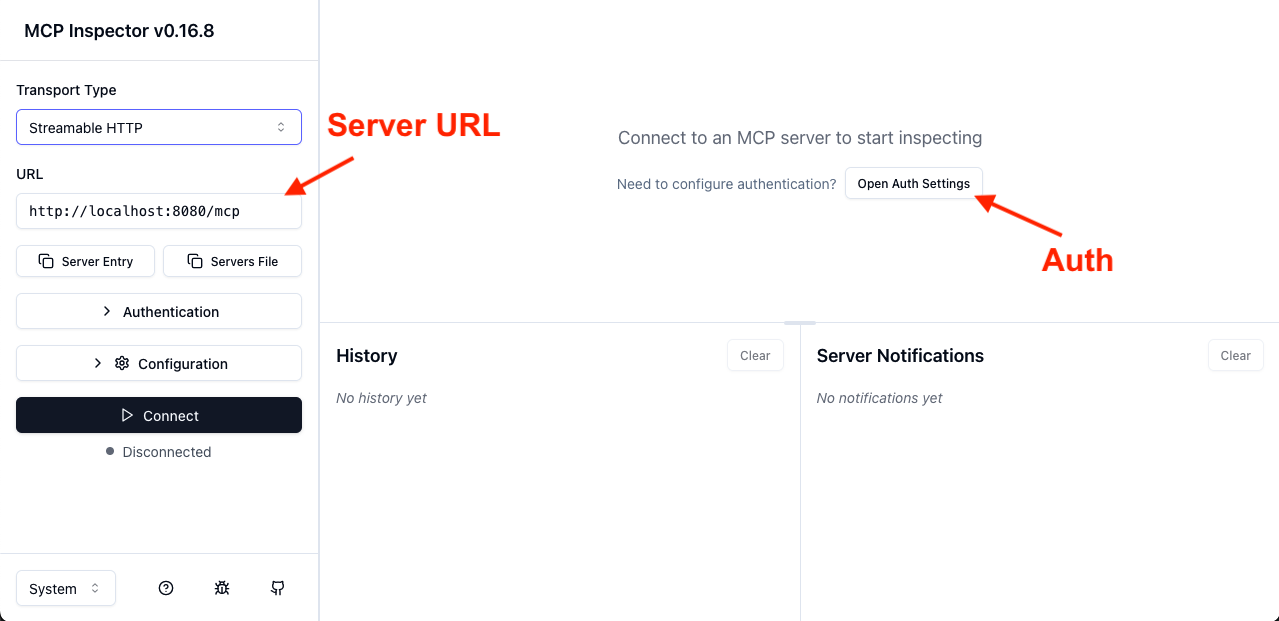
[MCP inspector](https://modelcontextprotocol.io/docs/tools/inspector). You can run it easily with:
```shell theme={null}
npx @modelcontextprotocol/inspector@0.16.7
```
In the UI, you must set the URL of your server, and then click "Open Auth Settings":
In the auth settings, select the "Quick OAuth Flow".
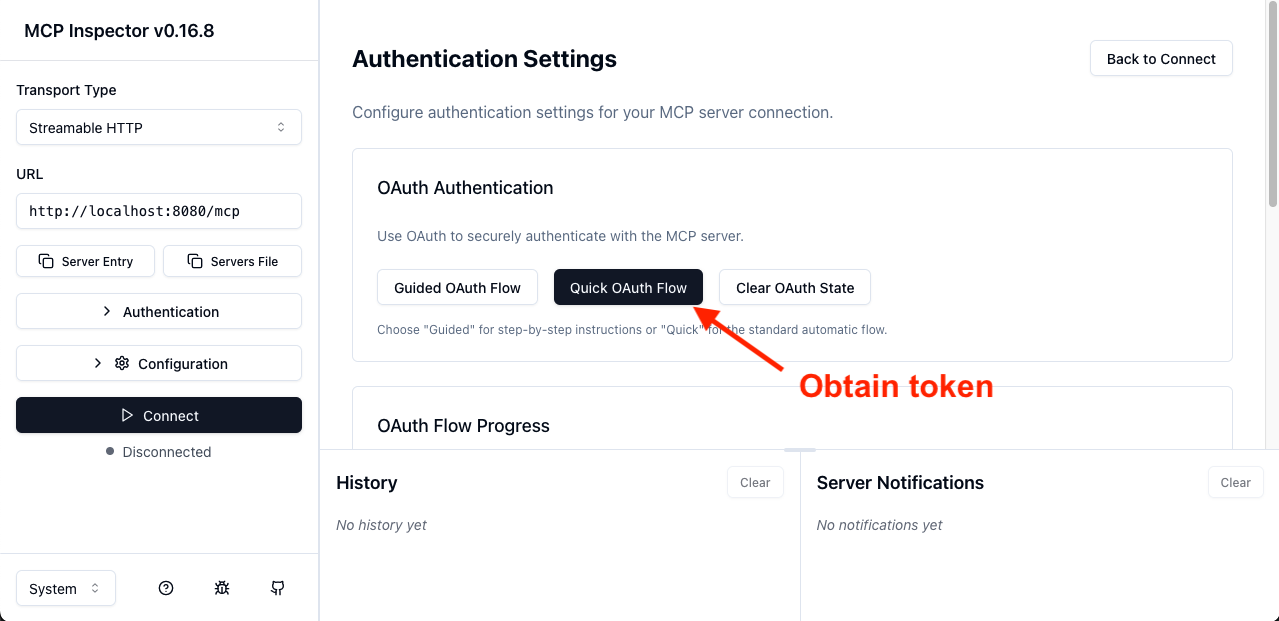
This will redirect you to the authorization server.
Once you log in, you will be redirected back to the MCP inspector, which will display a success message and the first
few characters of an access token. From there, you should be able to connect and ultimately call our "greeter" tool:
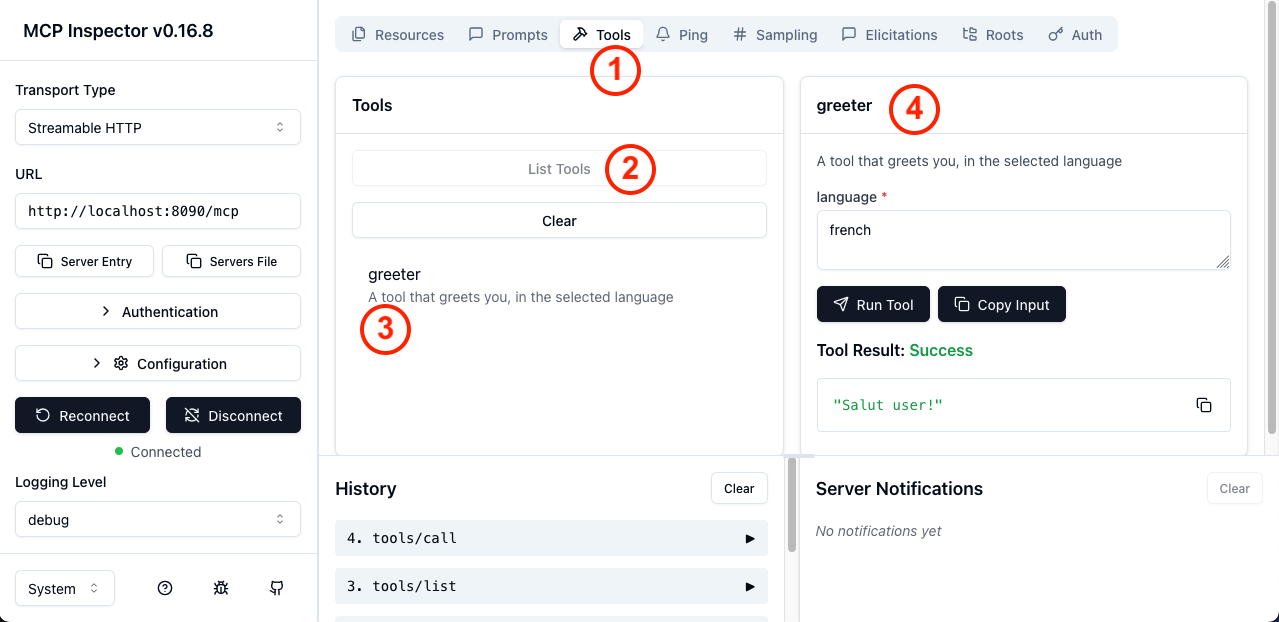
In the screenshot above, in order, you can do:
1. Select the `Tools` tab
2. Click `List tools`
3. Select the `greeter` tool
4. Fill the arguments and call the tool
And with this, you have your very first spec-compliant, OAuth2-secured MCP Server.
There are variants around this implementation, for example a use-case where everything on the MCP server is publicly
accessible (e.g. "list tools"), except calling the tools themselves.
It is not spec compliant but matches certain specific needs.
You can learn
more [in the dedicated section](https://github.com/spring-ai-community/mcp-security/?tab=readme-ov-file#special-case-only-secure-tool-calls-with-oauth2)
in the mcp-security docs.
Of course, for users to log in, you must connect your MCP Server to an authorization server, that complies with the
required specifications for MCP, such as dynamic client registration.
While there are many SaaS options available, you can also write you own
with [Spring Authorization Server](https://docs.spring.io/spring-authorization-server/).
## MCP-compatible Spring Authorization Server
To create an MCP-compatible authorization server with Spring, create a new Spring project, with Spring Authorization
Server, and add the MCP-specific:
*Maven*
```xml theme={null}
org.springaicommunity
mcp-authorization-server
0.0.3
```
*Gradle*
```groovy theme={null}
implementation("org.springaicommunity:mcp-authorization-server:0.0.3")
```
You can configure the Authorization Server in the usual way (
see [reference documentation](https://docs.spring.io/spring-security/reference/7.0/servlet/oauth2/authorization-server/getting-started.html#oauth2AuthorizationServer-developing-your-first-application)).
Here is an example `application.yml` for registering a default client and a default user:
```yaml theme={null}
spring:
application:
name: sample-authorization-server
security:
oauth2:
authorizationserver:
client:
default-client:
token:
access-token-time-to-live: 1h
registration:
client-id: "default-client-id"
client-secret: "{noop}default-client-secret"
client-authentication-methods:
- "client_secret_basic"
- "none"
authorization-grant-types:
- "authorization_code"
- "client_credentials"
redirect-uris:
- "http://127.0.0.1:8080/authorize/oauth2/code/authserver"
- "http://localhost:8080/authorize/oauth2/code/authserver"
# mcp-inspector
- "http://localhost:6274/oauth/callback"
user:
# A single user, named "user"
name: user
password: password
server:
port: 9000
servlet:
session:
cookie:
# Override the default cookie name (JSESSIONID).
# This allows running multiple Spring apps on localhost, and they'll each have their own cookie.
# Otherwise, since the cookies do not take the port into account, they are confused.
name: MCP_AUTHORIZATION_SERVER_SESSIONID
```
This is only an example, and you'll likely want to write your own configuration.
With this configuration, there will be a single user registered (username: `user`, password: `password`).
There will also be a single OAuth2 Client (`default-client-id` / `default-client-secret`).
You can then activate all the authorization server capabilities with the usual Spring Security API,
the security filter chain:
```java theme={null}
@Bean
SecurityFilterChain securityFilterChain(HttpSecurity http) throws Exception {
return http
// all requests must be authenticated
.authorizeHttpRequests(auth -> auth.anyRequest().authenticated())
// enable authorization server customizations
.with(McpAuthorizationServerConfigurer.mcpAuthorizationServer(), withDefaults())
// enable form-based login, for user "user"/"password"
.formLogin(withDefaults())
.build();
}
```
With this, your Spring Authorization Server will
support [OAuth 2 Dynamic Client Registration](https://www.rfc-editor.org/rfc/rfc7591.html) as well as [Resource
Indicators for OAuth 2](https://www.rfc-editor.org/rfc/rfc8707.html).
Connecting your MCP Server to this authorization server is compatible with the majority of AI tools,
such as Claude Desktop, Cursor, or the MCP inspector.
## Beyond OAuth 2: API keys
While the MCP specification mandates using OAuth2 for security, many environments do not have the infrastructure to
support this use-case.
To be usable in environments lacking OAuth 2, many clients, including the MCP inspector itself, allow you to pass custom
headers when making requests.
This opens the door to alternative authentication flows, including API key-based security.
The MCP Security project supports API keys, which we'll showcase below.
First, add the dependencies to your project:
```xml theme={null}
org.springframework.ai
spring-ai-starter-mcp-server-webmvc
org.springaicommunity
mcp-server-security
0.0.3
org.springframework.boot
spring-boot-starter-security
```
*Gradle:*
```groovy theme={null}
implementation("org.springframework.ai:spring-ai-starter-mcp-server-webmvc")
implementation("org.springaicommunity:mcp-server-security:0.0.3")
implementation("org.springframework.boot:spring-boot-starter-security")
```
Ensure that MCP server is enabled in your `application.properties`:
```properties theme={null}
spring.ai.mcp.server.name=my-cool-mcp-server
# Supported protocols: STREAMABLE, STATELESS
spring.ai.mcp.server.protocol=STREAMABLE
```
"Entites" authenticated by an API key, such as users or service accounts, are represented by `ApiKeyEntity`. The MCP
server checks a specific header for an API key, loads the entity, and validates the secret.
You can bring your own entity implementation, and your own entity repository, for specific security validations.
With that, you can configure the security for your project in the usual Spring-Security way:
```java theme={null}
@Configuration
@EnableWebSecurity
class McpServerConfiguration {
@Bean
SecurityFilterChain securityFilterChain(HttpSecurity http) throws Exception {
return http.authorizeHttpRequests(authz -> authz.anyRequest().authenticated())
.with(
McpApiKeyConfigurer.mcpServerApiKey(),
(apiKey) -> apiKey.apiKeyRepository(apiKeyRepository())
)
.build();
}
private ApiKeyEntityRepository apiKeyRepository() {
var apiKey = ApiKeyEntityImpl.builder()
.name("test api key")
.id("api01")
.secret("mycustomapikey")
.build();
return new InMemoryApiKeyEntityRepository<>(List.of(apiKey));
}
}
```
Here we use an API Key repository that stores simple keys.
Then you should be able to call your MCP server with a header `X-API-key: api01.mycustomapikey`. `X-API-key` is the
default header name for passing API keys, followed by the header value `{id}.{secret}`.
The secret is stored in bcrypt-hashed form on the server side.
The `mcpServerApiKey()` configurer offers options for changing the header name, and even dedicated APIs to extract the
API key from incoming HTTP requests.
## Improving MCP security
If you would like to learn more, head over to
the [spring-ai-community/mcp-security](https://github.com/spring-ai-community/mcp-security/) project, for documentation
and samples.
You will also find support for client-side MCP security with Spring AI and Spring Security.
Try it out with your own projects and applications, test it with the rest of the ecosystem, and help us improve it!
We are open to contributions, including feedback and issues.
In another blog post, we'll cover how to implement OAuth 2 on the client side, with the
`org.springaiframework:mcp-client-security` module.
# Prompt Caching Support in Spring AI with Anthropic Claude
Source: https://springaicommunity.mintlify.app/blog/model-providers/anthropic-prompt-caching
Large language model API costs can accumulate quickly when applications repeatedly send the same prompt content. A typical scenario: you're building a document...
Large language model API costs can accumulate quickly when applications repeatedly send the same prompt content. A typical scenario: you're building a document analyzer that includes a 3,000-token document in every request. Five questions about that document means processing 15,000 tokens of identical content at full price.
Anthropic's prompt caching addresses this by allowing you to reuse previously processed prompt segments. Spring AI provides comprehensive support through strategic caching patterns that handle cache breakpoint placement and management automatically.
In this blog post, we explain how prompt caching works, when to use it, and how Spring AI simplifies its implementation for you.
## Understanding Prompt Caching
Prompt caching allows you to mark portions of your prompt for reuse across multiple API requests. When you enable it, Anthropic caches the specified content and charges reduced rates for cached segments in subsequent requests.
### How It Works
The cache operates on exact prefix matching. Consider this sequence:
```
Request 1: [System Prompt] + [User: "Question 1"]
└─ Cached ──┘
Request 2: [System Prompt] + [User: "Question 2"]
└─ Cache Hit ─┘ (Only this part incurs full cost)
```
The system generates cache keys using cryptographic hashes of prompt content up to designated cache control points. Only requests with identical content achieve cache hits—even a single character change creates a new cache entry.
```
Request 1: "You are a helpful assistant." → Cache created
Request 2: "You are a helpful assistant." → Cache hit
Request 3: "You are a helpful assistant " → Cache miss (extra space)
Request 4: "You are a Helpful assistant." → Cache miss (capitalization)
```
On a cache miss, the system processes content at standard rates and creates a new cache entry. This is why maintaining consistent prompt templates becomes important for effective caching.
**Performance Impact:** Beyond cost savings, Anthropic reports latency reductions of up to 85% for long prompts. In their [announcement](https://www.anthropic.com/news/prompt-caching), a 100K-token book example showed response time dropping from 11.5s to 2.4s with caching enabled. Note that actual latency improvements depend on how much content you're caching and your cache hit rate.
**Cache Lifecycle:** Entries refresh on each use within the TTL window (5 minutes default, 1 hour optional). After TTL expiration, the next request creates a new cache entry.
### Cost Structure
Pricing varies significantly by model tier:
| Model | Base Input | Cache Write | Cache Read | Savings |
| --------------------- | ----------- | ------------------- | ----------- | ------- |
| **Claude Sonnet 4.5** | \$3/MTok | \$3.75/MTok (+25%) | \$0.30/MTok | **90%** |
| **Claude Sonnet 4** | \$3/MTok | \$3.75/MTok (+25%) | \$0.30/MTok | **90%** |
| **Claude Opus 4.1** | \$15/MTok | \$18.75/MTok (+25%) | \$1.50/MTok | **90%** |
| **Claude Opus 4** | \$15/MTok | \$18.75/MTok (+25%) | \$1.50/MTok | **90%** |
| **Claude Haiku 4.5** | \$1/MTok | \$1.25/MTok (+25%) | \$0.10/MTok | **90%** |
| **Claude Haiku 3.5** | \$0.80/MTok | \$1/MTok (+25%) | \$0.08/MTok | **90%** |
| **Claude Haiku 3** | \$0.25/MTok | \$0.30/MTok (+25%) | \$0.03/MTok | **90%** |
*All code examples in this blog use Claude Sonnet 4.5 pricing unless otherwise specified.*
For more on pricing, see - [Anthropic pricing on prompt caching](https://docs.claude.com/en/docs/build-with-claude/prompt-caching#pricing)
**Example calculation (Claude 3.5 Sonnet, 5,000 tokens):**
* First request: 5,000 tokens × $3.75/M = **$0.01875\*\* (cache write)
* Subsequent requests: 5,000 tokens × $0.30/M = **$0.00150\*\* (cache read)
* **Savings:** 90% reduction on cached content
* **Breakeven:** 2nd request (the 25% write premium is recovered immediately)
### Requirements and Limitations
**Minimum token thresholds vary by model:**
| Model | Minimum Cacheable Tokens |
| -------------------------------------------------------------------- | ------------------------ |
| Claude Sonnet 4.5, , Claude Sonnet 4, Claude Opus 4.1, Claude Opus 4 | 1,024 |
| Claude Haiku 3.5, Claude Haiku 3 | 2,048 |
| Claude Haiku 4.5 | **4,096** |
Prompts below these thresholds cannot be cached, even when you mark them with cache control directives. Note that Claude Haiku 4.5 requires significantly more tokens (4,096) compared to other models.
For more on this, see [Anthropic's cacheable prompt length limitations](https://docs.claude.com/en/docs/build-with-claude/prompt-caching#cache-limitations).
**Additional constraints:**
* Maximum 4 cache breakpoints per request
* Cache TTL: 5 minutes default, 1 hour optional (at higher write cost)
* Cache refreshes on each use within TTL window
* Cache entries become available after the first response begins (not available for concurrent parallel requests)
## Cache Hierarchy and Cascade Invalidation
Anthropic processes request components in a specific order, and this order determines how cache invalidation works.
```
┌─────────────────────────────────────────┐
│ Request Processing Order: │
│ │
│ 1. Tools │
│ ↓ │
│ 2. System Message │
│ ↓ │
│ 3. Message History │
└─────────────────────────────────────────┘
```
Changes cascade downward through this hierarchy:
```
┌──────────────────────────────────────────────────────┐
│ Cascade Invalidation: │
│ │
│ Change Tools → Invalidates: Tools, System, Msgs │
│ Change System → Invalidates: System, Msgs │
│ Change Messages → Invalidates: Msgs only │
└──────────────────────────────────────────────────────┘
```
Understanding this behavior is essential when choosing your caching strategy. Changes to components higher in the hierarchy invalidate all downstream caches, which directly impacts your cache hit rates.
## Spring AI Cache Strategies
Rather than requiring you to manually place cache breakpoints (which can be error-prone and tedious), Spring AI provides five strategic patterns through the `AnthropicCacheStrategy` enum. Each strategy handles cache control directive placement automatically while respecting Anthropic's 4-breakpoint limit.
### Strategy Overview
| Strategy | Breakpoints | Cached Content | Typical Use Case |
| ---------------------- | ----------- | ----------------- | ----------------------------------- |
| `NONE` | 0 | Nothing | One-off requests, testing |
| `SYSTEM_ONLY` | 1 | System message | Stable system prompts, \<20 tools |
| `TOOLS_ONLY` | 1 | Tool definitions | Large tools, dynamic system prompts |
| `SYSTEM_AND_TOOLS` | 2 | Tools + System | 20+ tools, both stable |
| `CONVERSATION_HISTORY` | 1-4 | Full conversation | Multi-turn conversations |
Let's take a look at each strategy with practical examples.
## SYSTEM\_ONLY Strategy
This strategy caches the system message content. Since tools appear before the system message in Anthropic's request hierarchy (Tools → System → Messages), they automatically become part of the cache prefix when you place a cache breakpoint on the system message.
**Important:** Changing any tool definition will invalidate the system cache due to the cache hierarchy.
```java theme={null}
String systemPrompt = """
You are an expert software architect specializing in distributed systems.
You have deep knowledge of microservices, event-driven architecture, and cloud-native patterns.
When analyzing systems, consider scalability, resilience, and maintainability.
[... additional context ...]
""";
ChatResponse response = chatModel.call(
new Prompt(
List.of(
new SystemMessage(systemPrompt),
new UserMessage("What is microservices architecture?")
),
AnthropicChatOptions.builder()
.model(AnthropicApi.ChatModel.CLAUDE_3_5_SONNET)
.cacheOptions(AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.SYSTEM_ONLY)
.build())
.maxTokens(500)
.build()
)
);
// Access cache metrics
AnthropicApi.Usage usage = (AnthropicApi.Usage) response.getMetadata()
.getUsage().getNativeUsage();
if (usage != null) {
System.out.println("Cache creation: " + usage.cacheCreationInputTokens());
System.out.println("Cache read: " + usage.cacheReadInputTokens());
}
```
On the first request, `cacheCreationInputTokens` will be greater than zero and `cacheReadInputTokens` will be zero. Subsequent requests with the same system prompt will show zero for `cacheCreationInputTokens` and a positive value for `cacheReadInputTokens`. This is how you can verify that caching is working as expected in your application.
Use this strategy when your system prompt is large (meeting the minimum token threshold) and stable, but user questions vary.
## TOOLS\_ONLY Strategy
This strategy caches tool definitions while processing the system message fresh on each request. The use case becomes clear in multi-tenant scenarios where tools are shared but system prompts need customization.
Consider a SaaS application serving multiple organizations:
```java theme={null}
@Service
public class MultiTenantAIService {
private final List sharedTools = List.of(
weatherTool, // 500 tokens
calendarTool, // 800 tokens
emailTool, // 700 tokens
analyticsTool, // 600 tokens
reportingTool, // 900 tokens
// ... 15 more tools totaling 5,000+ tokens
);
public String handleRequest(String tenantId, String userQuery) {
TenantConfig config = tenantRepository.findById(tenantId);
// Each tenant requires a unique system prompt
String systemPrompt = """
You are %s's AI assistant.
Company values: [custom data]
Brand voice: [custom data]
Compliance requirements: [custom data]
""";
ChatResponse response = chatModel.call(
new Prompt(
List.of(
new SystemMessage(systemPrompt),
new UserMessage(userQuery)
),
AnthropicChatOptions.builder()
.model(AnthropicApi.ChatModel.CLAUDE_3_5_SONNET)
.cacheOptions(AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.TOOLS_ONLY)
.build())
.toolCallbacks(sharedTools)
.maxTokens(800)
.build()
)
);
return response.getResult().getOutput().getText();
}
}
```
Here's what happens:
* **First request (any tenant)**: Tools cached at 1.25x cost
* **All subsequent requests (all tenants)**: Tools read from cache at 0.1x cost
* **Each tenant's system prompt**: Processed fresh at 1.0x cost (by design)
All tenants share the same cached tool definitions, while each receives their customized system prompt. For the 5,000-token tool set, this means paying `$0.01875` once to create the cache, then `$0.0015` per request for cache reads—regardless of which tenant is making the request.
## SYSTEM\_AND\_TOOLS Strategy
This strategy creates two independent cache breakpoints: one for tools (breakpoint 1) and one for the system message (breakpoint 2). This separation matters when you have more than 20 tools or when you need deterministic caching of both components.
The key advantage: changing the system message does not invalidate the tool cache.
```java theme={null}
ChatResponse response = chatModel.call(
new Prompt(
List.of(
new SystemMessage(systemPrompt),
new UserMessage(userQuery)
),
AnthropicChatOptions.builder()
.model(AnthropicApi.ChatModel.CLAUDE_3_5_SONNET)
.cacheOptions(AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.SYSTEM_AND_TOOLS)
.build())
.toolCallbacks(toolCallbacks)
.maxTokens(500)
.build()
)
);
```
The cache keys work as follows:
* **Breakpoint 1 (tools)**: `hash(tools)`
* **Breakpoint 2 (system)**: `hash(tools + system)`
**Cascade Behavior:**
* **System changes only:** Tool cache (breakpoint 1) remains valid, system cache (breakpoint 2) invalidated
* **Tool changes:** Both caches invalidated
This makes SYSTEM\_AND\_TOOLS ideal when your system prompt changes more frequently than your tools, allowing efficient reuse of the tool cache.
## CONVERSATION\_HISTORY Strategy
For multi-turn conversations, this strategy caches the entire conversation history incrementally. Spring AI places a cache breakpoint on the last user message in the conversation history. This is particularly useful when building conversational AI applications (such as chatbots, virtual assistants, and customer support systems).
```java theme={null}
ChatClient chatClient = ChatClient.builder(chatModel)
.defaultSystem("You are a personalized career counselor with 20 years of experience...")
.defaultAdvisors(MessageChatMemoryAdvisor.builder(chatMemory)
.conversationId(conversationId)
.build())
.build();
String response = chatClient.prompt()
.user("What career advice would you give me based on our conversation?")
.options(AnthropicChatOptions.builder()
.model(AnthropicApi.ChatModel.CLAUDE_3_5_SONNET)
.cacheOptions(AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.CONVERSATION_HISTORY)
.build())
.maxTokens(500)
.build())
.call()
.content();
```
The cache grows incrementally as the conversation progresses:
```
Turn 1: Cache [U1]
Turn 2: Reuse [U1], cache [U1 + A1 + U2]
Turn 3: Reuse [U1 + A1 + U2], cache [U1 + A1 + U2 + A2 + U3]
Turn 4: Reuse [U1 + A1 + U2 + A2 + U3], cache [full history + U4]
```
By turn 10 in a conversation, you might have 20,000 tokens of history cached, paying just 10% of the normal cost for that context on each subsequent turn.
**Critical Requirement: Tool and System Stability**
When using `CONVERSATION_HISTORY`, both tools and system prompts must remain stable throughout the conversation. Changes to either invalidate the entire conversation cache.
## Example: Partnership Agreement Analysis
Here's a complete example showing cache efficiency for multi-question document analysis:
```java theme={null}
@Service
public class ContractAnalyzer {
private final AnthropicChatModel chatModel;
private final PdfExtractor pdfExtractor;
public AnalysisReport analyzeAgreement(String agreementPdf) {
// Extract text from PDF (typically 2,000-5,000 tokens)
String agreementText = pdfExtractor.extract(agreementPdf);
String systemPrompt = """
You are an expert business analyst specializing in partnership agreements.
Analyze the following partnership agreement and provide insights about
collaboration terms, value propositions, and strategic opportunities.
AGREEMENT:
%s
""".formatted(agreementText);
String[] questions = {
"What are the key collaboration opportunities outlined in this agreement?",
"Summarize the revenue sharing and financial arrangements.",
"What intellectual property rights and licensing terms are defined?",
"Identify the strategic value propositions for both parties.",
"What are the performance milestones and success metrics?"
};
AnalysisReport report = new AnalysisReport();
AnthropicChatOptions options = AnthropicChatOptions.builder()
.model(AnthropicApi.ChatModel.CLAUDE_3_5_SONNET)
.cacheOptions(AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.SYSTEM_ONLY)
.messageTypeTtl(MessageType.SYSTEM, AnthropicCacheTtl.ONE_HOUR)
.build())
.maxTokens(1000)
.build();
for (int i = 0; i < questions.length; i++) {
ChatResponse response = chatModel.call(
new Prompt(
List.of(
new SystemMessage(systemPrompt),
new UserMessage(questions[i])
),
options
)
);
String answer = response.getResult().getOutput().getText();
report.addSection(questions[i], answer);
// Log cache performance
AnthropicApi.Usage usage = (AnthropicApi.Usage)
response.getMetadata().getUsage().getNativeUsage();
if (usage != null) {
if (i == 0) {
logger.info("First question - Cache created: {} tokens",
usage.cacheCreationInputTokens());
} else {
logger.info("Question {} - Cache read: {} tokens",
i + 1, usage.cacheReadInputTokens());
}
}
}
return report;
}
}
```
With a 3,500-token system prompt (agreement + instructions) using Claude 3.5 Sonnet:
* **First question**: 3,500 tokens × $3.75/M = $0.013 (cache write)
* **Questions 2-5**: 3,500 tokens × $0.30/M = $0.001 (cache read) each
* **Total cached content cost**: $0.013 + (4 × $0.001) = \$0.017
* **Without caching**: 5 × (3,500 tokens × $3.00/M) = $0.053
This represents a 68% cost reduction for the cached system prompt portion. The actual total savings will be lower when you factor in the user question tokens and output tokens (which are not cached), but the reduction becomes more significant with more questions or larger documents.
## Getting Started
**Note:** Prompt caching support is available in Spring AI `1.1.0` and later. Try it with the latest `1.1.0-SNAPSHOT` version.
Add the Spring AI Anthropic starter to your project:
```xml theme={null}
org.springframework.ai
spring-ai-anthropic-spring-boot-starter
```
Configure your API key in your application properties:
```properties theme={null}
spring.ai.anthropic.api-key=${ANTHROPIC_API_KEY}
```
Inject and use in your application:
```java theme={null}
@Autowired
private AnthropicChatModel chatModel;
// Start using caching strategies immediately
```
## Advanced Configuration Options
### Extended Cache TTL
The default cache TTL is 5 minutes. For scenarios where requests arrive less frequently, you can configure a 1-hour cache:
```java theme={null}
AnthropicChatOptions options = AnthropicChatOptions.builder()
.model(AnthropicApi.ChatModel.CLAUDE_3_5_SONNET)
.cacheOptions(AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.SYSTEM_ONLY)
.messageTypeTtl(MessageType.SYSTEM, AnthropicCacheTtl.ONE_HOUR)
.build())
.maxTokens(500)
.build();
```
Spring AI automatically adds the required beta header (`anthropic-beta: extended-cache-ttl-2025-04-11`) when you configure 1-hour TTL.
**When to use each TTL:**
* **5 minutes (default):** Real-time conversations, frequently updated content
* **1 hour:** Infrequent requests (>5 min apart), stable reference materials, lower traffic
**Trade-off:** 1-hour cache writes cost **2x** vs 5-minute writes ($6/M vs $3.75/M for Claude 3.5 Sonnet). Evaluate your application's request patterns and stability requirements to determine which TTL makes sense.
### Content Length Filtering
You can set minimum content lengths per message type to optimize breakpoint usage:
```java theme={null}
AnthropicCacheOptions cache = AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.CONVERSATION_HISTORY)
.messageTypeMinContentLength(MessageType.SYSTEM, 1024)
.messageTypeMinContentLength(MessageType.USER, 512)
.messageTypeMinContentLength(MessageType.ASSISTANT, 512)
.build();
```
For precise token counting, you can provide a custom length function:
```java theme={null}
AnthropicCacheOptions cache = AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.CONVERSATION_HISTORY)
.contentLengthFunction(text -> customTokenCounter.count(text))
.build();
```
By default, Spring AI uses string length as a proxy for token count, but for production scenarios, you might want to consider injecting a proper token counter.
## Implementation Details
For those interested in internals, here's how Spring AI handles cache management:
```
┌─────────────────────────────────────────────────────────┐
│ Request Flow: │
│ │
│ Application │
│ ↓ │
│ AnthropicChatModel │
│ ↓ │
│ CacheEligibilityResolver │
│ (created from strategy) │
│ ↓ │
│ For each component: │
│ - Check strategy eligibility │
│ - Verify minimum content length │
│ - Confirm breakpoint availability (<4) │
│ - Add cache_control if eligible │
│ ↓ │
│ Build request with cache markers │
│ ↓ │
│ Add beta headers if needed (1h TTL) │
│ ↓ │
│ Anthropic API │
│ ↓ │
│ Response with cache metrics │
└─────────────────────────────────────────────────────────┘
```
The `CacheEligibilityResolver` determines whether each message or tool qualifies for caching based on the chosen strategy, message type eligibility, content length requirements, and available breakpoints. The `CacheBreakpointTracker` enforces Anthropic's 4-breakpoint limit with thread-safe tracking per request.
For `CONVERSATION_HISTORY`, Spring AI uses aggregate eligibility checking—it considers the combined content of all message types (user, assistant, tool) within the last \~20 content blocks when determining cache eligibility. This prevents short user questions (such as "Tell me more") from blocking cache creation when there are substantial assistant responses in the conversation history.
## Practical Considerations
### When Caching Doesn't Help
Avoid caching when:
* Content changes frequently (cache miss rate >50%)
* Prompts are below minimum token thresholds for your model
* Making one-off requests with no reuse patterns
* Tools or system prompts change more often than content is reused
### Strategy Anti-Patterns
Avoid these common mistakes:
* **Don't use SYSTEM\_ONLY** if your system prompt changes frequently—you'll pay cache write costs without getting cache hits
* **Don't use TOOLS\_ONLY** if your tools change frequently—you'll pay cache write costs without getting cache hits. Note that SYSTEM\_ONLY won't help either when tools change frequently, since tool changes invalidate the system cache
* **Don't use CONVERSATION\_HISTORY** if you can't guarantee tool and system stability—changes invalidate the entire conversation cache
* **Don't use SYSTEM\_AND\_TOOLS** if you only have a few small tools (\<20)—SYSTEM\_ONLY's implicit caching is sufficient
### Streaming Support
Caching works seamlessly with both streaming and non-streaming responses. Cache metrics appear in the final response chunk when using streaming. There is no difference in cache behavior between the two modes.
## Conclusion
Prompt caching in Anthropic Claude provides significant cost and latency benefits for applications with reusable prompt content. Spring AI's strategic approach simplifies implementation by automatically handling cache breakpoint placement, breakpoint limits, and TTL configuration.
The five caching strategies cover common usage patterns, from simple system prompt caching to complex multi-turn conversations. For most applications, selecting the appropriate strategy based on content stability patterns is sufficient—Spring AI handles the implementation details.
For additional information, see the [Spring AI Anthropic documentation](https://docs.spring.io/spring-ai/reference/api/chat/anthropic-chat.html#_prompt_caching) and [Anthropic's prompt caching guide](https://docs.claude.com/en/docs/build-with-claude/prompt-caching).
# Introducing Spring AI Amazon Bedrock Nova Integration via Converse API
Source: https://springaicommunity.mintlify.app/blog/model-providers/bedrock-nova
The [Amazon Bedrock Nova](https://docs.aws.amazon.com/nova/latest/userguide/what-is-nova.html) models represent a new generation of foundation models supporting...
The [Amazon Bedrock Nova](https://docs.aws.amazon.com/nova/latest/userguide/what-is-nova.html) models represent a new generation of foundation models supporting a broad range of use cases, from text and image understanding to video-to-text analysis.
With the [Spring AI Bedrock Converse API](https://docs.spring.io/spring-ai/reference/api/chat/bedrock-converse.html) integration, developers can seamlessly connect to these advanced Nova models and build sophisticated conversational applications with minimal effort.
![]() This blog post introduces the key features of Amazon Nova models, demonstrates their integration with Spring AI's Bedrock Converse API, and provides practical examples for text, image, video, document processing, and function calling.
## What are Amazon Nova Models?
Amazon Nova offers three tiers of models—Nova Pro, Nova Lite, and Nova Micro—to address different performance and cost requirements:
| Specification | Nova Pro | Nova Lite | Nova Micro |
| ------------- | -------------------------- | -------------------------- | ---------------------- |
| Modalities | Text, Image, Video-to-text | Text, Image, Video-to-text | Text |
| Model ID | amazon.nova-pro-v1:0 | amazon.nova-lite-v1:0 | amazon.nova-micro-v1:0 |
| Max tokens | 300K | 300K | 128K |
Nova Pro and Lite support multimodal capabilities, including text, image, and video inputs, while Nova Micro is optimized for text-only interactions at a lower cost.
## Setting Up the Integration
### Prerequisites
1. **AWS Configuration**: You need:
* AWS credentials with access to Amazon Bedrock
* Necessary permissions to use Nova models
* Models enabled in the [Amazon Bedrock console](https://us-east-1.console.aws.amazon.com/bedrock/home?region=us-east-1#/modelaccess)
2. **Spring AI Dependency**:
Add the Spring AI Bedrock Converse starter to your Spring Boot project:
**Maven**:
```xml theme={null}
org.springframework.ai
spring-ai-bedrock-converse-spring-boot-starter
```
**Gradle**:
```groovy theme={null}
dependencies {
implementation 'org.springframework.ai:spring-ai-bedrock-converse-spring-boot-starter'
}
```
3. **Application Configuration**:
Configure `application.properties` for Amazon Bedrock:
```properties theme={null}
spring.ai.bedrock.aws.region=us-east-1
spring.ai.bedrock.aws.access-key=${AWS_ACCESS_KEY_ID}
spring.ai.bedrock.aws.secret-key=${AWS_SECRET_ACCESS_KEY}
spring.ai.bedrock.aws.session-token=${AWS_SESSION_TOKEN}
spring.ai.bedrock.converse.chat.options.model=amazon.nova-pro-v1:0
spring.ai.bedrock.converse.chat.options.temperature=0.8
spring.ai.bedrock.converse.chat.options.max-tokens=1000
```
For more details, refer to the [Chat Properties](https://docs.spring.io/spring-ai/reference/api/chat/bedrock-converse.html#_chat_properties) documentation.
## Key Features of the Bedrock Nova Integration
### 1. Text Completion
Text-based chat completion is straightforward:
```java theme={null}
String response = ChatClient.create(chatModel)
.prompt("Tell me a joke about AI.")
.call()
.content();
```
### 2. Multimodal Input
Nova Pro and Lite support multimodal inputs, enabling text and visual data processing. Spring AI provides a portable [Multimodal API](https://docs.spring.io/spring-ai/reference/api/multimodality.html) that supports Bedrock Nova models.
#### Text + Image
Nova Pro and Lite support multiple [image modalities](https://docs.aws.amazon.com/nova/latest/userguide/modalities-image.html). These models can analyze images, answer questions about them, classify them, and generate summaries based on provided instructions. They support base64-encoded images in `image/jpeg`, `image/png`, `image/gif`, and `image/webp` formats.
Example combining user text with an image:
```java theme={null}
String response = ChatClient.create(chatModel)
.prompt()
.user(u -> u.text("Explain what do you see on this picture?")
.media(Media.Format.IMAGE_PNG, new ClassPathResource("/test.png")))
.call()
.content();
```
This code processes the `test.png` image:
![]() with the text message `"Explain what do you see on this picture?"` and generates a response like:
> The image shows a close-up view of a wire fruit basket containing several pieces of fruit...
#### Text + Video
Amazon Nova Pro/Lite models support a single [video modality](https://docs.aws.amazon.com/nova/latest/userguide/modalities-video.html) in the payload, provided either in base64 format or through an Amazon S3 URI.
Supported video formats include `video/x-matros`, `video/quicktime`, `video/mp4`, `video/webm`, `video/x-flv`, `video/mpeg`, `video/x-ms-wmv`, and `image/3gpp`.
Example combining user text with a video:
```java theme={null}
String response = ChatClient.create(chatModel)
.prompt()
.user(u -> u.text("Explain what do you see in this video?")
.media(Media.Format.VIDEO_MP4, new ClassPathResource("/test.video.mp4")))
.call()
.content();
```
This code processes the `test.video.mp4` video
![]() with the text message `"Explain what do you see in this video?"` and generates a response like:
> The video shows a group of baby chickens, also known as chicks, huddled together on a surface ...
#### Text + Document
Nova Pro/Lite supports [document modalities](https://docs.aws.amazon.com/nova/latest/userguide/modalities-document.html) in two variants:
* Text document types (txt, csv, html, md, etc.) for text understanding and answering questions based on textual elements
* Media document types (pdf, docx, xlsx) for vision-based understanding, such as analyzing charts and graphs
Example combining user text with a media document:
```java theme={null}
String response = ChatClient.create(chatModel)
.prompt()
.user(u -> u.text(
"You are a very professional document summarization specialist. Please summarize the given document.")
.media(Media.Format.DOC_PDF, new ClassPathResource("/spring-ai-reference-overview.pdf")))
.call()
.content();
```
This code processes the `spring-ai-reference-overview.pdf` document:
![]() with the text message and generates a response like:
> **Introduction:**
>
> * Spring AI is designed to simplify the development of applications with artificial intelligence (AI) capabilities, aiming to avoid unnecessary complexity....
### 3. Function Calling
Nova models support [Tool/Function Calling](https://docs.spring.io/spring-ai/reference/api/functions.html) for integration with external tools.
![]() #### Define a Function
```java theme={null}
@Bean
@Description("Get the weather in a location. Return temperature in Celsius or Fahrenheit.")
public Function weatherFunction() {
return new MockWeatherService();
}
```
#### Use the Function in a Chat Prompt
```java theme={null}
String response = ChatClient.create(this.chatModel)
.prompt("What's the weather like in Boston?")
.function("weatherFunction") // bean name
.inputType(WeatherRequest.class)
.call()
.content();
```
## Resources
#### Getting Started
* [Spring AI Documentation](https://docs.spring.io/spring-ai/reference/index.html) - Comprehensive guide to Spring AI
* [Spring AI Bedrock Converse API Guide](https://docs.spring.io/spring-ai/reference/api/chat/bedrock-converse.html) - Detailed API documentation
#### Amazon Bedrock Resources
* [Amazon Bedrock Nova Documentation](https://docs.aws.amazon.com/nova/latest/userguide/what-is-nova.html) - Official Nova models documentation
* [Amazon Bedrock Console](https://us-east-1.console.aws.amazon.com/bedrock/home) - Manage and monitor your Bedrock resources
* [Nova Model Capabilities](https://docs.aws.amazon.com/bedrock/latest/userguide/model-parameters.html) - Detailed information about Nova model parameters and capabilities
#### Code Examples
* [Spring AI Bedrock Nova Demo](https://github.com/tzolov/spring-ai-bedrock-nova-demo) - Complete example project showcasing integration features
* [BedrockNovaChatClientIT.java](https://github.com/spring-projects/spring-ai/blob/main/models/spring-ai-bedrock-converse/src/test/java/org/springframework/ai/bedrock/converse/client/BedrockNovaChatClientIT.java) - Integration test examples
* [Spring AI Samples Repository](https://github.com/spring-projects/spring-ai/tree/main/spring-ai-samples) - Additional code samples and use cases
## Tanzu AI Server
[VMware Tanzu Platform 10](https://blogs.vmware.com/tanzu/broadcom-announces-the-general-availability-of-vmware-tanzu-platform-10-making-it-easier-for-customers-to-build-and-launch-new-applications-in-the-private-cloud/) integrates Amazon Bedrock Nova models through the VMware Tanzu AI Server, powered by Spring AI.
This integration provides:
* **Enterprise-Grade AI Deployment**: Production-ready solution for deploying AI applications within your VMware Tanzu environment
* **Simplified Model Access**: Streamlined access to Amazon Bedrock Nova models through a unified interface
* **Security and Governance**: Enterprise-level security controls and governance features
* **Scalable Infrastructure**: Built on Spring AI, the integration supports for scalable deployment of AI applications while maintaining high performance
For more information about deploying AI applications with Tanzu AI Server, visit the [VMware Tanzu AI documentation](https://www.vmware.com/solutions/app-platform/ai).
## Conclusion
The integration of Spring AI with Amazon Bedrock Nova models via the Converse API enables powerful capabilities for building advanced conversational applications. Nova Pro and Lite provide comprehensive tools for developing multimodal experiences across text, images, videos, and documents. Function calling extends these capabilities further by enabling interaction with external tools and services.
Start building advanced AI applications with Nova models and Spring AI today!
# AWS Bedrock Prompt Caching Support in Spring AI
Source: https://springaicommunity.mintlify.app/blog/model-providers/bedrock-prompt-caching
In our [previous blog post about Anthropic prompt caching](https://spring.io/blog/2025/10/27/spring-ai-anthropic-prompt-caching-blog), we explored how prompt...
In our [previous blog post about Anthropic prompt caching](https://spring.io/blog/2025/10/27/spring-ai-anthropic-prompt-caching-blog), we explored how prompt caching dramatically reduces API costs and latency by reusing previously processed prompt content. We introduced Spring AI's five strategic caching patterns for Anthropic Claude models and showed how they automatically handle cache breakpoint placement while respecting the 4-breakpoint limit.
AWS Bedrock brings prompt caching to a broader ecosystem—supporting both Claude models (accessed via Bedrock) and Amazon's own Nova family. If you're considering Bedrock or already using it, you'll find the same Spring AI caching strategies apply with a few key differences.
In this blog post, we explain what's different about prompt caching in AWS Bedrock compared to Anthropic's direct API and how Spring AI maintains consistent patterns across both providers.
## What AWS Bedrock Adds
AWS Bedrock extends prompt caching beyond Claude to include Amazon Nova models:
**Claude models** (via Bedrock):
* Claude 3 Opus 4.1, Opus 4, Sonnet 4.5, Sonnet 4, Haiku 4.5
* Claude 3.7 Sonnet, 3.5 Haiku
* Full caching support including tool definitions
**Amazon Nova models**:
* Nova Micro, Lite, Pro, Premier
* System and conversation caching support only
For complete model details, see [AWS Bedrock supported models](https://docs.aws.amazon.com/bedrock/latest/userguide/prompt-caching.html#prompt-caching-models).
## Key Differences from Anthropic Direct API
While the core caching concepts remain the same (as covered in our [previous blog](https://spring.io/blog/2025/10/27/spring-ai-anthropic-prompt-caching-blog)), AWS Bedrock has several differences worth understanding.
### Fixed 5-Minute Cache TTL
AWS Bedrock uses a fixed 5-minute TTL with no configuration options, while Anthropic's direct API offers optional 1-hour caching.
```java theme={null}
// Anthropic direct API: optional TTL configuration
AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.SYSTEM_ONLY)
.messageTypeTtl(MessageType.SYSTEM, AnthropicCacheTtl.ONE_HOUR)
.build()
// AWS Bedrock: always 5 minutes
BedrockCacheOptions.builder()
.strategy(BedrockCacheStrategy.SYSTEM_ONLY)
.build()
```
For high-frequency workloads (requests every few seconds or minutes), the 5-minute TTL keeps the cache warm. For applications with requests spaced 5-30 minutes apart, cache entries may expire between requests.
### Tool Caching Not Supported on Nova
Amazon Nova models do not support tool caching. Attempting to use `TOOLS_ONLY` or `SYSTEM_AND_TOOLS` strategies with Nova throws an exception.
```java theme={null}
// Works with Claude models
BedrockChatOptions.builder()
.model("anthropic.claude-sonnet-4-5-20250929-v1:0")
.cacheOptions(BedrockCacheOptions.builder()
.strategy(BedrockCacheStrategy.SYSTEM_AND_TOOLS)
.build())
.toolCallbacks(tools)
.build()
// Throws exception with Nova models
BedrockChatOptions.builder()
.model("us.amazon.nova-pro-v1:0")
.cacheOptions(BedrockCacheOptions.builder()
.strategy(BedrockCacheStrategy.TOOLS_ONLY)
.build())
.toolCallbacks(tools)
.build()
// Use SYSTEM_ONLY for Nova
BedrockChatOptions.builder()
.model("us.amazon.nova-pro-v1:0")
.cacheOptions(BedrockCacheOptions.builder()
.strategy(BedrockCacheStrategy.SYSTEM_ONLY)
.build())
.build()
```
### Model-Specific Token Thresholds
| Model | Minimum Tokens per Checkpoint |
| -------------------------------------------------------------- | ----------------------------- |
| Claude 3.7 Sonnet, 3.5 Sonnet v2, Opus 4, Sonnet 4, Sonnet 4.5 | 1,024 |
| Claude 3.5 Haiku | 2,048 |
| Claude Haiku 4.5 | 4,096 |
| Amazon Nova (all variants) | 1,000 |
See [Bedrock token limits documentation](https://docs.aws.amazon.com/bedrock/latest/userguide/prompt-caching.html#prompt-caching-models) for details.
### Cache Metrics Naming
| Metric | Anthropic Direct | AWS Bedrock |
| ---------------------- | -------------------------- | ----------------------- |
| Creating a cache entry | `cacheCreationInputTokens` | `cacheWriteInputTokens` |
| Reading from cache | `cacheReadInputTokens` | `cacheReadInputTokens` |
## Same Spring AI Patterns Across Providers
Spring AI uses identical caching strategies across both providers:
```java theme={null}
BedrockCacheStrategy.SYSTEM_ONLY ←→ AnthropicCacheStrategy.SYSTEM_ONLY
BedrockCacheStrategy.TOOLS_ONLY ←→ AnthropicCacheStrategy.TOOLS_ONLY
BedrockCacheStrategy.SYSTEM_AND_TOOLS ←→ AnthropicCacheStrategy.SYSTEM_AND_TOOLS
BedrockCacheStrategy.CONVERSATION_HISTORY ←→ AnthropicCacheStrategy.CONVERSATION_HISTORY
```
Let's take a look at how similar the code is:
```java theme={null}
// Anthropic direct API
ChatResponse response = anthropicChatModel.call(
new Prompt(
List.of(new SystemMessage(systemPrompt), new UserMessage(userQuery)),
AnthropicChatOptions.builder()
.model(AnthropicApi.ChatModel.CLAUDE_4_5_SONNET)
.cacheOptions(AnthropicCacheOptions.builder()
.strategy(AnthropicCacheStrategy.SYSTEM_ONLY)
.build())
.maxTokens(500)
.build()
)
);
// AWS Bedrock (nearly identical)
ChatResponse response = bedrockChatModel.call(
new Prompt(
List.of(new SystemMessage(systemPrompt), new UserMessage(userQuery)),
BedrockChatOptions.builder()
.model("anthropic.claude-sonnet-4-5-20250929-v1:0")
.cacheOptions(BedrockCacheOptions.builder()
.strategy(BedrockCacheStrategy.SYSTEM_ONLY)
.build())
.maxTokens(500)
.build()
)
);
```
The only differences: the chat model instance, options class, and model identifier format.
## Provider Characteristics at a Glance
| Feature | AWS Bedrock | Anthropic Direct |
| ----------------- | ----------------------------------------------- | -------------------------------------------------- |
| **Cache TTL** | 5 minutes (fixed) | 5 minutes (default), 1 hour (optional) |
| **Models** | Claude + Nova | Claude only |
| **Tool Caching** | Claude only | All Claude models |
| **Token Metrics** | `cacheWriteInputTokens`, `cacheReadInputTokens` | `cacheCreationInputTokens`, `cacheReadInputTokens` |
| **Pricing** | Varies by region/model | Published per-model |
| **Cost Pattern** | \~25% write premium, \~90% read savings | 25% write premium, 90% read savings |
## Example: Document Analysis with Caching
Here's a practical example showing cache effectiveness:
```java theme={null}
@Service
public class ContractAnalyzer {
private final BedrockProxyChatModel chatModel;
private final DocumentExtractor documentExtractor;
public AnalysisReport analyzeContract(String contractId) {
String contractText = documentExtractor.extract(contractId);
String systemPrompt = """
You are an expert legal analyst specializing in commercial contracts.
Analyze the following contract and provide precise insights about
terms, obligations, risks, and opportunities:
CONTRACT:
%s
""".formatted(contractText);
String[] questions = {
"What are the key legal clauses and penalties?",
"Summarize the payment terms and financial obligations.",
"What intellectual property rights are defined?",
"Identify potential compliance risks.",
"What are the performance milestones?"
};
AnalysisReport report = new AnalysisReport();
BedrockChatOptions options = BedrockChatOptions.builder()
.model("anthropic.claude-sonnet-4-5-20250929-v1:0")
.cacheOptions(BedrockCacheOptions.builder()
.strategy(BedrockCacheStrategy.SYSTEM_ONLY)
.build())
.maxTokens(1000)
.build();
for (int i = 0; i < questions.length; i++) {
ChatResponse response = chatModel.call(
new Prompt(
List.of(new SystemMessage(systemPrompt), new UserMessage(questions[i])),
options
)
);
report.addSection(questions[i], response.getResult().getOutput().getText());
logCacheMetrics(response, i);
}
return report;
}
private void logCacheMetrics(ChatResponse response, int questionNum) {
Integer cacheWrite = (Integer) response.getMetadata()
.getMetadata().get("cacheWriteInputTokens");
Integer cacheRead = (Integer) response.getMetadata()
.getMetadata().get("cacheReadInputTokens");
if (questionNum == 0 && cacheWrite != null) {
logger.info("Cache created: {} tokens", cacheWrite);
} else if (cacheRead != null && cacheRead > 0) {
logger.info("Cache hit: {} tokens", cacheRead);
}
}
}
```
AWS Bedrock provides cache metrics through the response metadata:
First request: `cacheWriteInputTokens` > 0, `cacheReadInputTokens` = 0
Subsequent requests (within TTL): `cacheWriteInputTokens` = 0, `cacheReadInputTokens` > 0
With a 3,500-token system prompt, this yields approximately 65% cost reduction on cached content (first question pays \~1.25x, subsequent questions pay \~0.10x).
## Using Different Models on Bedrock
```java theme={null}
@Service
public class MultiModelService {
// Nova: System prompt caching
public String analyzeWithNova(String document, String query) {
return chatClient.prompt()
.system("You are an expert analyst. Context: " + document)
.user(query)
.options(BedrockChatOptions.builder()
.model("us.amazon.nova-pro-v1:0")
.cacheOptions(BedrockCacheOptions.builder()
.strategy(BedrockCacheStrategy.SYSTEM_ONLY)
.build())
.maxTokens(500)
.build())
.call()
.content();
}
// Claude: System + tool caching
public String analyzeWithTools(String document, String query,
List tools) {
return chatClient.prompt()
.system("You are an expert analyst. Context: " + document)
.user(query)
.options(BedrockChatOptions.builder()
.model("anthropic.claude-sonnet-4-5-20250929-v1:0")
.cacheOptions(BedrockCacheOptions.builder()
.strategy(BedrockCacheStrategy.SYSTEM_AND_TOOLS)
.build())
.toolCallbacks(tools)
.maxTokens(500)
.build())
.call()
.content();
}
}
```
## Getting Started
Add the Spring AI Bedrock Converse starter:
**Note:** AWS Bedrock Prompt caching support is available in Spring AI `1.1.0` and later. Try it with the latest `1.1.0-SNAPSHOT` version.
```xml theme={null}
org.springframework.ai
spring-ai-starter-model-bedrock-converse
```
Configure AWS credentials:
```properties theme={null}
spring.ai.bedrock.aws.region=us-east-1
spring.ai.bedrock.aws.access-key=${AWS_ACCESS_KEY_ID}
spring.ai.bedrock.aws.secret-key=${AWS_SECRET_ACCESS_KEY}
```
You can then start using prompt caching via AWS Bedrock as shown in the examples above.
## Strategy Selection Reference
| Strategy | Use When | Claude | Nova |
| ---------------------- | ---------------------------------- | ------ | ---- |
| `SYSTEM_ONLY` | Large stable system prompt | Yes | Yes |
| `TOOLS_ONLY` | Large stable tools, dynamic system | Yes | No |
| `SYSTEM_AND_TOOLS` | Both large and stable | Yes | No |
| `CONVERSATION_HISTORY` | Multi-turn conversations | Yes | Yes |
| `NONE` | Disable caching explicitly | Yes | Yes |
For detailed strategy explanations, cache hierarchy, and cascade invalidation patterns, see our [Anthropic prompt caching blog post](https://spring.io/blog/2025/10/27/spring-ai-anthropic-prompt-caching-blog). These concepts still hold true in the case of AWS Bedrock.
## Conclusion
AWS Bedrock extends prompt caching to Amazon Nova models while maintaining full support for Claude models. The key differences from Anthropic's direct API are a fixed 5-minute TTL, Nova's lack of tool caching support, and region-specific pricing.
Spring AI provides the same strategic caching patterns across both providers. Whether you choose Claude through Anthropic, Claude through Bedrock, or Amazon Nova models, the five caching strategies work consistently with minimal code changes.
The decision between providers depends on model availability (Nova is only on Bedrock), cache TTL requirements, and tool caching needs (Nova doesn't support it).
For more on prompt caching support in Spring AI for AWS Bercok see [Spring AI Bedrock documentation](https://docs.spring.io/spring-ai/reference/1.1-SNAPSHOT/api/chat/bedrock-converse.html#_prompt_caching) and [AWS Bedrock Prompt Caching documentation](https://docs.aws.amazon.com/bedrock/latest/userguide/prompt-caching.html).
# Spring AI with Docker Model Runner
Source: https://springaicommunity.mintlify.app/blog/model-providers/docker-model-runner
> This blog post is authored by [Eddú Meléndez](https://github.com/eddumelendez).
> This blog post is authored by [Eddú Meléndez](https://github.com/eddumelendez).
Docker recently [released a Model Runner in Docker Desktop for Mac 4.40.0](https://www.docker.com/blog/docker-desktop-4-40/) on Apple silicon. The Docker Model Runner provides a local Inference API designed to be compatible with the OpenAI API, enabling easy integration with [Spring AI](https://docs.spring.io/spring-ai/reference/api/chat/dmr-chat.html) as part of the Spring AI 1.0.0-M7 release. Models are distributed as standard OCI artifacts on Docker Hub under the [ai namespace](https://hub.docker.com/u/ai).
## Prerequisites
* Download Docker Desktop for Mac 4.40.0.
* Choose one of the following options to enable the Model Runner:
Option 1:
* Enable Model Runner \`docker desktop enable model-runner --tcp 12434\`.
* Set the base-url to \`[http://localhost:12434/engines\\\`](http://localhost:12434/engines\\`)
Option 2:
* Enable Model Runner \`docker desktop enable model-runner\`.
* Use [Testcontainers](https://testcontainers.com/) and set the base-url as follows:
```java theme={null}
@Container
private static final SocatContainer socat = new SocatContainer().withTarget(80, "model-runner.docker.internal");
@Bean
public OpenAiApi chatCompletionApi() {
var baseUrl = "http://%s:%d/engines".formatted(socat.getHost(), socat.getMappedPort(80));
return OpenAiApi.builder().baseUrl(baseUrl).apiKey("test").build();
}
```
Next, pull the model \`docker model pull ai/gemma3\` and confirm it is available locally \`docker model list\`
## Dependencies
Go to start.spring.io, select Spring Web, OpenAI and Testcontainers and generate the project.
The following dependencies must be listed
```
org.springframework.boot
spring-boot-starter-web
org.springframework.ai
spring-ai-openai-spring-boot-starter
org.springframework.ai
spring-ai-spring-boot-testcontainers
test
```
Also, make sure the Spring AI BOM is present
```
org.springframework.ai
spring-ai-bom
${spring-ai.version}
pom
import
```
Configuring Spring AI
To use Docker Model Runner, we need to configure the OpenAI client to point to the right endpoint and use the model pulled earlier
For Option 1: Let’s configure the src/main/resources/application.properties
```
spring.ai.openai.api-key=ignored
spring.ai.openai.base-url=http://localhost:12434/engines
spring.ai.openai.chat.options.model=ai/gemma3
```
For Option 2 (Using Testcontainers): Let’s go to \`TestcontainersConfiguration\`, define the SocatContainer bean and register the properties with \`DynamicPropertyRegistrar\` bean.
```java theme={null}
@TestConfiguration(proxyBeanMethods = false)
class TestcontainersConfiguration {
@Bean
SocatContainer socat() {
return new SocatContainer(DockerImageName.parse("alpine/socat:1.8.0.1"))
.withTarget(80, "model-runner.docker.internal");
}
@Bean
DynamicPropertyRegistrar properties(SocatContainer socat) {
return (registrar) -> {
registrar.add("spring.ai.openai.base-url", () -> "http://%s:%d/engines".formatted(socat.getHost(), socat.getMappedPort(80)));
registrar.add("spring.ai.openai.api-key", () -> "test-api-key");
registrar.add("spring.ai.openai.chat.options.model", () -> "ai/gemma3");
};
}
}
```
## Chat example
Now, let’s create a simple controller
```java theme={null}
@RestController
public class ChatController {
private final ChatClient chatClient;
public ChatController(ChatClient.Builder chatClientBuilder) {
this.chatClient = chatClientBuilder.build();
}
@GetMapping("/chat")
public String chat(@RequestParam String message) {
return this.chatClient.prompt()
.user(message)
.call()
.content();
}
@GetMapping("/chat-stream")
public Flux chatStream(@RequestParam String message) {
return this.chatClient.prompt()
.user(message)
.stream()
.content();
}
}
```
Run the application with \`./mvnw spring-boot:test-run\`
Using [httpie](https://httpie.io/), let’s call to the \`/chat\` endpoint
```
http :8080/chat message=="tell me a joke"
```
We can also call to the \`/chat-stream\` endpoint
```
http :8080/chat-stream message=="tell me a haiku about docker containers"
```
## Tool example
Docker Model Runner of course supports tool calling if used with a model that supports tool calling.
Create a \`FunctionCallConfig\` class and add a simple function
```java theme={null}
@Configuration(proxyBeanMethods = false)
class FunctionCallConfig {
@Bean
@Description("Get the stock price")
public Function stockFunction() {
return new MockStockService();
}
static class MockStockService implements Function {
public record StockRequest(String symbol) {}
public record StockResponse(double price) {}
@Override
public StockResponse apply(StockRequest request) {
double price = request.symbol().contains("AAPL") ? 198 : 114;
return new StockResponse(price);
}
}
}
```
Now, let’s register \`stockFunction\` function
```java theme={null}
@GetMapping("/stocks")
public String stocks(@RequestParam String message) {
return this.chatClient.prompt()
.user(message)
.tools("stockFunction")
.call()
.content();
}
```
Run the application \`./mvnw spring-boot:test-run\` and call the \`/stocks\` endpoint
```
http :8080/stocks message=="What's AAPL and NVDA stock price?"
```
The response should be something like \`AAPL stock price is 198.0 and NVDA stock price is 114.0.\` based on the hardcoded values we set.
## References
* # Introducing Docker Model Runner [https://www.docker.com/blog/introducing-docker-model-runner/](https://www.docker.com/blog/introducing-docker-model-runner/)
* Run LLMs Locally with Docker: A Quickstart Guide to Model Runner [https://www.docker.com/blog/run-llms-locally/](https://www.docker.com/blog/run-llms-locally/)
* Docker Model Runner docs [https://docs.docker.com/desktop/features/model-runner/](https://docs.docker.com/desktop/features/model-runner/)
* Spring AI Docker Model Runner Example [https://github.com/eddumelendez/spring-ai-dmr](https://github.com/eddumelendez/spring-ai-dmr)
## Conclusion
Docker Model Runner allows you to iterate faster, stay local and access an OpenAI-compatible API. It streamlines the development experience by enabling seamless integration with Spring AI’s OpenAI module, letting developers stay within their familiar inner-loop tooling. This empowers teams to build and test AI applications at their own pace—locally, securely, and efficiently. In the future, integration with Testcontainers will make it even easier to pull and run models on demand, further simplifying setup and testing workflows.Docker Model Runner allows you to iterate faster, stay local and access an OpenAI-compatible API. It streamlines the development experience by enabling seamless integration with Spring AI’s OpenAI module, letting developers stay within their familiar inner-loop tooling. This empowers teams to build and test AI applications at their own pace—locally, securely, and efficiently.
# Spring AI with Groq - a blazingly fast AI inference engine
Source: https://springaicommunity.mintlify.app/blog/model-providers/groq
> Faster information processing not only informs - it transforms how we perceive and innovate.
> Faster information processing not only informs - it transforms how we perceive and innovate.
[Spring AI](https://docs.spring.io/spring-ai/reference/), a powerful framework for integrating AI capabilities into Spring applications, now offers support for [Groq](https://groq.com/) - a blazingly fast AI inference engine with support for Tool/Function calling.
Leveraging Groq's OpenAI-compatible API, Spring AI seamlessly integrates by adapting its existing [OpenAI Chat](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html) client.
This approach enables developers to harness Groq's high-performance models through the familiar Spring AI API.
We'll explore how to configure and use the Spring AI OpenAI chat client to connect with Groq.
For detailed information, consult the Spring AI [Groq documentation](https://docs.spring.io/spring-ai/reference/api/chat/groq-chat.html) and related [tests](https://github.com/spring-projects/spring-ai/blob/main/models/spring-ai-openai/src/test/java/org/springframework/ai/openai/chat/proxy/GroqWithOpenAiChatModelIT.java).
# Groq API Key
To interact with Groq, you'll need to obtain a Groq API key from [https://console.groq.com/keys](https://console.groq.com/keys).
# Dependencies
Add the Spring AI OpenAI starter to your project.
``
``org.springframework.ai``
``spring-ai-openai-spring-boot-starter``
``
For Gradle, add this to your `build.gradle`
dependencies \{
implementation 'org.springframework.ai:spring-ai-openai-spring-boot-starter'
}
Ensure you've added the Spring [Milestone and Snapshot repositories](https://docs.spring.io/spring-ai/reference/getting-started.html#repositories) and add the [Spring AI BOM](https://docs.spring.io/spring-ai/reference/getting-started.html#dependency-management).
# Configuring Spring AI for Groq
To use Groq with Spring AI, we need to configure the OpenAI client to point to Groq's API endpoint and use Groq-specific models.
Add the following environment variables to your project:
export SPRING\_AI\_OPENAI\_API\_KEY=``\
export SPRING\_AI\_OPENAI\_BASE\_URL=[https://api.groq.com/openai](https://api.groq.com/openai)\
export SPRING\_AI\_OPENAI\_CHAT\_OPTIONS\_MODEL=llama3-70b-8192
Alternatively, you can add these to your `application.properties` file:
spring.ai.openai.api-key=``
spring.ai.openai.base-url=[https://api.groq.com/openai](https://api.groq.com/openai)
spring.ai.openai.chat.options.model=llama3-70b-8192
spring.ai.openai.chat.options.temperature=0.7
Key points:
* The `api-key` is set to one of your [Groq keys](https://console.groq.com/keys).
* The `base-url` is set to Groq's API endpoint: `https://api.groq.com/openai`
* The `model` is set to one of Groq's available [Models](https://console.groq.com/docs/models).
For the complete list of configuration properties, consult the [Groq chat properties](https://docs.spring.io/spring-ai/reference/api/chat/groq-chat.html#_chat_properties) documentation.
# Code Example
Now that we've configured Spring AI to use Groq, let's look at a simple example of how to use it in your application.
@RestController
public class ChatController \{
private final ChatClient chatClient;
@Autowired
public ChatController(ChatClient.Builder builder) \{
this.chatClient = builder.build();
}
@GetMapping("/ai/generate")
public Map generate(@RequestParam(value = "message", defaultValue = "Tell me a joke") String message) \{
String response = chatClient.prompt().user(message).call().content();
return Map.of("generation", response);
}
@GetMapping("/ai/generateStream")
public Flux`` generateStream(@RequestParam(value = "message",
defaultValue = "Tell me a joke") String message) \{
return chatClient.prompt().user(message).stream().content();
}
}
In this example, we've created a simple REST controller with two endpoints:
* `/ai/generate`: Generates a single response to a given prompt.
* `/ai/generateStream`: Streams the response, which can be useful for longer outputs or real-time interactions.
# Tools/Functions
Groq API endpoints support [tool/function calling](https://console.groq.com/docs/tool-use) when selecting one of the Tool/Function supporting models.
You can register custom Java functions with your ChatModel and have the provided Groq model intelligently choose to output a JSON object containing arguments to call one or many of the registered functions.
This is a powerful technique to connect the LLM capabilities with external tools and APIs.
### Tool Example
Here's a simple example of how to use Groq function calling with Spring AI:
@SpringBootApplication
public class GroqApplication \{
public static void main(String\[] args) \{
SpringApplication.run(GroqApplication.class, args);
}
@Bean
CommandLineRunner runner(ChatClient.Builder chatClientBuilder) \{
return args -> \{
var chatClient = chatClientBuilder.build();
var response = chatClient.prompt()
.user("What is the weather in Amsterdam and Paris?")
.functions("weatherFunction") // reference by bean name.
.call()
.content();
System.out.println(response);
};
}
@Bean
@Description("Get the weather in location")
public Function`` weatherFunction() \{
return new MockWeatherService();
}
public static class MockWeatherService implements Function`` \{
public record WeatherRequest(String location, String unit) \{}
public record WeatherResponse(double temp, String unit) \{}
@Override
public WeatherResponse apply(WeatherRequest request) \{
double temperature = request.location().contains("Amsterdam") ? 20 : 25;
return new WeatherResponse(temperature, request.unit);
}
}
}
In this example, when the model needs weather information, it will automatically call the `weatherFunction` bean, which can then fetch real-time weather data.
The expected response looks like this: "The weather in Amsterdam is currently 20 degrees Celsius, and the weather in Paris is currently 25 degrees Celsius."
Read more about OpenAI [Function Calling](https://docs.spring.io/spring-ai/reference/api/chat/functions/openai-chat-functions.html).
# Key Considerations
When using Groq with Spring AI, keep the following points in mind:
* Tool/Function Calling: Groq [supports](https://console.groq.com/docs/tool-use) Tool/Function calling. Check for the recommended models to use.
* API Compatibility: The Groq API is not fully compatible with the OpenAI API. Be aware of potential differences in behavior or features.
* Model Selection: Ensure you're using one of the Groq-specific [models](https://console.groq.com/docs/models).
* Multimodal Limitations: Currently, Groq doesn't support multimodal messages.
* Performance: Groq is known for its fast inference times. You may notice improved response speeds compared to other providers, especially for larger models.
# Conclusion
Integrating Groq with Spring AI opens up new possibilities for developers looking to leverage high-performance AI models in their Spring applications.
By repurposing the OpenAI client, Spring AI makes it straightforward to switch between different AI providers, allowing you to choose the best solution for your specific needs.
As you explore this integration, remember to stay updated with the latest documentation from both [Spring AI](https://docs.spring.io/spring-ai/reference/index.html) and [Groq](https://console.groq.com/docs/quickstart), as features and compatibility may evolve over time.
We encourage you to experiment with different Groq models and compare their performance and outputs to find the best fit for your use case.
Happy coding, and enjoy the speed and capabilities that Groq brings to your AI-powered Spring applications!
# Spring AI with NVIDIA LLM API
Source: https://springaicommunity.mintlify.app/blog/model-providers/nvidia
Spring AI now supports [NVIDIA's Large Language Model API](https://docs.api.nvidia.com/nim/reference/llm-apis), offering integration with a wide range of...
Spring AI now supports [NVIDIA's Large Language Model API](https://docs.api.nvidia.com/nim/reference/llm-apis), offering integration with a wide range of [models](https://docs.api.nvidia.com/nim/reference/llm-apis#models). By leveraging NVIDIA's OpenAI-compatible API, Spring AI allows developers to use NVIDIA's LLMs through the familiar [Spring AI API](https://docs.spring.io/spring-ai/reference/api/chat/nvidia-chat.html).
We'll explore how to configure and use the Spring AI OpenAI chat client to connect with NVIDIA LLM API.
* The demo application code is available in the [nvidia-llm](https://github.com/tzolov/nvidia-llm) GitHub repository.
* The SpringAI / NVIDIA integration [documentation](https://docs.spring.io/spring-ai/reference/api/chat/nvidia-chat.html).
# Prerequisite
* Create [NVIDIA](https://build.nvidia.com/explore/discover) account with sufficient credits.
* Select your preferred [LLM model](https://docs.api.nvidia.com/nim/reference/llm-apis#models) from NVIDIA's offerings. Like the `meta/llama-3.1-70b-instruct` in the screenshot below.
* From the model's page, obtain the API key for your chosen model.
# Dependencies
To get started, add the Spring AI OpenAI starter to your project.
For Maven, add this to your pom.xml:
``
``org.springframework.ai``
``spring-ai-openai-spring-boot-starter``
``
For Gradle, add this to your build.gradle:
gradleCopydependencies \{
implementation 'org.springframework.ai:spring-ai-openai-spring-boot-starter'
}
Ensure you've added the Spring Milestone and Snapshot repositories and add the [Spring AI BOM](https://docs.spring.io/spring-ai/reference/getting-started.html#dependency-management).
# Configuring Spring AI
To use NVIDIA LLM API with Spring AI, we need to configure the OpenAI client to point to the NVIDIA LLM API endpoint and use NVIDIA-specific models.
Add the following environment variables to your project:
export SPRING\_AI\_OPENAI\_API\_KEY=``
export SPRING\_AI\_OPENAI\_BASE\_URL=[https://integrate.api.nvidia.com](https://integrate.api.nvidia.com)
export SPRING\_AI\_OPENAI\_CHAT\_OPTIONS\_MODEL=meta/llama-3.1-70b-instruct
export SPRING\_AI\_OPENAI\_EMBEDDING\_ENABLED=false
export SPRING\_AI\_OPENAI\_CHAT\_OPTIONS\_MAX\_TOKENS=2048
Alternatively, you can add these to your application.properties file:
spring.ai.openai.api-key=``
spring.ai.openai.base-url=[https://integrate.api.nvidia.com](https://integrate.api.nvidia.com)
spring.ai.openai.chat.options.model=meta/llama-3.1-70b-instruct
# The NVIDIA LLM API doesn't support embeddings.
spring.ai.openai.embedding.enabled=false
# The NVIDIA LLM API requires this parameter to be set explicitly or error will be thrown.
spring.ai.openai.chat.options.max-tokens=2048
Key points:
* The `api-key` is set to your NVIDIA API key.
* The `base-url` is set to NVIDIA's LLM API endpoint: [https://integrate.api.nvidia.com](https://integrate.api.nvidia.com)
* The `model` is set to one of the models available on NVIDIA's LLM API.
* The NVIDIA LLM API reuquires the `max-tokens` to be explicitly set or a server error will be thrown.
* Since the NVIDIA LLM API is LLM only we can disable the embedding endpong: `embedding.enabled=false`.
Check the reference documentation for the complete list of [configuration properties](https://docs.spring.io/spring-ai/reference/api/chat/nvidia-chat.html#_chat_properties).
# Code Example
Now that we've configured Spring AI to use NVIDIA LLM API, let's look at a simple example of how to use it in your application.
@RestController
public class ChatController \{
private final ChatClient chatClient;
@Autowired
public ChatController(ChatClient.Builder builder) \{
this.chatClient = builder.build();
}
@GetMapping("/ai/generate")
public String generate(@RequestParam(value = "message", defaultValue = "Tell me a joke") String message) \{
return chatClient.prompt().user(message).call().content();
}
@GetMapping("/ai/generateStream")
public Flux`` generateStream(
@RequestParam(value = "message", defaultValue = "Tell me a joke") String message) \{
return chatClient.prompt().user(message).stream().content();
}
}
In the [ChatController.java](https://github.com/tzolov/nvidia-llm/blob/main/src/main/java/com/example/nvidia/ChatController.java) example, we've created a simple REST controller with two endpoints:
* `/ai/generate`: Generates a single response to a given prompt.
* `/ai/generateStream`: Streams the response, which can be useful for longer outputs or real-time interactions.
# Tool/Function Calling
NVIDIA LLM API endpoints support tool/function calling when selecting one of the Tool/Function supporting models.
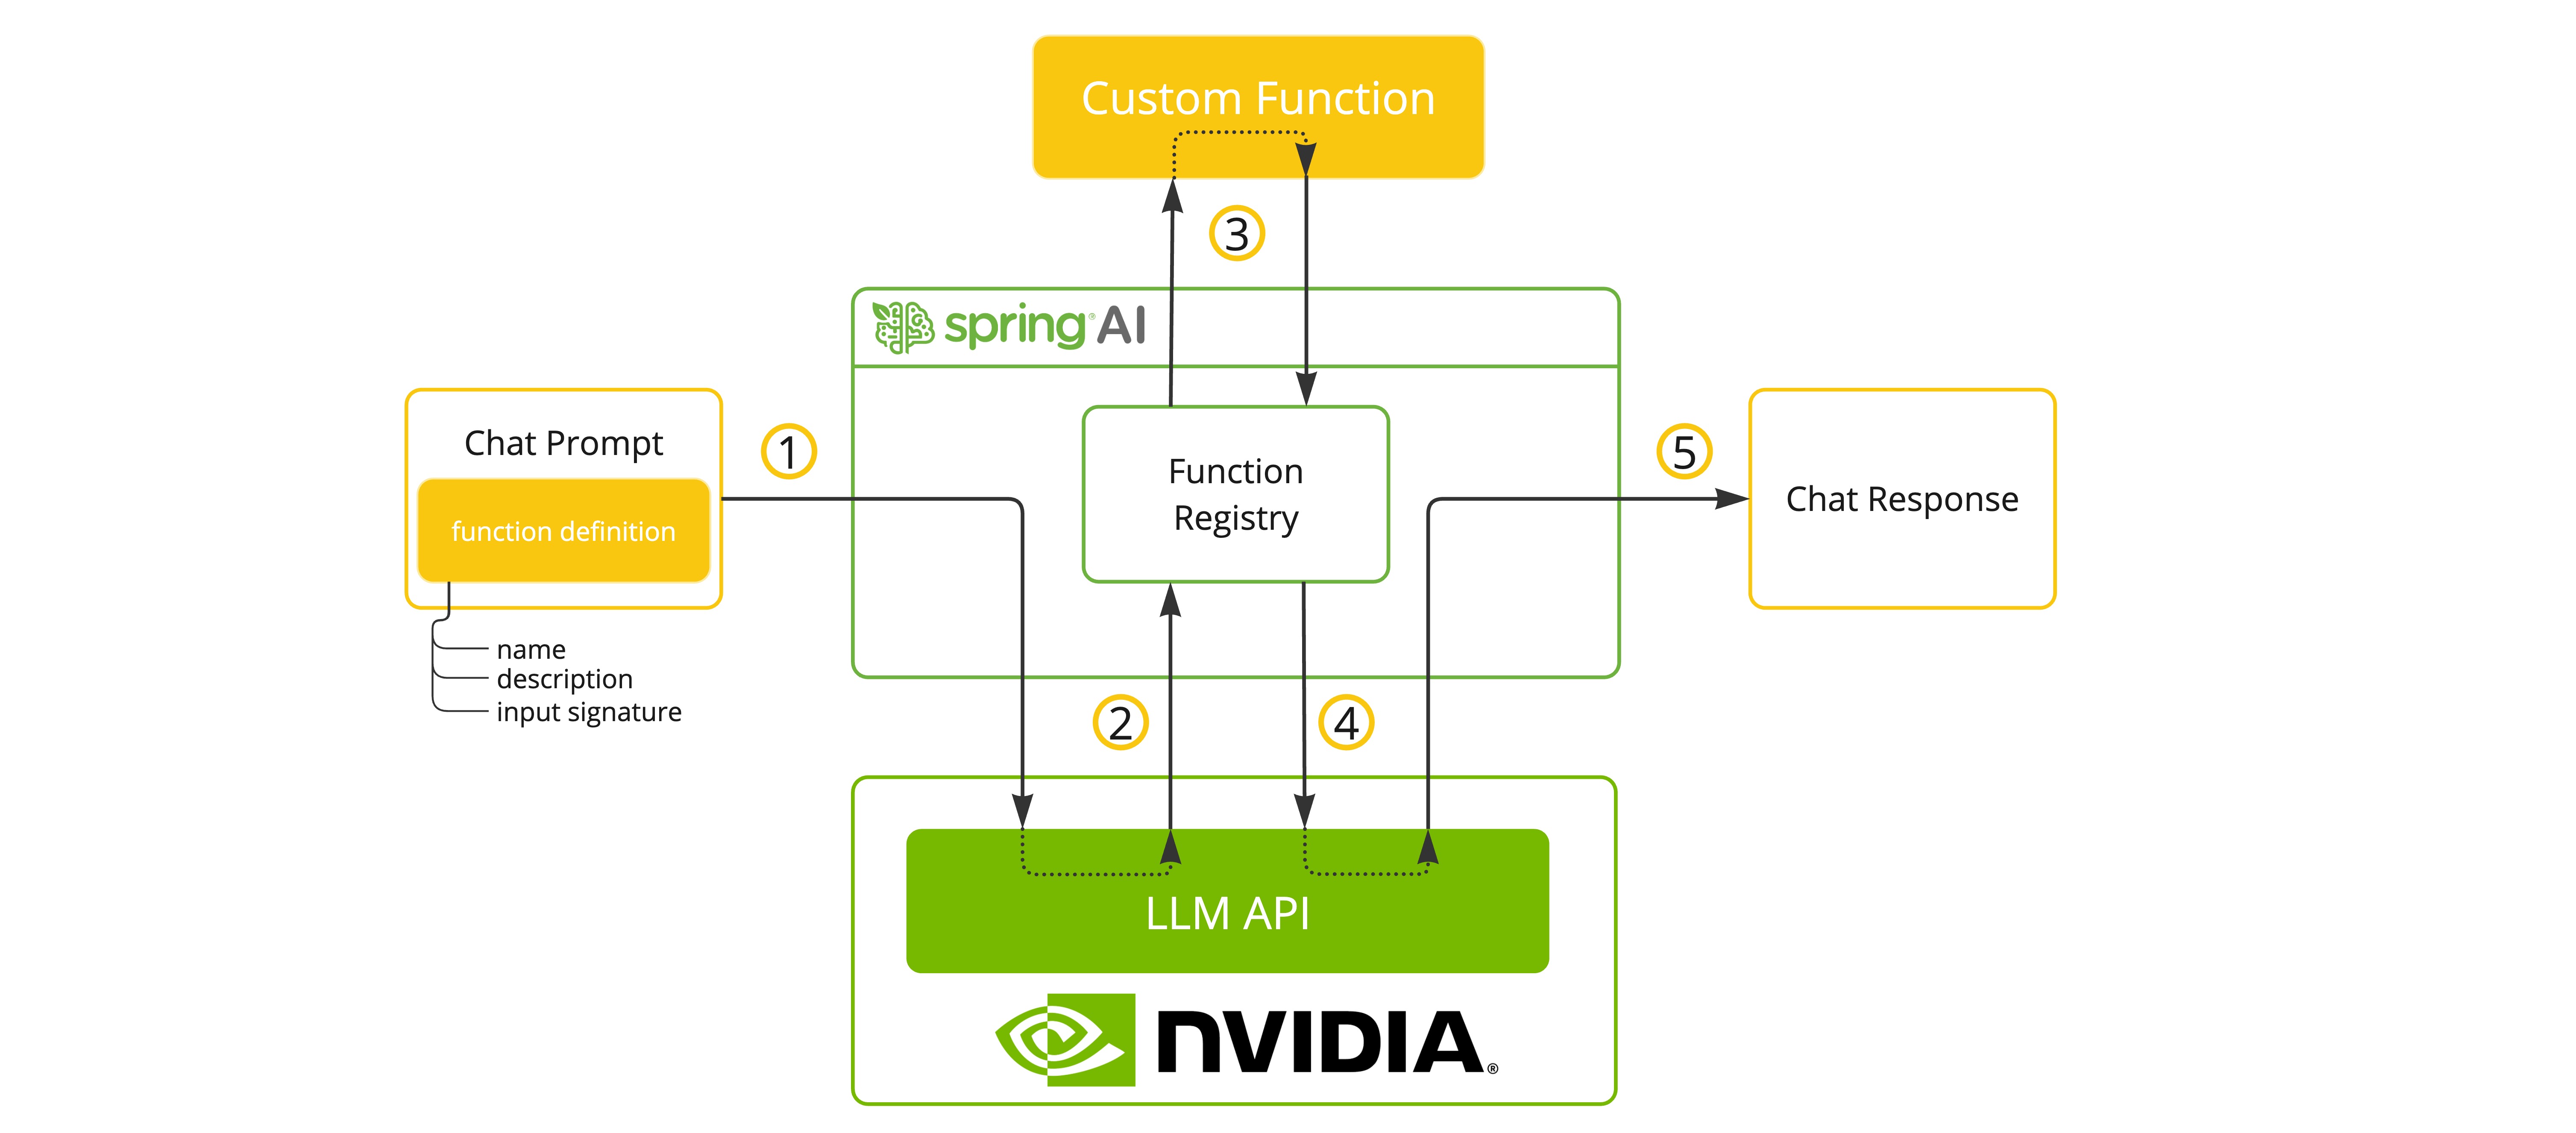
You can register custom Java functions with your ChatModel and have the provided LLM model intelligently choose to output a JSON object containing arguments to call one or many of the registered functions.
This is a powerful technique to connect the LLM capabilities with external tools and APIs.
Find more about SpringAI/OpenAI [Function Calling](https://docs.spring.io/spring-ai/reference/api/chat/functions/openai-chat-functions.html) support.
### Tool Example
Here's a simple example of how to use too/function calling with Spring AI:
@SpringBootApplication
public class NvidiaLlmApplication \{
public static void main(String\[] args) \{
SpringApplication.run(NvidiaLlmApplication.class, args);
}
@Bean
CommandLineRunner runner(ChatClient.Builder chatClientBuilder) \{
return args -> \{
var chatClient = chatClientBuilder.build();
var response = chatClient.prompt()
.user("What is the weather in Amsterdam and Paris?")
.functions("weatherFunction") // reference by bean name.
.call()
.content();
System.out.println(response);
};
}
@Bean
@Description("Get the weather in location")
public Function`` weatherFunction() \{
return new MockWeatherService();
}
public static class MockWeatherService implements Function`` \{
public record WeatherRequest(String location, String unit) \{}
public record WeatherResponse(double temp, String unit) \{}
@Override
public WeatherResponse apply(WeatherRequest request) \{
double temperature = request.location().contains("Amsterdam") ? 20 : 25;
return new WeatherResponse(temperature, request.unit);
}
}
}
In the [NvidiaLlmApplication.java](https://github.com/tzolov/nvidia-llm/blob/main/src/main/java/com/example/nvidia/NvidiaLlmApplication.java) example, when the model needs weather information, it will automatically call the `weatherFunction` bean, which can then fetch real-time weather data.
The expected response looks like this:
> The weather in Amsterdam is currently 20 degrees Celsius, and the weather in Paris is currently 25 degrees Celsius.
# Key Considerations
When using NVIDIA LLM API with Spring AI, keep the following points in mind:
* **Model Selection**: NVIDIA offers a wide range of models from various providers. Choose the appropriate model for your use case.
* **API Compatibility**: The NVIDIA LLM API is designed to be compatible with the OpenAI API, which allows for easy integration with Spring AI.
* **Performance**: NVIDIA's LLM API is optimized for high-performance inference. You may notice improved response speeds, especially for larger models.
* **Specialized Models**: NVIDIA offers models specialized for different tasks, such as code completion, math problems, and general chat. Select the most appropriate model for your specific needs.
* **API Limits**: Be aware of any rate limits or usage quotas associated with your NVIDIA API key.
# References
For further information check the Spring AI and OpenAI reference documentations.
* [Spring AI NVIDIA Reference docs](https://docs.spring.io/spring-ai/reference/api/chat/nvidia-chat.html)
* [NVIDIA LLM API](https://docs.api.nvidia.com/nim/reference/llm-apis#overview)
* [Spring AI - NVIDIA - Demo](https://github.com/tzolov/nvidia-llm/blob/main/src/main/java/com/example/nvidia/ChatController.java)
* Previous Spring AI blog posts:
* [Spring AI Embraces OpenAI's Structured Outputs: Enhancing JSON Response Reliability](https://spring.io/blog/2024/08/09/spring-ai-embraces-openais-structured-outputs-enhancing-json-response)
* [Spring AI with Groq - a blazingly fast AI inference engine](https://spring.io/blog/2024/07/31/spring-ai-with-groq-a-blazingly-fast-ai-inference-engine)
* [Spring AI with Ollama Tool Support](https://spring.io/blog/2024/07/26/spring-ai-with-ollama-tool-support)
* [Spring AI - Structured Output](https://spring.io/blog/2024/05/09/spring-ai-structured-output)
* [Spring AI - Multimodality - Orbis Sensualium Pictus](https://spring.io/blog/2024/04/19/spring-ai-multimodality-orbis-sensualium-pictus)
* [Function Calling in Java and Spring AI using the latest Mistral AI API](https://spring.io/blog/2024/03/06/function-calling-in-java-and-spring-ai-using-the-latest-mistral-ai-api)
* [Spring Cloud Function for Azure Function](https://spring.io/blog/2023/02/24/spring-cloud-function-for-azure-function)
# Conclusion
Integrating NVIDIA LLM API with Spring AI opens up new possibilities for developers looking to leverage high-performance AI models in their Spring applications.
By repurposing the OpenAI client, Spring AI makes it straightforward to switch between different AI providers, allowing you to choose the best solution for your specific needs.
As you explore this integration, remember to stay updated with the latest documentation from both Spring AI and NVIDIA LLM API, as features and model availability may evolve over time.
We encourage you to experiment with different models and compare their performance and outputs to find the best fit for your use case.
Happy coding, and enjoy the speed and capabilities that NVIDIA LLM API brings to your AI-powered Spring applications!
# Leverage the Power of 45k, free, Hugging Face Models with Spring AI and Ollama
Source: https://springaicommunity.mintlify.app/blog/model-providers/ollama-huggingface
> This blog post is co-authored by our great contributor [Thomas Vitale](https://www.linkedin.com/in/vitalethomas/).
> This blog post is co-authored by our great contributor [Thomas Vitale](https://www.linkedin.com/in/vitalethomas/).
**Ollama** now supports all [GGUF](https://github.com/ggerganov/ggml/blob/master/docs/gguf.md) models from **Hugging Face**, allowing access to over 45,000 community-created models through [Spring AI's Ollama](https://docs.spring.io/spring-ai/reference/api/chat/ollama-chat.html) integration, runnable locally.

We'll explore using this new feature with Spring AI. The Spring AI Ollama integration can automatically pull unavailable models for both chat completion and embedding models. This is useful when switching models or deploying to new environments.
## Setting Up Spring AI with Ollama
Install Ollama on your system: [https://ollama.com/download](https://ollama.com/download).
**Tip**: Spring AI also supports [running Ollama via Testcontainers](https://docs.spring.io/spring-ai/reference/api/testcontainers.html) or integrating with an external Ollama service via [Kubernetes Service Bindings](https://docs.spring.io/spring-ai/reference/api/cloud-bindings.html).
Follow the [dependency management](https://docs.spring.io/spring-ai/reference/getting-started.html#dependency-management) guide to add the Spring AI BOM and the Spring AI Ollama boot starter to your project's Maven `pom.xml` file or Gradle `build.gradle` files.
Maven:
```xml theme={null}
org.springframework.ai
spring-ai-ollama-spring-boot-starter
```
Gradle:
```groovy theme={null}
implementation 'org.springframework.ai:spring-ai-ollama-spring-boot-starter'
```
Add the following properties to your `application.properties` file:
```properties theme={null}
spring.ai.ollama.chat.options.model=hf.co/bartowski/gemma-2-2b-it-GGUF
spring.ai.ollama.init.pull-model-strategy=always
```
* **spring.ai.ollama.chat.options.model**: Specifies the Hugging Face GGUF model to use using theformat: `hf.co/{username}/{repository}`
* **spring.ai.ollama.init.pull-model-strategy=always**: Enables automatic model pulling at startup time. For production, you should pre-download the models to avoid delays: `ollama pull hf.co/bartowski/gemma-2-2b-it-GGUF`.
**Note**: [Auto-pulling](https://docs.spring.io/spring-ai/reference/api/chat/ollama-chat.html#auto-pulling-models) is available in Spring AI 1.0.0-SNAPSHOT and the upcoming M4 release. For M3, pre-download models (`ollama pull hf.co/{username}/{repository}`).
You can disable the embedding auto-configuration if not required: `spring.ai.ollama.embedding.enabled=false`.
Otherwise, Spring AI will pull the `mxbai-embed-large` embedding model if not available locally.
## Usage Example
Using the configured Hugging Face model with Spring AI is straightforward and not different from using any other Spring AI model provider.
Here's a simple example:
```java theme={null}
@Bean
public CommandLineRunner run(ChatClient.Builder builder) {
var chatClient = builder.build();
return args -> {
var response = chatClient
.prompt("Tell me a joke")
.call()
.content();
logger.info("Answer: " + response);
};
}
```
## References
* [Spring AI Ollama Chat](https://docs.spring.io/spring-ai/reference/api/chat/ollama-chat.html)
* [Spring AI Ollama Embedding](https://docs.spring.io/spring-ai/reference/api/embeddings/ollama-embeddings.html)
* [Companion sample project](https://github.com/tzolov/spring-ai-ollama-huggingface-demo)
## Conclusion
The integration of Ollama's support for Hugging Face GGUF models with Spring AI opens up a world of possibilities for developers.
We encourage you to explore the vast collection of models on Hugging Face and experiment with different models in your Spring AI projects. Whether you're building advanced natural language understanding systems, creative writing tools, or complex analytical applications, Spring AI and Ollama provide the flexibility to easily leverage these powerful models.
Remember to stay updated with the latest developments in Spring AI and Ollama, as this field is rapidly evolving. Happy coding!
# Audio Multimodality: Expanding AI Interaction with Spring AI and OpenAI
Source: https://springaicommunity.mintlify.app/blog/prompts-and-output/audio-modality
> This blog post is co-authored by our great contributor [Thomas Vitale](https://www.linkedin.com/in/vitalethomas/).
> This blog post is co-authored by our great contributor [Thomas Vitale](https://www.linkedin.com/in/vitalethomas/).
OpenAI provides specialized models for `speech-to-text` and `text-to-speech` conversion, recognized for their performance and cost-efficiency. Spring AI integrates these capabilities via [Voice-to-Text](https://docs.spring.io/spring-ai/reference/api/audio/transcriptions/openai-transcriptions.html) and [Text-to-Speech (TTS)](https://docs.spring.io/spring-ai/reference/api/audio/speech/openai-speech.html).
The new [Audio Generation](https://platform.openai.com/docs/guides/audio) feature (`gpt-4o-audio-preview`) goes further, enabling mixed input and output modalities. Audio inputs can contain richer data than text alone. Audio can convey nuanced information like tone and inflection, and together with the audio outputs it enables asynchronous `speech-to-speech` interactions.
Additionally, this new multimodality opens up possibilities for innovative applications, such as structured data extraction. Developers can extract structured information not just from simple text, but also from images and audio, building complex, structured objects seamlessly.
## Spring AI Audio Integrations
The Spring AI [Multimodality Message API](https://docs.spring.io/spring-ai/reference/api/multimodality.html) simplifies the integration of multimodal capabilities with various AI models.
![]() Now it fully supports OpenAI’s [Audio Input](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html#_audio) and [Audio Output](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html#_output_audio) modalities, thanks in large part to community member [Thomas Vitale](https://www.linkedin.com/in/vitalethomas/), who contributed to this feature's development.
### Setup
Follow the [Spring AI-OpenAI](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html) integration documentation to prepare your environment.
### Audio Input
OpenAI’s [User Message API](https://platform.openai.com/docs/api-reference/chat/create#chat-create-messages) accepts base64-encoded audio files within messages using the [Media](https://github.com/spring-projects/spring-ai/blob/main/spring-ai-core/src/main/java/org/springframework/ai/chat/messages/Media.java) type. Supported formats include `audio/mp3` and `audio/wav`.
**Example: Adding audio to an input prompt:**
```java theme={null}
// Prepare the audio resource
var audioResource = new ClassPathResource("speech1.mp3");
// Create a user message with audio and send it to the chat model
String response = chatClient.prompt()
.user(u -> u.text("What is this recording about?")
.media(MimeTypeUtils.parseMimeType("audio/mp3"), audioResource))
.options(OpenAiChatOptions.builder()
.withModel(OpenAiApi.ChatModel.GPT_4_O_AUDIO_PREVIEW).build())
.call()
.content();
```
### Audio Output Generation
The OpenAI [Assistant Message API](https://platform.openai.com/docs/api-reference/chat/create#chat-create-messages) can return base64-encoded audio files using the `Media` type.
**Example: Generating audio output:**
```java theme={null}
// Generate an audio response
ChatResponse response = chatClient
.prompt("Tell me a joke about the Spring Framework")
.options(OpenAiChatOptions.builder()
.withModel(OpenAiApi.ChatModel.GPT_4_O_AUDIO_PREVIEW)
.withOutputModalities(List.of("text", "audio"))
.withOutputAudio(new AudioParameters(Voice.ALLOY, AudioResponseFormat.WAV))
.build())
.call()
.chatResponse();
// Access the audio transcript
String audioTranscript = response.getResult().getOutput().getContent();
// Retrieve the generated audio
byte[] generatedAudio = response.getResult().getOutput().getMedia().get(0).getDataAsByteArray();
```
To generate audio output, specify the audio modality in `OpenAiChatOptions`. Use the `AudioParameters` class to customize the voice and the audio format.
## [Voice ChatBot Demo](https://github.com/tzolov/voice-assistant-chatbot)
This example demonstrates building an interactive chatbot using Spring AI that supports input and output audio. It shows how AI can enhance user interaction with natural-sounding audio responses.
### Setup
Add the Spring AI OpenAI starter:
```xml theme={null}
org.springframework.ai
spring-ai-openai-spring-boot-starter
```
Configure the API key, model name, and output audio modality in `application.properties`:
```
spring.main.web-application-type=none
spring.ai.openai.api-key=${OPENAI_API_KEY}
spring.ai.openai.chat.options.model=gpt-4o-audio-preview
spring.ai.openai.chat.options.output-modalities=text,audio
spring.ai.openai.chat.options.output-audio.voice=ALLOY
spring.ai.openai.chat.options.output-audio.format=WAV
```
### Implementation
The Java implementation of the voice chatbot, detailed below, creates a conversational AI assistant using audio input and output. It leverages Spring AI's integration with OpenAI models to enable seamless interactions with users.
**VoiceAssistantApplication**
* `VoiceAssistantApplication` serves as the main application.
* The `CommandLineRunner` bean initializes the chatbot:
* The `ChatClient` is configured using the `systemPrompt` for contextual understanding and an in-memory chat memory for conversation history.
* The `Audio` utility is used to record voice input from the user and play back audio responses generated by the AI.
* **Chat Loop:** Inside the loop:
* **Voice Recording:** The `audio.startRecording()` and `audio.stopRecording()` methods handle the recording process, pausing for user input.
* **Processing AI Response:** The user message is sent to the AI model via `chatClient.prompt()`. The audio data is encapsulated in the `Media` object.
* **Response Handling:** The AI-generated response is retrieved as text and played back as audio using the `Audio.play()` method.
Refer to the following code snippet for the implementation:
```java theme={null}
@Bean
public CommandLineRunner chatBot(ChatClient.Builder chatClientBuilder,
@Value("${chatbot.prompt:classpath:/marvin.paranoid.android.txt}") Resource systemPrompt) {
return args -> {
var chatClient = chatClientBuilder.defaultSystem(systemPrompt)
.defaultAdvisors(new MessageChatMemoryAdvisor(new InMemoryChatMemory()))
.build();
try (Scanner scanner = new Scanner(System.in)) {
Audio audio = new Audio();
while (true) {
audio.startRecording();
System.out.print("Recording your question ... press to stop! ");
scanner.nextLine();
audio.stopRecording();
System.out.print("PROCESSING ... ");
AssistantMessage response = chatClient.prompt()
.messages(new UserMessage("Please answer the questions in the audio input",
new Media(MediaType.parseMediaType("audio/wav"),
new ByteArrayResource(audio.getLastRecording()))))
.call()
.chatResponse()
.getResult()
.getOutput();
System.out.println("ASSISTANT: " + response.getContent());
Audio.play(response.getMedia().get(0).getDataAsByteArray());
}
}
};
}
```
The `Audio` utility, for capturing and playing back audio, is a single class leveraging the plain `Java Sound API`.
```
▗▄▄▖▗▄▄▖ ▗▄▄▖ ▗▄▄▄▖▗▖ ▗▖ ▗▄▄▖ ▗▄▖ ▗▄▄▄▖
▐▌ ▐▌ ▐▌▐▌ ▐▌ █ ▐▛▚▖▐▌▐▌ ▐▌ ▐▌ █
▝▀▚▖▐▛▀▘ ▐▛▀▚▖ █ ▐▌ ▝▜▌▐▌▝▜▌ ▐▛▀▜▌ █
▗▄▄▞▘▐▌ ▐▌ ▐▌▗▄█▄▖▐▌ ▐▌▝▚▄▞▘ ▐▌ ▐▌▗▄█▄▖
▗▄▄▖ ▗▄▖ ▗▄▄▖ ▗▄▖ ▗▖ ▗▖ ▗▄▖ ▗▄▄▄▖▗▄▄▄ ▗▄▖ ▗▖ ▗▖▗▄▄▄ ▗▄▄▖ ▗▄▖ ▗▄▄▄▖▗▄▄▄
▐▌ ▐▌▐▌ ▐▌▐▌ ▐▌▐▌ ▐▌▐▛▚▖▐▌▐▌ ▐▌ █ ▐▌ █ ▐▌ ▐▌▐▛▚▖▐▌▐▌ █▐▌ ▐▌▐▌ ▐▌ █ ▐▌ █
▐▛▀▘ ▐▛▀▜▌▐▛▀▚▖▐▛▀▜▌▐▌ ▝▜▌▐▌ ▐▌ █ ▐▌ █ ▐▛▀▜▌▐▌ ▝▜▌▐▌ █▐▛▀▚▖▐▌ ▐▌ █ ▐▌ █
▐▌ ▐▌ ▐▌▐▌ ▐▌▐▌ ▐▌▐▌ ▐▌▝▚▄▞▘▗▄█▄▖▐▙▄▄▀ ▐▌ ▐▌▐▌ ▐▌▐▙▄▄▀▐▌ ▐▌▝▚▄▞▘▗▄█▄▖▐▙▄▄▀
2024-12-01T11:00:11.274+01:00 INFO 31297 --- [voice-assistant-chatbot] [ main] s.a.d.a.m.VoiceAssistantApplication : Started VoiceAssistantApplication in 0.827 seconds (process running for 1.054)
Recording your question ... press to stop!
```
The complete demo is available on GitHub: [voice-assistant-chatbot](https://github.com/tzolov/voice-assistant-chatbot)
## Important Considerations
* [One hour of](https://github.com/tzolov/voice-assistant-chatbot) audio input is roughly equivalent to 128k tokens.
* The model currently supports `modalities = ["text", "audio"]`.
* Future updates may offer more flexible modality controls.
## Conclusion
The `gpt-4o-audio-preview` model unlocks new possibilities for dynamic audio interactions, enabling developers to build rich, AI-powered audio applications.
*Disclaimer: API capabilities and features may evolve. Refer to the latest OpenAI and Spring AI documentation for updates.*
# Spring AI - Multimodality - Orbis Sensualium Pictus
Source: https://springaicommunity.mintlify.app/blog/prompts-and-output/multimodality
*__UPDATE__ 20.07.2024 : Update Message API hierarchy diagram and update the model names supporting multimodality*
***UPDATE** 20.07.2024 : Update Message API hierarchy diagram and update the model names supporting multimodality*
***UPDATE** 02.06.2024 : Add an additional code snippet showing how to use the new ChatClient API.*
Humans process knowledge, simultaneously across multiple modes of data inputs. The way we learn, our experiences are all multimodal. We don't have just vision, just audio and just text.
These foundational principles of learning were articulated by the father of modern education John Amos Comenius, in his work, "Orbis Sensualium Pictus", dating back to 1658.
> "All things that are naturally connected ought to be taught in combination"
Contrary to those principles, in the past, our approach to Machine Learning was often focused on specialised models tailored to process a single modality. For instance, we developed audio models for tasks like text-to-speech or speech-to-text, and computer vision models for tasks such as object detection and classification.
However, a new wave of multimodal large language models starts to emerge. Examples include OpenAI's GPT-4o, Google's Vertex AI Gemini Pro 1.5, Anthropic's Claude3, and open source offerings LLaVA and balklava are able to accept multiple inputs, including text images, audio and video and generate text responses by integrating these inputs.
The multimodal large language model (LLM) features **enable the models to process and generate text in conjunction with other modalities such as images, audio, or video.**
# Spring AI - Multimodality
Multimodality refers to a model’s ability to simultaneously understand and process information from various sources, including text, images, audio, and other data formats.
The Spring AI Message API provides all necessary abstractions to support multimodal LLMs.

The UserMessage’s **content** field is used as primarily text inputs, while the, optional, **media** field allows adding one or more additional content of different modalities such as images, audio and video. The MimeType specifies the modality type.
Depending on the used LLMs the Media's data field can be either encoded raw media content or an URI to the content.
***Note:** The media field is currently applicable only for user input messages, e.g. `UserMessage`.*
## Example
Lets for example take the following picture (*multimodal.test.png*) as an input and ask the LLM to explain what it sees in the picture.
For most multimodal LLMs, the Spring AI code would look something like this:
byte\[] imageData = new ClassPathResource("/multimodal.test.png").getContentAsByteArray();
var userMessage = new UserMessage(
"Explain what do you see in this picture?", // text content
List.of(new Media(MimeTypeUtils.IMAGE\_PNG, imageData))); // image content
ChatResponse response = chatModel.call(new Prompt(List.of(userMessage)));
or with the new fluent [ChatClient API](https://docs.spring.io/spring-ai/reference/api/chatclient.html):
String response = ChatClient.create(chatModel).prompt()
.user(u -> u.text("Explain what do you see on this picture?")
.media(MimeTypeUtils.IMAGE\_PNG, new ClassPathResource("/multimodal.test.png")))
.call()
.content();
and produce a response like:
> This is an image of a fruit bowl with a simple design. The bowl is made of metal with curved wire edges that create an open structure, allowing the fruit to be visible from all angles. Inside the bowl, there are two yellow bananas resting on top of what appears to be a red apple. The bananas are slightly overripe, as indicated by the brown spots on their peels. The bowl has a metal ring at the top, likely to serve as a handle for carrying. The bowl is placed on a flat surface with a neutral-colored background that provides a clear view of the fruit inside.
Latest (1.0.0-SANPSHOT and 1.0.0-M1) versions of Spring AI provides multimodal support for the following Chat Clients:
* [Open AI - (GPT-4o)](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/chat/openai-chat.html#_multimodal)
* [Ollama - (LLaVa and Baklava models)](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/chat/ollama-chat.html#_multimodal)
* [Vertex AI Gemini - (gemini-pro-1.5 model)](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/chat/vertexai-gemini-chat.html#_multimodal)
* [Anthropic Claude 3](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/chat/anthropic-chat.html#_multimodal)
* [AWS Bedrock Anthropic Claude 3](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/chat/bedrock/bedrock-anthropic3.html#_multimodal)
## Next steps
Next, the Spring AI will rework the Document API to add multimodality support similar to the Message API.
Currently the AWS Bedrock [Titan EmbeddingClient](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/embeddings/bedrock-titan-embedding.html) supports image embeddings.
It would be required to integrate additional multimodal Embedding services to allow encoding, storing and searching of multimodal content in the Vector Stores.
# Conclusion
Traditionally, machine learning focused on specialised models for singular modalities. However, with innovations like OpenAI's GPT-4 Vision and Google's Vertex AI Gemini, a new era has dawned.
As we embrace this era of multimodal AI, the vision of interconnected learning envisioned by Comenius becomes a reality.
Spring AI's Message API facilitates the integration of multimodal LLMs, enabling developers to create innovative solutions. By leveraging these models, applications can comprehend and respond to data in various forms, unlocking new possibilities for AI-driven experiences.
# Prompt Engineering Techniques with Spring AI
Source: https://springaicommunity.mintlify.app/blog/prompts-and-output/prompt-engineering-patterns
This blog post demonstrates practical implementations of Prompt Engineering techniques using [Spring AI](https://docs.spring.io/spring-ai/reference/index.html).
This blog post demonstrates practical implementations of Prompt Engineering techniques using [Spring AI](https://docs.spring.io/spring-ai/reference/index.html).
![]() The examples and patterns in this article are based on the comprehensive [Prompt Engineering Guide](https://www.kaggle.com/whitepaper-prompt-engineering) that covers the theory, principles, and patterns of effective prompt engineering.
The blog shows how to translate those concepts into working Java code using Spring AI's fluent [ChatClient API](https://docs.spring.io/spring-ai/reference/api/chatclient.html).
For convenience, the examples are structured to follow the same patterns and techniques outlined in the original guide.
The demo source code used in this article is available at: [https://github.com/spring-projects/spring-ai-examples/tree/main/prompt-engineering/prompt-engineering-patterns](https://github.com/spring-projects/spring-ai-examples/tree/main/prompt-engineering/prompt-engineering-patterns)
## 1. Configuration
The configuration section outlines how to set up and tune your Large Language Model (LLM) with Spring AI.
It covers selecting the right LLM provider for your use case and configuring important generation parameters that control the quality, style, and format of model outputs.
### LLM Provider Selection
For prompt engineering, you will start by choosing a model.
Spring AI supports [multiple LLM providers](https://docs.spring.io/spring-ai/reference/api/chat/comparison.html) (such as OpenAI, Anthropic, Google Vertex AI, AWS Bedrock, Ollama, and more), letting you switch providers without changing application code—just update your configuration.
Just add the selected starter dependency `spring-ai-starter-model-`.
For example, here is how to enable Anthropic Claude API:
```xml theme={null}
org.springframework.ai
spring-ai-starter-model-anthropic
```
along with some connection properties:
`spring.ai.anthropic.api-key=${ANTHROPIC_API_KEY}`
You can specify a particular LLM model name like this:
```java theme={null}
.options(ChatOptions.builder()
.model("claude-3-7-sonnet-latest") // Use Anthropic's Claude model
.build())
```
Find detailed information for enabling and configuring the preferred AI model in the [reference docs](https://docs.spring.io/spring-ai/reference/api/chatmodel.html).
### LLM Output Configuration
![]() Before we dive into prompt engineering techniques, it's essential to understand how to configure the LLM's output behavior. Spring AI provides several configuration options that let you control various aspects of generation through the [ChatOptions](https://docs.spring.io/spring-ai/reference/api/chatmodel.html#_chat_options) builder.
All configurations can be applied programmatically as demonstrated in the examples below or through Spring application properties at start time.
#### Temperature
Temperature controls the randomness or "creativity" of the model's response.
* **Lower values (0.0-0.3)**: More deterministic, focused responses. Better for factual questions, classification, or tasks where consistency is critical.
* **Medium values (0.4-0.7)**: Balanced between determinism and creativity. Good for general use cases.
* **Higher values (0.8-1.0)**: More creative, varied, and potentially surprising responses. Better for creative writing, brainstorming, or generating diverse options.
```java theme={null}
.options(ChatOptions.builder()
.temperature(0.1) // Very deterministic output
.build())
```
Understanding temperature is crucial for prompt engineering as different techniques benefit from different temperature settings.
#### Output Length (MaxTokens)
The `maxTokens` parameter limits how many tokens (word pieces) the model can generate in its response.
* **Low values (5-25)**: For single words, short phrases, or classification labels.
* **Medium values (50-500)**: For paragraphs or short explanations.
* **High values (1000+)**: For long-form content, stories, or complex explanations.
```java theme={null}
.options(ChatOptions.builder()
.maxTokens(250) // Medium-length response
.build())
```
Setting appropriate output length is important to ensure you get complete responses without unnecessary verbosity.
#### Sampling Controls (Top-K and Top-P)
These parameters give you fine-grained control over the token selection process during generation.
* **Top-K**: Limits token selection to the K most likely next tokens. Higher values (e.g., 40-50) introduce more diversity.
* **Top-P (nucleus sampling)**: Dynamically selects from the smallest set of tokens whose cumulative probability exceeds P. Values like 0.8-0.95 are common.
```java theme={null}
.options(ChatOptions.builder()
.topK(40) // Consider only the top 40 tokens
.topP(0.8) // Sample from tokens that cover 80% of probability mass
.build())
```
These sampling controls work in conjunction with temperature to shape response characteristics.
#### Structured Response Format
Along with the plain text response (using `.content()`), Spring AI makes it easy to directly map LLM responses to Java objects using the `.entity()` method.
```java theme={null}
enum Sentiment {
POSITIVE, NEUTRAL, NEGATIVE
}
Sentiment result = chatClient.prompt("...")
.call()
.entity(Sentiment.class);
```
This feature is particularly powerful when combined with system prompts that instruct the model to return structured data.
#### Model-Specific Options
While the portable `ChatOptions` provides a consistent interface across different LLM providers, Spring AI also offers model-specific options classes that expose provider-specific features and configurations. These model-specific options allow you to leverage the unique capabilities of each LLM provider.
```java theme={null}
// Using OpenAI-specific options
OpenAiChatOptions openAiOptions = OpenAiChatOptions.builder()
.model("gpt-4o")
.temperature(0.2)
.frequencyPenalty(0.5) // OpenAI-specific parameter
.presencePenalty(0.3) // OpenAI-specific parameter
.responseFormat(new ResponseFormat("json_object")) // OpenAI-specific JSON mode
.seed(42) // OpenAI-specific deterministic generation
.build();
String result = chatClient.prompt("...")
.options(openAiOptions)
.call()
.content();
// Using Anthropic-specific options
AnthropicChatOptions anthropicOptions = AnthropicChatOptions.builder()
.model("claude-3-7-sonnet-latest")
.temperature(0.2)
.topK(40) // Anthropic-specific parameter
.thinking(AnthropicApi.ThinkingType.ENABLED, 1000) // Anthropic-specific thinking configuration
.build();
String result = chatClient.prompt("...")
.options(anthropicOptions)
.call()
.content();
```
Each model provider has its own implementation of chat options (e.g., `OpenAiChatOptions`, `AnthropicChatOptions`, `MistralAiChatOptions`) that exposes provider-specific parameters while still implementing the common interface. This approach gives you the flexibility to use portable options for cross-provider compatibility or model-specific options when you need access to unique features of a particular provider.
Note that when using model-specific options, your code becomes tied to that specific provider, reducing portability. It's a trade-off between accessing advanced provider-specific features versus maintaining provider independence in your application.
## 2. Prompt Engineering Techniques
Each section below implements a specific prompt engineering technique from the guide.
By following both the "Prompt Engineering" guide and these implementations, you'll develop a thorough understanding of not just what prompt engineering techniques are available, but how to effectively implement them in production Java applications.
### 2.1 Zero-Shot Prompting
Zero-shot prompting involves asking an AI to perform a task without providing any examples. This approach tests the model's ability to understand and execute instructions from scratch. Large language models are trained on vast corpora of text, allowing them to understand what tasks like "translation," "summarization," or "classification" entail without explicit demonstrations.
Zero-shot is ideal for straightforward tasks where the model likely has seen similar examples during training, and when you want to minimize prompt length. However, performance may vary depending on task complexity and how well the instructions are formulated.
```java theme={null}
// Implementation of Section 2.1: General prompting / zero shot (page 15)
public void pt_zero_shot(ChatClient chatClient) {
enum Sentiment {
POSITIVE, NEUTRAL, NEGATIVE
}
Sentiment reviewSentiment = chatClient.prompt("""
Classify movie reviews as POSITIVE, NEUTRAL or NEGATIVE.
Review: "Her" is a disturbing study revealing the direction
humanity is headed if AI is allowed to keep evolving,
unchecked. I wish there were more movies like this masterpiece.
Sentiment:
""")
.options(ChatOptions.builder()
.model("claude-3-7-sonnet-latest")
.temperature(0.1)
.maxTokens(5)
.build())
.call()
.entity(Sentiment.class);
System.out.println("Output: " + reviewSentiment);
}
```
This example shows how to classify a movie review sentiment without providing examples. Note the low temperature (0.1) for more deterministic results and the direct `.entity(Sentiment.class)` mapping to a Java enum.
**Reference:** Brown, T. B., et al. (2020). "Language Models are Few-Shot Learners." arXiv:2005.14165. [https://arxiv.org/abs/2005.14165](https://arxiv.org/abs/2005.14165)
### 2.2 One-Shot & Few-Shot Prompting
Few-shot prompting provides the model with one or more examples to help guide its responses, particularly useful for tasks requiring specific output formats. By showing the model examples of desired input-output pairs, it can learn the pattern and apply it to new inputs without explicit parameter updates.
One-shot provides a single example, which is useful when examples are costly or when the pattern is relatively simple. Few-shot uses multiple examples (typically 3-5) to help the model better understand patterns in more complex tasks or to illustrate different variations of correct outputs.
```java theme={null}
// Implementation of Section 2.2: One-shot & few-shot (page 16)
public void pt_ones_shot_few_shots(ChatClient chatClient) {
String pizzaOrder = chatClient.prompt("""
Parse a customer's pizza order into valid JSON
EXAMPLE 1:
I want a small pizza with cheese, tomato sauce, and pepperoni.
JSON Response:
```
\{
"size": "small",
"type": "normal",
"ingredients": \["cheese", "tomato sauce", "pepperoni"]
}
```
EXAMPLE 2:
Can I get a large pizza with tomato sauce, basil and mozzarella.
JSON Response:
```
\{
"size": "large",
"type": "normal",
"ingredients": \["tomato sauce", "basil", "mozzarella"]
}
```
Now, I would like a large pizza, with the first half cheese and mozzarella.
And the other tomato sauce, ham and pineapple.
""")
.options(ChatOptions.builder()
.model("claude-3-7-sonnet-latest")
.temperature(0.1)
.maxTokens(250)
.build())
.call()
.content();
}
```
Few-shot prompting is especially effective for tasks requiring specific formatting, handling edge cases, or when the task definition might be ambiguous without examples. The quality and diversity of the examples significantly impact performance.
**Reference:** Brown, T. B., et al. (2020). "Language Models are Few-Shot Learners." arXiv:2005.14165. [https://arxiv.org/abs/2005.14165](https://arxiv.org/abs/2005.14165)
### 2.3 System, contextual and role prompting
#### System Prompting
System prompting sets the overall context and purpose for the language model, defining the "big picture" of what the model should be doing. It establishes the behavioral framework, constraints, and high-level objectives for the model's responses, separate from the specific user queries.
System prompts act as a persistent "mission statement" throughout the conversation, allowing you to set global parameters like output format, tone, ethical boundaries, or role definitions. Unlike user prompts which focus on specific tasks, system prompts frame how all user prompts should be interpreted.
```java theme={null}
// Implementation of Section 2.3.1: System prompting
public void pt_system_prompting_1(ChatClient chatClient) {
String movieReview = chatClient
.prompt()
.system("Classify movie reviews as positive, neutral or negative. Only return the label in uppercase.")
.user("""
Review: "Her" is a disturbing study revealing the direction
humanity is headed if AI is allowed to keep evolving,
unchecked. It's so disturbing I couldn't watch it.
Sentiment:
""")
.options(ChatOptions.builder()
.model("claude-3-7-sonnet-latest")
.temperature(1.0)
.topK(40)
.topP(0.8)
.maxTokens(5)
.build())
.call()
.content();
}
```
System prompting is particularly powerful when combined with Spring AI's entity mapping capabilities:
```java theme={null}
// Implementation of Section 2.3.1: System prompting with JSON output
record MovieReviews(Movie[] movie_reviews) {
enum Sentiment {
POSITIVE, NEUTRAL, NEGATIVE
}
record Movie(Sentiment sentiment, String name) {
}
}
MovieReviews movieReviews = chatClient
.prompt()
.system("""
Classify movie reviews as positive, neutral or negative. Return
valid JSON.
""")
.user("""
Review: "Her" is a disturbing study revealing the direction
humanity is headed if AI is allowed to keep evolving,
unchecked. It's so disturbing I couldn't watch it.
JSON Response:
""")
.call()
.entity(MovieReviews.class);
```
System prompts are especially valuable for multi-turn conversations, ensuring consistent behavior across multiple queries, and for establishing format constraints like JSON output that should apply to all responses.
**Reference:** OpenAI. (2022). "System Message." [https://platform.openai.com/docs/guides/chat/introduction](https://platform.openai.com/docs/guides/chat/introduction)
#### Role Prompting
Role prompting instructs the model to adopt a specific role or persona, which affects how it generates content. By assigning a particular identity, expertise, or perspective to the model, you can influence the style, tone, depth, and framing of its responses.
Role prompting leverages the model's ability to simulate different expertise domains and communication styles. Common roles include expert (e.g., "You are an experienced data scientist"), professional (e.g., "Act as a travel guide"), or stylistic character (e.g., "Explain like you're Shakespeare").
```java theme={null}
// Implementation of Section 2.3.2: Role prompting
public void pt_role_prompting_1(ChatClient chatClient) {
String travelSuggestions = chatClient
.prompt()
.system("""
I want you to act as a travel guide. I will write to you
about my location and you will suggest 3 places to visit near
me. In some cases, I will also give you the type of places I
will visit.
""")
.user("""
My suggestion: "I am in Amsterdam and I want to visit only museums."
Travel Suggestions:
""")
.call()
.content();
}
```
Role prompting can be enhanced with style instructions:
```java theme={null}
// Implementation of Section 2.3.2: Role prompting with style instructions
public void pt_role_prompting_2(ChatClient chatClient) {
String humorousTravelSuggestions = chatClient
.prompt()
.system("""
I want you to act as a travel guide. I will write to you about
my location and you will suggest 3 places to visit near me in
a humorous style.
""")
.user("""
My suggestion: "I am in Amsterdam and I want to visit only museums."
Travel Suggestions:
""")
.call()
.content();
}
```
This technique is particularly effective for specialized domain knowledge, achieving a consistent tone across responses, and creating more engaging, personalized interactions with users.
**Reference:** Shanahan, M., et al. (2023). "Role-Play with Large Language Models." arXiv:2305.16367. [https://arxiv.org/abs/2305.16367](https://arxiv.org/abs/2305.16367)
#### Contextual Prompting
Contextual prompting provides additional background information to the model by passing context parameters. This technique enriches the model's understanding of the specific situation, enabling more relevant and tailored responses without cluttering the main instruction.
By supplying contextual information, you help the model understand the specific domain, audience, constraints, or background facts relevant to the current query. This leads to more accurate, relevant, and appropriately framed responses.
```java theme={null}
// Implementation of Section 2.3.3: Contextual prompting
public void pt_contextual_prompting(ChatClient chatClient) {
String articleSuggestions = chatClient
.prompt()
.user(u -> u.text("""
Suggest 3 topics to write an article about with a few lines of
description of what this article should contain.
Context: {context}
""")
.param("context", "You are writing for a blog about retro 80's arcade video games."))
.call()
.content();
}
```
Spring AI makes contextual prompting clean with the param() method to inject context variables. This technique is particularly valuable when the model needs specific domain knowledge, when adapting responses to particular audiences or scenarios, and for ensuring responses are aligned with particular constraints or requirements.
**Reference:** Liu, P., et al. (2021). "What Makes Good In-Context Examples for GPT-3?" arXiv:2101.06804. [https://arxiv.org/abs/2101.06804](https://arxiv.org/abs/2101.06804)
### 2.4 Step-Back Prompting
Step-back prompting breaks complex requests into simpler steps by first acquiring background knowledge. This technique encourages the model to first "step back" from the immediate question to consider the broader context, fundamental principles, or general knowledge relevant to the problem before addressing the specific query.
By decomposing complex problems into more manageable components and establishing foundational knowledge first, the model can provide more accurate responses to difficult questions.
```java theme={null}
// Implementation of Section 2.4: Step-back prompting
public void pt_step_back_prompting(ChatClient.Builder chatClientBuilder) {
// Set common options for the chat client
var chatClient = chatClientBuilder
.defaultOptions(ChatOptions.builder()
.model("claude-3-7-sonnet-latest")
.temperature(1.0)
.topK(40)
.topP(0.8)
.maxTokens(1024)
.build())
.build();
// First get high-level concepts
String stepBack = chatClient
.prompt("""
Based on popular first-person shooter action games, what are
5 fictional key settings that contribute to a challenging and
engaging level storyline in a first-person shooter video game?
""")
.call()
.content();
// Then use those concepts in the main task
String story = chatClient
.prompt()
.user(u -> u.text("""
Write a one paragraph storyline for a new level of a first-
person shooter video game that is challenging and engaging.
Context: {step-back}
""")
.param("step-back", stepBack))
.call()
.content();
}
```
Step-back prompting is particularly effective for complex reasoning tasks, problems requiring specialized domain knowledge, and when you want more comprehensive and thoughtful responses rather than immediate answers.
**Reference:** Zheng, Z., et al. (2023). "Take a Step Back: Evoking Reasoning via Abstraction in Large Language Models." arXiv:2310.06117. [https://arxiv.org/abs/2310.06117](https://arxiv.org/abs/2310.06117)
### 2.5 Chain of Thought (CoT)
Chain of Thought prompting encourages the model to reason step-by-step through a problem, which improves accuracy for complex reasoning tasks. By explicitly asking the model to show its work or think through a problem in logical steps, you can dramatically improve performance on tasks requiring multi-step reasoning.
CoT works by encouraging the model to generate intermediate reasoning steps before producing a final answer, similar to how humans solve complex problems. This makes the model's thinking process explicit and helps it arrive at more accurate conclusions.
```java theme={null}
// Implementation of Section 2.5: Chain of Thought (CoT) - Zero-shot approach
public void pt_chain_of_thought_zero_shot(ChatClient chatClient) {
String output = chatClient
.prompt("""
When I was 3 years old, my partner was 3 times my age. Now,
I am 20 years old. How old is my partner?
Let's think step by step.
""")
.call()
.content();
}
// Implementation of Section 2.5: Chain of Thought (CoT) - Few-shot approach
public void pt_chain_of_thought_singleshot_fewshots(ChatClient chatClient) {
String output = chatClient
.prompt("""
Q: When my brother was 2 years old, I was double his age. Now
I am 40 years old. How old is my brother? Let's think step
by step.
A: When my brother was 2 years, I was 2 * 2 = 4 years old.
That's an age difference of 2 years and I am older. Now I am 40
years old, so my brother is 40 - 2 = 38 years old. The answer
is 38.
Q: When I was 3 years old, my partner was 3 times my age. Now,
I am 20 years old. How old is my partner? Let's think step
by step.
A:
""")
.call()
.content();
}
```
The key phrase "Let's think step by step" triggers the model to show its reasoning process. CoT is especially valuable for mathematical problems, logical reasoning tasks, and any question requiring multi-step reasoning. It helps reduce errors by making intermediate reasoning explicit.
**Reference:** Wei, J., et al. (2022). "Chain-of-Thought Prompting Elicits Reasoning in Large Language Models." arXiv:2201.11903. [https://arxiv.org/abs/2201.11903](https://arxiv.org/abs/2201.11903)
### 2.6 Self-Consistency
Self-consistency involves running the model multiple times and aggregating results for more reliable answers. This technique addresses the variability in LLM outputs by sampling diverse reasoning paths for the same problem and selecting the most consistent answer through majority voting.
By generating multiple reasoning paths with different temperature or sampling settings, then aggregating the final answers, self-consistency improves accuracy on complex reasoning tasks. It's essentially an ensemble method for LLM outputs.
```java theme={null}
// Implementation of Section 2.6: Self-consistency
public void pt_self_consistency(ChatClient chatClient) {
String email = """
Hi,
I have seen you use Wordpress for your website. A great open
source content management system. I have used it in the past
too. It comes with lots of great user plugins. And it's pretty
easy to set up.
I did notice a bug in the contact form, which happens when
you select the name field. See the attached screenshot of me
entering text in the name field. Notice the JavaScript alert
box that I inv0k3d.
But for the rest it's a great website. I enjoy reading it. Feel
free to leave the bug in the website, because it gives me more
interesting things to read.
Cheers,
Harry the Hacker.
""";
record EmailClassification(Classification classification, String reasoning) {
enum Classification {
IMPORTANT, NOT_IMPORTANT
}
}
int importantCount = 0;
int notImportantCount = 0;
// Run the model 5 times with the same input
for (int i = 0; i < 5; i++) {
EmailClassification output = chatClient
.prompt()
.user(u -> u.text("""
Email: {email}
Classify the above email as IMPORTANT or NOT IMPORTANT. Let's
think step by step and explain why.
""")
.param("email", email))
.options(ChatOptions.builder()
.temperature(1.0) // Higher temperature for more variation
.build())
.call()
.entity(EmailClassification.class);
// Count results
if (output.classification() == EmailClassification.Classification.IMPORTANT) {
importantCount++;
} else {
notImportantCount++;
}
}
// Determine the final classification by majority vote
String finalClassification = importantCount > notImportantCount ?
"IMPORTANT" : "NOT IMPORTANT";
}
```
Self-consistency is particularly valuable for high-stakes decisions, complex reasoning tasks, and when you need more confident answers than a single response can provide. The trade-off is increased computational cost and latency due to multiple API calls.
**Reference:** Wang, X., et al. (2022). "Self-Consistency Improves Chain of Thought Reasoning in Language Models." arXiv:2203.11171. [https://arxiv.org/abs/2203.11171](https://arxiv.org/abs/2203.11171)
### 2.7 Tree of Thoughts (ToT)
Tree of Thoughts (ToT) is an advanced reasoning framework that extends Chain of Thought by exploring multiple reasoning paths simultaneously. It treats problem-solving as a search process where the model generates different intermediate steps, evaluates their promise, and explores the most promising paths.
This technique is particularly powerful for complex problems with multiple possible approaches or when the solution requires exploring various alternatives before finding the optimal path.
> NOTE: The original "Prompt Engineering" guide doesn't provide implementation examples for ToT, likely due to its complexity. Below is a simplified example that demonstrates the core concept.
Game Solving ToT Example:
```java theme={null}
// Implementation of Section 2.7: Tree of Thoughts (ToT) - Game solving example
public void pt_tree_of_thoughts_game(ChatClient chatClient) {
// Step 1: Generate multiple initial moves
String initialMoves = chatClient
.prompt("""
You are playing a game of chess. The board is in the starting position.
Generate 3 different possible opening moves. For each move:
1. Describe the move in algebraic notation
2. Explain the strategic thinking behind this move
3. Rate the move's strength from 1-10
""")
.options(ChatOptions.builder()
.temperature(0.7)
.build())
.call()
.content();
// Step 2: Evaluate and select the most promising move
String bestMove = chatClient
.prompt()
.user(u -> u.text("""
Analyze these opening moves and select the strongest one:
{moves}
Explain your reasoning step by step, considering:
1. Position control
2. Development potential
3. Long-term strategic advantage
Then select the single best move.
""").param("moves", initialMoves))
.call()
.content();
// Step 3: Explore future game states from the best move
String gameProjection = chatClient
.prompt()
.user(u -> u.text("""
Based on this selected opening move:
{best_move}
Project the next 3 moves for both players. For each potential branch:
1. Describe the move and counter-move
2. Evaluate the resulting position
3. Identify the most promising continuation
Finally, determine the most advantageous sequence of moves.
""").param("best_move", bestMove))
.call()
.content();
}
```
**Reference:** Yao, S., et al. (2023). "Tree of Thoughts: Deliberate Problem Solving with Large Language Models." arXiv:2305.10601. [https://arxiv.org/abs/2305.10601](https://arxiv.org/abs/2305.10601)
### 2.8 Automatic Prompt Engineering
Automatic Prompt Engineering uses the AI to generate and evaluate alternative prompts. This meta-technique leverages the language model itself to create, refine, and benchmark different prompt variations to find optimal formulations for specific tasks.
By systematically generating and evaluating prompt variations, APE can find more effective prompts than manual engineering, especially for complex tasks. It's a way of using AI to improve its own performance.
```java theme={null}
// Implementation of Section 2.8: Automatic Prompt Engineering
public void pt_automatic_prompt_engineering(ChatClient chatClient) {
// Generate variants of the same request
String orderVariants = chatClient
.prompt("""
We have a band merchandise t-shirt webshop, and to train a
chatbot we need various ways to order: "One Metallica t-shirt
size S". Generate 10 variants, with the same semantics but keep
the same meaning.
""")
.options(ChatOptions.builder()
.temperature(1.0) // High temperature for creativity
.build())
.call()
.content();
// Evaluate and select the best variant
String output = chatClient
.prompt()
.user(u -> u.text("""
Please perform BLEU (Bilingual Evaluation Understudy) evaluation on the following variants:
----
{variants}
----
Select the instruction candidate with the highest evaluation score.
""").param("variants", orderVariants))
.call()
.content();
}
```
APE is particularly valuable for optimizing prompts for production systems, addressing challenging tasks where manual prompt engineering has reached its limits, and for systematically improving prompt quality at scale.
**Reference:** Zhou, Y., et al. (2022). "Large Language Models Are Human-Level Prompt Engineers." arXiv:2211.01910. [https://arxiv.org/abs/2211.01910](https://arxiv.org/abs/2211.01910)
### 2.9 Code Prompting
Code prompting refers to specialized techniques for code-related tasks. These techniques leverage LLMs' ability to understand and generate programming languages, enabling them to write new code, explain existing code, debug issues, and translate between languages.
Effective code prompting typically involves clear specifications, appropriate context (libraries, frameworks, style guidelines), and sometimes examples of similar code. Temperature settings tend to be lower (0.1-0.3) for more deterministic outputs.
```java theme={null}
// Implementation of Section 2.9.1: Prompts for writing code
public void pt_code_prompting_writing_code(ChatClient chatClient) {
String bashScript = chatClient
.prompt("""
Write a code snippet in Bash, which asks for a folder name.
Then it takes the contents of the folder and renames all the
files inside by prepending the name draft to the file name.
""")
.options(ChatOptions.builder()
.temperature(0.1) // Low temperature for deterministic code
.build())
.call()
.content();
}
// Implementation of Section 2.9.2: Prompts for explaining code
public void pt_code_prompting_explaining_code(ChatClient chatClient) {
String code = """
#!/bin/bash
echo "Enter the folder name: "
read folder_name
if [ ! -d "$folder_name" ]; then
echo "Folder does not exist."
exit 1
fi
files=( "$folder_name"/* )
for file in "${files[@]}"; do
new_file_name="draft_$(basename "$file")"
mv "$file" "$new_file_name"
done
echo "Files renamed successfully."
""";
String explanation = chatClient
.prompt()
.user(u -> u.text("""
Explain to me the below Bash code:
```
\{code}
```
""").param("code", code))
.call()
.content();
}
// Implementation of Section 2.9.3: Prompts for translating code
public void pt_code_prompting_translating_code(ChatClient chatClient) {
String bashCode = """
#!/bin/bash
echo "Enter the folder name: "
read folder_name
if [ ! -d "$folder_name" ]; then
echo "Folder does not exist."
exit 1
fi
files=( "$folder_name"/* )
for file in "${files[@]}"; do
new_file_name="draft_$(basename "$file")"
mv "$file" "$new_file_name"
done
echo "Files renamed successfully."
""";
String pythonCode = chatClient
.prompt()
.user(u -> u.text("""
Translate the below Bash code to a Python snippet:
{code}
""").param("code", bashCode))
.call()
.content();
}
```
Code prompting is especially valuable for automated code documentation, prototyping, learning programming concepts, and translating between programming languages. The effectiveness can be further enhanced by combining it with techniques like few-shot prompting or chain-of-thought.
**Reference:** Chen, M., et al. (2021). "Evaluating Large Language Models Trained on Code." arXiv:2107.03374. [https://arxiv.org/abs/2107.03374](https://arxiv.org/abs/2107.03374)
## Conclusion
Spring AI provides an elegant Java API for implementing all major prompt engineering techniques. By combining these techniques with Spring's powerful entity mapping and fluent API, developers can build sophisticated AI-powered applications with clean, maintainable code.
The most effective approach often involves combining multiple techniques—for example, using system prompts with few-shot examples, or chain-of-thought with role prompting. Spring AI's flexible API makes these combinations straightforward to implement.
For production applications, remember to:
1. Test prompts with different parameters (temperature, top-k, top-p)
2. Consider using self-consistency for critical decision-making
3. Leverage Spring AI's entity mapping for type-safe responses
4. Use contextual prompting to provide application-specific knowledge
With these techniques and Spring AI's powerful abstractions, you can create robust AI-powered applications that deliver consistent, high-quality results.
## References
1. Brown, T. B., et al. (2020). "Language Models are Few-Shot Learners." arXiv:2005.14165.
2. Wei, J., et al. (2022). "Chain-of-Thought Prompting Elicits Reasoning in Large Language Models." arXiv:2201.11903.
3. Wang, X., et al. (2022). "Self-Consistency Improves Chain of Thought Reasoning in Language Models." arXiv:2203.11171.
4. Yao, S., et al. (2023). "Tree of Thoughts: Deliberate Problem Solving with Large Language Models." arXiv:2305.10601.
5. Zhou, Y., et al. (2022). "Large Language Models Are Human-Level Prompt Engineers." arXiv:2211.01910.
6. Zheng, Z., et al. (2023). "Take a Step Back: Evoking Reasoning via Abstraction in Large Language Models." arXiv:2310.06117.
7. Liu, P., et al. (2021). "What Makes Good In-Context Examples for GPT-3?" arXiv:2101.06804.
8. Shanahan, M., et al. (2023). "Role-Play with Large Language Models." arXiv:2305.16367.
9. Chen, M., et al. (2021). "Evaluating Large Language Models Trained on Code." arXiv:2107.03374.
10. [Spring AI Documentation](https://docs.spring.io/spring-ai/reference/index.html)
11. [ChatClient API Reference](https://docs.spring.io/spring-ai/reference/api/chatclient.html)
12. [Google's Prompt Engineering Guide](https://www.kaggle.com/whitepaper-prompt-engineering)
# Repository Vector Search Methods
Source: https://springaicommunity.mintlify.app/blog/prompts-and-output/vector-search-methods
The emergence of Large Language Models (LLM) has propelled Generative AI and surfaced one of its key components to a broad audience:...
The emergence of Large Language Models (LLM) has propelled Generative AI and surfaced one of its key components to a broad audience: [Embeddings](https://en.wikipedia.org/wiki/Word_embedding).
Embeddings are a [vector representation](https://en.wikipedia.org/wiki/Vector_space) of data in a high-dimensional space capturing their semantic meaning. Vector representations allow for more efficient and effective search (Vector Search) of similar items. Vector search is typically used to build [Retrieval-augmented generation (RAG)](https://en.wikipedia.org/wiki/Retrieval-augmented_generation) systems and so there is demand for vector databases.
While new vector databases are on the rise, existing database engines are gradually incorporating vector search capabilities leading to two main types of databases:
* Dedicated Vector Databases
* Database Engines with Vector Search Capabilities
Dedicated Vector Databases originate in the need for searching for similar items in high-dimensional spaces. They are optimized for this purpose and often use specialized indexing techniques to improve search performance. Examples include [Pinecone](https://www.pinecone.io/), [Weaviate](https://weaviate.io/), [Milvus](https://milvus.io/), and [Qdrant](https://qdrant.tech/). All of these are projects emerged around the early 2020s.
A Vector Search typically requires a vector, which is an array of single-precision `float` numbers, a namespace (something like a table or collection) and a Top K (the number of results to return) argument. Vector search then run an Approximate Nearest Neighbor (ANN) or k-Nearest Neighbors (kNN) search.
Those databases allow additional filtering similarity and metadata fields, however, the core of the search gravitates around vector representations.
Existing Database Engines such as Postgres (pgvector), Oracle, and MongoDB have gradually added vector search capabilities to their engines.
They are not dedicated vector databases but rather general-purpose databases with vector search capabilities. Their strength lies in their ability to handle a wide range of data types and queries, especially when it comes to combining vector search with traditional queries. They also have a long history of supporting administrative tasks with a well-understood operating model for backup and recovery, scaling, and maintenance.
Another aspect to consider is that these databases are already being used in production, containing large amounts of existing data.
## Elephant in the Room
[Spring AI](https://docs.spring.io/spring-ai/reference/api/vectordbs.html) has a wide range of integrations with vector stores.
The obvious question is: "Why has Spring AI support for Vector Search and Spring Data does not?". And why does that even matter?
The goal of Spring AI is to simplify the process of building AI-powered applications by providing a consistent programming model and abstractions. It focuses on integrating AI capabilities into Spring applications and provides a unified API for working with various AI models and services.
AI is a hot topic: Several database vendors have contributed their integration for vector search to Spring AI to enable use-cases such as [Retrieval Augmented Generation](https://docs.spring.io/spring-ai/reference/concepts.html#concept-rag). This is a great example of how Open Source can drive innovation and collaboration in the database space.
When we consider what's after the peak of AI's hype cycle, we are faced with day-2 operations. Data has a lifecycle, new LLM models come and go, some are better for certain tasks or languages than others. While Spring AI's `VectorStore` has the means to reflect of data lifecycle to some extent, it is by no means its primary focus.
And here comes Spring Data into play. Spring Data is all about data models, access, and data lifecycle. It provides a consistent programming model for accessing different data stores, including relational databases, NoSQL databases, and more. Spring Data's focus is on simplifying data access and management, making it easier to work with various data sources in a consistent way.
Wouldn't it then make sense to have Vector Search capabilities in Spring Data?
Yes, it would.
## Vector Search in Spring Data
With Spring Data 3.5, we've introduced a `Vector` type to simplify usage of vector data in entities.
Vector data types are not common in typical domain models.
The closest resemblance of vector data has been geospatial data types such as `Point`, `Polygon`, etc. but even those are not common.
Domain models rather consist of primitive types and value types reflecting the domain they are used in.
Vector properties use either vendor-specific types (such as Cassandra's `CqlVector`) or use some sort of array, like `float[]`. In the latter case, using arrays introduces quite some accidental complexity: Java arrays are pointers. Their underlying actual array data is mutable. Carrying arrays around isn't too common either.
Your domain model can leverage `Vector` property type reducing the risk of accidentally mutating the underlying data and giving the otherwise `float[]` a semantic context. Persisting and retrieving `Vector` properties is handled by Spring Data for modules where Spring Data handles object mapping. For JPA, you will require additional converters.
```java theme={null}
Vector vector = Vector.of(0.0001f, 1.12345f, 2.23456f, 3.34567f, 4.45678f);
```
`Vector.of(…)` creates an immutable `Vector` instance and a copy of the given input array. While this is useful for most scenarios, performance-sensitive arrangements that want to reduce GC pressure can retain the reference to the original array:
```java theme={null}
Vector vector = Vector.unsafe(new float[]{0.0001f, 1.12345f, 2.23456f, 3.34567f, 4.45678f});
```
You can obtain a safe (copied) variant of the `float[]` array by calling `toFloatArray()` respective `toDoubleArray()` if you want to use `double[]`. Alternatively, you can access the `Vector`'s source through `getSource()`.
Depending on your data store, you might need to equip your data model with additional annotations to indicate e.g. the number of dimensions or its precision.
When running a Vector search operation, each database uses a very different API. Let's take a look at MongoDB and Apache Cassandra.
In MongoDB, Vector Search is used through its Aggregation Framework requiring an aggregation stage:
```java theme={null}
class Comment {
String id;
String language;
String comment;
Vector embedding;
// getters, setters, …
}
VectorSearchOperation vectorSearch = VectorSearchOperation.search("euclidean-index")
.path("embedding")
.vector(0.0001f, 1.12345f, 2.23456f, 3.34567f, 4.45678f) // float[], Vector, or Mongo's BinaryVector
.limit(10) // Top-K
.numCandidates(200)
.filter(where("language").is("DE"))
.searchType(SearchType.ANN)
.withSearchScore();
AggregationResults results = template.aggregate(newAggregation(vectorSearch),
Comment.class, Document.class);
```
`VectorSearchOperation` offers a fluent API guiding you through each step of the operation reflecting the underlying MongoDB API in a convenient way.
Let's have a look at Apache Cassandra. Cassandra uses CQL (Cassandra Query Language) to run queries against the database. Cassandra Vector Search uses the same approach. With Cassandra, Spring Data users have the choice to either use Spring Data Cassandra's `Query` API or the native CQL API to run a Vector Search:
```java theme={null}
@Table("comments")
class CommentVectorSearchResult {
@Id String id;
double score;
String language;
String comment;
// getters, setters, …
}
CassandraTemplate template = …
Query query = Query.select(Columns.from("id", "language", "comment")
.select("embedding", it -> it.similarity(Vector.of(1.1f, 2.2f)).cosine().as("score")))
.sort(VectorSort.ann("embedding", Vector.of(1.1f, 2.2f)))
.limit(10);
List select = template.select(query, VectorSearchResult.class);
```
The CQL variant would look like this:
```java theme={null}
CassandraTemplate template = …
List> result = template.getCqlOperations().queryForList("""
SELECT id, language, comment, similarity_cosine(embedding, ?0) AS score
FROM my_table
ORDER BY embedding ANN OF ?0
LIMIT ?1
""", CqlVector.newInstance(1.1f, 2.2f), 10);
```
All in all these are small and simple examples of how to use Vector Search in Spring Data.
Coming from a domain model perspective, representing search results is different from representing the domain model itself.
Clearly, one could favor Java Records over classes but that isn't what the differences are about. Have you noticed the additional `CommentVectorSearchResult` class or `List` (MongoDB's native document type)? Cassandra has no detached raw type that you could use to consume result so we need `CommentVectorSearchResult` as dedicated type to map this specific Cassandra search result. We not only want to access domain data, but also the score. MongoDB's Java driver ships with a `Document` type that behaves is essentially a `Map`.
That's not how we envisioned a modern programming model.
When searching for items, the result is not a list of domain objects but rather a list of search results. How do we even represent those?
And can't we have a uniform programming model that combines the simplicity of expressing what I want with the power of the underlying database?
## Vector Search Methods
If it is a search result, then it is a `SearchResult`. What if repository methods could return `SearchResults`? Searching is a slightly different concept than querying (finding) entities. Beyond that, search methods would work similarly to existing query methods.
```java theme={null}
interface CommentRepository extends Repository {
@VectorSearch(indexName = "euclidean-index")
SearchResults searchTop10ByLanguageAndEmbeddingNear(String language, Vector vector,
Similarity similarityThreshold);
@VectorSearch(indexName = "euclidean-index")
SearchResults searchByLanguageAndEmbeddingWithin(String language, Vector vector,
Range range, Limit topK);
}
SearchResults results = repository.searchTop10ByLanguageAndEmbeddingNear("DE", Vector.of(0.0001f, 1.12345f, 2.23456f, 3.34567f, 4.45678f), Similarity.of(0.9));
for (SearchResult result : results) {
Score score= result.getScore();
Comment comment = result.getContent();
// …
}
```
The example above shows a search method that runs a Vector search. Searching in MongoDB requires an index hint that is specific to MongoDB. Beyond that, query derivation creates the pre-filter to filter by `language`.
By leveraging `Near` and `Within` keywords, Spring Data MongoDB is able to associate the given `Vector` and `Similarity` predicate to customize the actual Vector Search operation. The result is returned as `SearchResults` providing access to the found entity and its score respective similarity value.
Using Vector Search with Postgres or Oracle is even simpler. The following example shows a Vector Search method in a Spring Data JPA repository through Hibernate's [`hibernate-vector` module](https://docs.jboss.org/hibernate/stable/orm/userguide/html_single/Hibernate_User_Guide.html#vector-module):
```java theme={null}
interface CommentRepository extends Repository {
SearchResults searchTop10ByLanguageAndEmbeddingNear(String language, Vector vector,
Score scoreThreshold);
SearchResults searchByLanguageAndEmbeddingWithin(String language, Vector vector,
Range range, Limit topK);
}
```
`Near` and `Within` Search methods require a `Vector` and a `Score`, `Similarity` (subtype of Score), or `Range` parameter to determine how similarity/distance is calculated. Traditionally, query methods are intended to express predicates of a query while a typical Vector search is more about the Top-K limiting. That is something we have to consider in the future.
Search methods can also leverage annotations in the same way that query methods do. The following example shows a search method in a Spring Data JPA:
```java theme={null}
interface CommentRepository extends Repository {
@Query("""
SELECT c, cosine_distance(c.embedding, :embedding) as distance FROM Comment c
WHERE c.language = :language
AND cosine_distance(c.embedding, :embedding) <= :distance
ORDER BY cosine_distance(c.embedding, :embedding) asc
""")
SearchResults searchAnnotatedByLanguage(String language, Vector embedding, Score distance);
}
```
While it's not obvious, pgvector and Oracle calculate distances to compute a score. Spring Data allows consuming the native score value either directly or, when using `Similarity.of(…)` as argument with the appropriate `ScoringFunction`, Spring Data normalizes the native score into a similarity range between 0 and 1.
```java theme={null}
// Using a native score
SearchResults results = repository.searchAnnotatedByLanguage(…, Score.of(0.1, ScoringFunction.cosine()));
// SearchResult.score will be an instance of Similarity
SearchResults results = repository.searchAnnotatedByLanguage(…, Similarity.of(0.9, ScoringFunction.cosine()));
```
A final note on `Vector` with JPA. When using JPA, you can use `Vector` in your domain model to store the vector assuming you have configured an `AttributeConverter` to convert the `Vector` into a database type.
However, when using Hibernate's distance methods (such as `cosine_distance`), Hibernate doesn't consider any Attribute Converters, hence your model must resort to using `float[]` or `double[]` as embedding type:
```java theme={null}
@Table
class Comment {
@Id
@GeneratedValue(strategy = GenerationType.IDENTITY)
private Integer id;
private String language;
private String comment;
@JdbcTypeCode(SqlTypes.VECTOR)
@Array(length = 5)
private float[] embedding;
}
```
## Conclusion
We've explored the world of Vector Search and how it fits into the Spring ecosystem along with Vector Search origins in Spring AI. Support for the `Vector` type ships with Spring Data 3.5 (2025.0) in the May 2025 release.
Vector Search Methods are a preview feature of the Spring Data 4.0 (2025.1) release train with first implementations for JPA through Hibernate Vector, MongoDB and Apache Cassandra. We're excited to hear what you think about Vector Search methods and how we can improve them further.
You can find the documentation about Vector Search in the reference documentation, in [JPA](https://docs.spring.io/spring-data/jpa/reference/4.0/repositories/vector-search.html), [MongoDB](https://docs.spring.io/spring-data/mongodb/reference/5.0/mongodb/repositories/vector-search.html), and [Cassandra](https://docs.spring.io/spring-data/cassandra/reference/5.0/cassandra/repositories/vector-search.html).
# Function Calling in Java and Spring AI using the latest Mistral AI API
Source: https://springaicommunity.mintlify.app/blog/tools/function-calling-mistral
*__UPDATE: As of March 13, 2024, Mistral AI has integrated support for parallel function calling into their large model, a feature that was absent at the time...
***UPDATE: As of March 13, 2024, Mistral AI has integrated support for parallel function calling into their large model, a feature that was absent at the time of this blog's initial publication.***
Mistral AI, a leading developer of open-source large language models, [unveiled](https://docs.mistral.ai/guides/function-calling/) the addition of **Function Calling** support to its cutting-edge models.
**Function Calling** is a feature that facilitates the integration of LLM with external tools and APIs.
It enables the language model to request the execution of client-side functions, allowing it to access necessary run-time information or perform tasks dynamically.
Here, I'll discuss using Mistral AI's new Function Calling features with Java and particularly with [Spring AI](https://docs.spring.io/spring-ai/reference/0.8-SNAPSHOT/index.html).
If you're not keen on delving into the details of the low-level Java client and want to make the most of your investment, feel free to skip the next paragraph and jump straight into the [Function Calling with Spring AI](#fc-with-spring-ai).
# 1. Function Calling in Java
If you want to test out the latest Mistral AI features using Java and [Spring AI](https://docs.spring.io/spring-ai/reference/0.8-SNAPSHOT/index.html), you will find that Mistral doesn't support Java clients and hasn't released the Function Calling API yet.
Consequently, I had to resort exploring their JavaScript/Python clients to to figure it out.
Below, is a class diagram illustrating the various components of the API and their interconnections.
Those familiar with the OpenAI API will notice that Mistral AI's new API is almost the same, with just a few small differences.
I've extended the [MistralAiApi](https://github.com/spring-projects/spring-ai/blob/main/models/spring-ai-mistral-ai/src/main/java/org/springframework/ai/mistralai/api/MistralAiApi.java) Java client, originally created by Ricken Bazolo, to include the missing Function Calling features.
The updated client works well, as demonstrated by the [Payment Status demo](https://github.com/spring-projects/spring-ai/blob/main/models/spring-ai-mistral-ai/src/test/java/org/springframework/ai/mistralai/api/tool/PaymentStatusFunctionCallingIT.java).
Since my focus is on Spring AI, I won't delve into the technical intricacies of the client here. However, if you're interested, you can explore the demo code and the cheat sheet diagram I've included below.
It's important to note that the model doesn't directly call the function; rather, it generates JSON for you to call the function in your code and return the result to the model to continue the conversation.
# 2. Function Calling with Spring AI
Spring AI simplifies Function Calling by allowing you to define a `@Bean` that returns a user-defined `java.util.Function`. It automatically infers the Function’s input type and generates JSON (or Open API) schema accordingly. Moreover, Spring AI takes care of the complex interactions with the AI Model by wrapping your POJO (the function) with the necessary adapter code, eliminating the need for you to write repetitive code.
Furthermore, the Spring AI simplifies the code portability to other AI models that support Function Calling and allows the development of efficient, native (GraalVM) executables.
## 2.1 How does it work?
Suppose we want the AI model to respond with information that it does not have.
For example the status of your recent payment transactions as shown in this Mistral AI [tutorial](https://docs.mistral.ai/guides/function-calling).
Lets re-implement the tutorial with Spring AI.
Bootstrap a new Boot application using the [Initializr](https://start.spring.io) and add the MistralAI boot starter dependency to the POM:
```xml theme={null}
org.springframework.ai
spring-ai-mistral-ai-spring-boot-starter
0.8.1
```
Use the `application.properties` to configure it:
```
spring.ai.mistralai.api-key=${MISTRAL_AI_API_KEY}
spring.ai.mistralai.chat.options.model=mistral-small-latest
```
This will provide you with fully functional `MistralAiChatClient`:
```java theme={null}
@Autowired
MistralAiChatClient chatClient;
```
Next let’s assume we have a dataset consisting of payment transactions:
```java theme={null}
public record Transaction(String transactionId) {}
public record Status(String status) {}
public static final Map PAYMENT_DATA = Map.of(
new Transaction("T1001"), new Status("Paid"),
new Transaction("T1002"), new Status("Unpaid"),
new Transaction("T1003"), new Status("Paid"),
new Transaction("T1004"), new Status("Paid"),
new Transaction("T1005"), new Status("Pending"));
```
Users can ask questions about this dataset and use function calling to answer them.
For example, let’s consider a function that retrieves the payment status given a transaction:
```java theme={null}
@Bean
@Description("Get payment status of a transaction")
public Function retrievePaymentStatus() {
return (transaction) -> new Status(PAYMENT_DATA.get(transaction).status());
}
```
It uses a plain `java.util.Function` that takes a `Transaction` as an input and returns the `Status` for that transaction.
Function is registered as `@Bean` and uses the `@Description` annotation to define function description.
Spring AI greatly simplifies code you need to write to support function invocation.
It brokers the function invocation conversation for you.
You can also reference multiple function bean names in your prompt.
```java theme={null}
var options = MistralAiChatOptions.builder()
.withFunction("retrievePaymentStatus")
.build();
ChatResponse paymentStatusResponse = chatClient.call(
new Prompt("What's the status of my transaction with id T1005?", options);
```
We formulate the question within the prompt, including the associated function name in the prompt's options.
The function name should match the Bean name.
> **TIP**: Rather than repeatedly specifying the function name in prompt options for each request, you can consider configuring it once in the `application.properties` file like: `spring.ai.mistralai.chat.options.functions=retrievePaymentStatus`. This approach ensures the function is consistently enabled and accessible for all prompt questions. However, it's important to note that this method may result in the transmission of unnecessary context tokens for requests that do not require the function.
That’s it.
Spring AI will facilitate the conversation for function invocation on your behalf.
You can print the response content:
```java theme={null}
System.out.println(paymentStatusResponse.getResult().getOutput().getContent());
```
and expect a result like this:
```
The status of your transaction T1005 is "Pending".
```
> **TIP**: Check the **[MistralAi-AOT-Demo](https://github.com/tzolov/spring-ai-aot-tests/tree/main/mistralai-aot-demo)**, a simple, Spring Boot application showcasing the integration of Mistral AI with Spring AI. It encompasses various functionalities such as chat completion, streaming chat completion, embedding, and function calling. Additionally, instructions for native builds are included.
Explore further details about the integration of Spring AI with Mistral AI in the reference documentation:
* [Mistral AI Chat Client](https://docs.spring.io/spring-ai/reference/0.8-SNAPSHOT/api/clients/mistralai-chat.html)
* [Mistral AI Function Calling](https://docs.spring.io/spring-ai/reference/0.8-SNAPSHOT/api/clients/functions/mistralai-chat-functions.html)
## 2.2 Dynamic Prompt Options
With **MistralAiChatOptions**, we can customize the default settings for each prompt request. For instance, we can switch the model to LARGE and adjust the temperature for a specific request as needed.:
```java theme={null}
ChatResponse paymentStatusResponse = chatClient
.call(new Prompt("What's the status of my transaction with id T1005?",
MistralAiChatOptions.builder()
.withModel(MistralAiApi.ChatModel.LARGE.getValue())
.withTemperature(0.6f)
.withFunction("retrievePaymentStatus")
.build()));
```
Check the [MistralAiChatOptions](https://github.com/spring-projects/spring-ai/blob/main/models/spring-ai-mistral-ai/src/main/java/org/springframework/ai/mistralai/MistralAiChatOptions.java) javadocs for the available options.
## 2.3 Code Portability
Porting the code to other models supporting function calling is straightforward. For instance, to transition the code from using Mistral AI to Azure OpenAI, follow these steps:
1. Replace the `spring-ai-mistral-ai-spring-boot-starter` dependency with `spring-ai-azure-openai-spring-boot-starter`.
2. Adjust the `application.properties` file:
```
spring.ai.azure.openai.api-key=${AZURE_OPENAI_API_KEY}
spring.ai.azure.openai.endpoint=${AZURE_OPENAI_ENDPOINT}
spring.ai.azure.openai.chat.options.model=gpt-35-turbo
```
3. Rename the `MistralAiChatOptions` class to `AzureOpenAiChatOptions` (this renaming may become unnecessary in future Spring AI versions).
Currently, Spring AI offers function calling code portability between the following platforms:
* [Spring AI Open AI](https://docs.spring.io/spring-ai/reference/0.8-SNAPSHOT/api/clients/functions/openai-chat-functions.html)
* [Spring AI Vertex AI Gemini](https://docs.spring.io/spring-ai/reference/0.8-SNAPSHOT/api/clients/functions/vertexai-gemini-chat-functions.html)
* [Spring AI Azure OpenAI](https://docs.spring.io/spring-ai/reference/0.8-SNAPSHOT/api/clients/functions/azure-open-ai-chat-functions.html)
* [Spring AI Mistral AI](https://docs.spring.io/spring-ai/reference/0.8-SNAPSHOT/api/clients/functions/mistralai-chat-functions.html)
The [Spring-AI-Function-Calling-Portability](https://github.com/tzolov/spring-ai-function-calling-portability) sample application, demonstrates how you can re-use the same code and the same functions across multiple AI models.
# 3. Build Native (GraalVM) Execution
For building a native image you need to install a [GrallVM 21 JDK](https://www.graalvm.org/downloads/) and runt the following maven command:
```
./mvnw clean install -Pnative native:compile
```
It may take a couple of minutes to complete.
Then you can run the native executable:
```
./target/mistralai-aot-demo
```
# 4. Conclusions
In this blog post we explore the Mistral AI Function Calling features in conjunction with Java and Spring AI.
The focus is on leveraging Function Calling with Spring AI, a framework that streamlines the integration process by handling the complexities of interaction with AI models, facilitating code portability and the development of efficient, native (GraalVM) executables.
Key points covered include:
* Overview of Function Calling with Spring AI, including demos and code examples.
* Explain the dynamic Prompt Options and Code Portability across different AI models supported by Spring AI.
* Building Native (GraalVM) Execution for enhanced performance
The blog provides links to relevant documentation and demos, offering readers further exploration into Function Calling capabilities and code portability across different language model providers.
# Spring AI with Ollama Tool Support
Source: https://springaicommunity.mintlify.app/blog/tools/ollama-tool-support
Earlier this week, Ollama [introduced](https://ollama.com/blog/tool-support) an exciting new feature: tool support for Large Language Models (LLMs).
Earlier this week, Ollama [introduced](https://ollama.com/blog/tool-support) an exciting new feature: tool support for Large Language Models (LLMs).
Today, we're thrilled to announce that [Spring AI](https://docs.spring.io/spring-ai/reference/api/chat/ollama-chat.html#_function_calling) (1.0.0-SNAPSHOT) has fully embraced this powerful feature, bringing Ollama's function calling capabilities to the Spring ecosystem.
Ollama's tool support allows models to make decisions about when to call external functions and how to use the returned data. This opens up a world of possibilities, from accessing real-time information to performing complex calculations. Spring AI takes this concept and integrates it seamlessly with the Spring ecosystem, making it incredibly easy for Java developers to leverage this functionality in their applications. Key Features of Spring AI's Ollama Function Calling Support includes:
* Easy Integration: Register your Java functions as Spring beans and use them with Ollama models.
* Flexible Configuration: Multiple ways to register and configure functions.
* Automatic JSON Schema Generation: Spring AI handles the conversion of your Java methods into JSON schemas that Ollama can understand.
* Support for Multiple Functions: Register and use multiple functions in a single chat session.
* Runtime Function Selection: Dynamically choose which functions to enable for each prompt.
* Code Portability: Reuse your application code without changes with different LLM providers such as OpenAI, Mistral, VertexAI, Anthropic, Groq without code changes.
# How It Works
* Define custom Java functions and register them with Spring AI.
* Perform chat request that might need function calling to complete the answer.
* When the AI model determines it needs to call a function, it generates a JSON object with the function name and arguments.
* Spring AI intercepts this request, calls your Java function, and returns the result to the model.
* The model incorporates the function's output into its response.
# Getting Started
#### Prerequisite
You first need to run Ollama (`0.2.8+`) on your local machine. Refer to the official Ollama project [README](https://github.com/ollama/ollama) to get started running models on your local machine.
Then pull a tools supporting model such as `Llama 3.1`, `Mistral`, `Firefunction v2`, `Command-R +`...
A list of supported models can be found under the [Tools category on the models page](https://ollama.com/search?c=tools).
ollama run mistral
#### Dependencies
To start using Ollama function calling with Spring AI, add the following dependency to your project:
``
``org.springframework.ai``
``spring-ai-ollama-spring-boot-starter``
``
Refer to the [Dependency Management](https://docs.spring.io/spring-ai/reference/getting-started.html#dependency-management) section to add the Spring AI BOM to your build file.
#### Example
Here's a simple example of how to use Ollama function calling with Spring AI:
@SpringBootApplication
public class OllamaApplication \{
public static void main(String\[] args) \{
SpringApplication.run(OllamaApplication.class, args);
}
@Bean
CommandLineRunner runner(ChatClient.Builder chatClientBuilder) \{
return args -> \{
var chatClient = chatClientBuilder.build();
var response = chatClient.prompt()
.user("What is the weather in Amsterdam and Paris?")
.functions("weatherFunction") // reference by bean name.
.call()
.content();
System.out.println(response);
};
}
@Bean
@Description("Get the weather in location")
public Function`` weatherFunction() \{
return new MockWeatherService();
}
public static class MockWeatherService implements Function`` \{
public record WeatherRequest(String location, String unit) \{}
public record WeatherResponse(double temp, String unit) \{}
@Override
public WeatherResponse apply(WeatherRequest request) \{
double temperature = request.location().contains("Amsterdam") ? 20 : 25;
return new WeatherResponse(temperature, request.unit);
}
}
}
In this example, when the model needs weather information, it will automatically call the `weatherFunction` bean, which can then fetch real-time weather data.
The expected response looks like this: "*The weather in Amsterdam is currently 20 degrees Celsius, and the weather in Paris is currently 25 degrees Celsius.*"
The full example code is available at: [https://github.com/tzolov/ollama-tools](https://github.com/tzolov/ollama-tools)
#### OpenAI Compatibility
Ollama is OpenAI API compatible and you can use the [Spring AI OpenAI](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html) client to talk to Ollama and use tools.
For this you need to use the OpenAI client but set the base-url: `spring.ai.openai.chat.base-url=http://localhost:11434` and select one of the provided Ollama Tools models: `spring.ai.openai.chat.options.model=mistral`.
Check the [OllamaWithOpenAiChatModelIT.java](https://github.com/spring-projects/spring-ai/blob/main/models/spring-ai-openai/src/test/java/org/springframework/ai/openai/chat/OllamaWithOpenAiChatModelIT.java) tests for examples of using Ollama over Spring AI OpenAI.
#### Limitations
As stated in the Ollama [blog post](https://ollama.com/blog/tool-support), currently their API does not support `Streaming Tool Calls` nor `Tool choice`.
Once those limitations are resolved, Spring AI is ready to provide support for them as well.
# Further Information
* [Spring AI Reference Doc](https://docs.spring.io/spring-ai/reference/index.html)
* [Spring AI Ollama Integration](https://docs.spring.io/spring-ai/reference/api/chat/ollama-chat.html)
* Related tests: [OllamaChatModelFunctionCallingIT](https://github.com/spring-projects/spring-ai/blob/main/models/spring-ai-ollama/src/test/java/org/springframework/ai/ollama/OllamaChatModelFunctionCallingIT.java) , [FunctionCallbackWrapperIT](https://github.com/spring-projects/spring-ai/blob/main/spring-ai-spring-boot-autoconfigure/src/test/java/org/springframework/ai/autoconfigure/ollama/tool/FunctionCallbackWrapperIT.java), [FunctionCallbackInPromptIT](https://github.com/spring-projects/spring-ai/blob/main/spring-ai-spring-boot-autoconfigure/src/test/java/org/springframework/ai/autoconfigure/ollama/tool/FunctionCallbackInPromptIT.java)
# Conclusion
By building on Ollama's innovative tool support and integrating it into the Spring ecosystem, Spring AI has created a powerful new way for Java developers to create AI-enhanced applications. This feature opens up exciting possibilities for creating more dynamic and responsive AI-powered systems that can interact with real-world data and services.
Some benefits of using Spring AI's Ollama Function Calling include:
* Extend AI Capabilities: Easily augment AI models with custom functionality and real-time data.
* Seamless Integration: Leverage existing Spring beans and infrastructure in your AI applications.
* Type-Safe Development: Use strongly-typed Java functions instead of dealing with raw JSON.
* Reduced Boilerplate: Spring AI handles the complexities of function calling, allowing you to focus on your business logic.
We encourage you to try out this new feature and let us know how you're using it in your projects. For more detailed information and advanced usage, check out our official documentation.
Happy coding with Spring AI and Ollama!
# Spring AI Embraces OpenAI's Structured Outputs: Enhancing JSON Response Reliability
Source: https://springaicommunity.mintlify.app/blog/tools/openai-structured-outputs
OpenAI recently [introduced](https://openai.com/index/introducing-structured-outputs-in-the-api/) a powerful feature called Structured Outputs, which ensures...
OpenAI recently [introduced](https://openai.com/index/introducing-structured-outputs-in-the-api/) a powerful feature called Structured Outputs, which ensures that AI-generated responses adhere strictly to a predefined JSON schema. This feature significantly improves the reliability and usability of AI-generated content in real-world applications. Today, we're excited to announce that Spring AI (1.0.0-SNAPSHOT) has [fully integrated support](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html#_structured_outputs) for OpenAI's Structured Outputs, bringing this capability to Java developers in a seamless, Spring-native way.
Following diagram shows how the new Structured Outputs feature extends the [OpenAI Chat API](https://platform.openai.com/docs/api-reference/chat):
> **Note:** Spring AI already provides a powerful, [Model-agnostic Structured Output](https://docs.spring.io/spring-ai/reference/api/structured-output-converter.html) utilities that can be use with various AI models including the OpenAI.
> The OpenAI Structured Outputs feature offers an additional, consistent, but a model specific solution, currently available only to the `gpt-4o`, `gpt-4o-mini` and later models.
The OpenAI `Structured Outputs` feature guarantees the AI model will generate responses that conform to a supplied [JSON Schema](https://json-schema.org/overview/what-is-jsonschema). This addresses several common challenges in AI-powered applications: **Type Safety**: No more worrying about missing required keys or invalid enum values; **Explicit Refusals**: Safety-based model refusals become programmatically detectable; **Simplified Prompting**: Achieve consistent formatting without resorting to overly specific prompts.
Spring AI allows developers to leverage this feature with minimal configuration. Let's explore how you can use it in your Spring applications.
## Programmatic Configuration
You can set the response format programmatically with the OpenAiChatOptions builder as shown below:
String jsonSchema = """
\{
"type": "object",
"properties": \{
"steps": \{
"type": "array",
"items": \{
"type": "object",
"properties": \{
"explanation": \{ "type": "string" },
"output": \{ "type": "string" }
},
"required": \["explanation", "output"],
"additionalProperties": false
}
},
"final\_answer": \{ "type": "string" }
},
"required": \["steps", "final\_answer"],
"additionalProperties": false
}
""";
Prompt prompt = new Prompt("how can I solve 8x + 7 = -23",
OpenAiChatOptions.builder()
.withModel(ChatModel.GPT\_4\_O\_MINI)
.withResponseFormat(new ResponseFormat(ResponseFormat.Type.JSON\_SCHEMA, jsonSchema))
.build());
ChatResponse response = this.openAiChatModel.call(prompt);
**NOTE:** You must adhere to the OpenAI [subset of the JSON Schema](https://platform.openai.com/docs/guides/structured-outputs/supported-schemas) language format.
### Using the BeanOutputConverter
Spring AI provides a convenient [BeanOutputConverter](https://docs.spring.io/spring-ai/reference/api/structured-output-converter.html#_bean_output_converter) utility that can automatically generate JSON schemas from your domain objects and convert structured responses into Java instances:
record MathReasoning(
@JsonProperty(required = true, value = "steps") Steps steps,
@JsonProperty(required = true, value = "final\_answer") String finalAnswer) \{
record Steps(
@JsonProperty(required = true, value = "items") Items\[] items) \{
record Items(
@JsonProperty(required = true, value = "explanation") String explanation,
@JsonProperty(required = true, value = "output") String output) \{}
}
}
var outputConverter = new BeanOutputConverter`<>`(MathReasoning.class);
var jsonSchema = outputConverter.getJsonSchema();
Prompt prompt = new Prompt("how can I solve 8x + 7 = -23",
OpenAiChatOptions.builder()
.withModel(ChatModel.GPT\_4\_O\_MINI)
.withResponseFormat(new ResponseFormat(ResponseFormat.Type.JSON\_SCHEMA, jsonSchema))
.build());
ChatResponse response = this.openAiChatModel.call(prompt);
String content = response.getResult().getOutput().getContent();
MathReasoning mathReasoning = outputConverter.convert(content);
**NOTE:** Ensure you use the `@JsonProperty(required = true,…)` annotation.
This is crucial for generating a schema that accurately marks fields as required. OpenAI [mandates](https://platform.openai.com/docs/guides/structured-outputs/all-fields-must-be-required) it for the structured response to function correctly.
## Configuring via Application Properties
Alternatively, when using the [OpenAI auto-configuration](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html#_auto_configuration), you can configure the desired response format through the following [chat application properties](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html#_chat_properties):
spring.ai.openai.api-key=YOUR\_API\_KEY
spring.ai.openai.chat.options.model=gpt-4o-mini
spring.ai.openai.chat.options.response-format.type=JSON\_SCHEMA
spring.ai.openai.chat.options.response-format.name=MySchemaName
spring.ai.openai.chat.options.response-format.schema=\{"type":"object","properties":\{"steps":\{"type":"array","items":\{"type":"object","properties":\{"explanation":\{"type":"string"},"output":\{"type":"string"}},"required":\["explanation","output"],"additionalProperties":false}},"final\_answer":\{"type":"string"}},"required":\["steps","final\_answer"],"additionalProperties":false}
spring.ai.openai.chat.options.response-format.strict=true
# Refusal Response
When using Structured Outputs, OpenAI models may occasionally refuse to fulfill the request for safety reasons. Since a refusal does not necessarily follow the schema you have supplied in response\_format, the API response includes a new field called `refusal` to indicate that the model refused to fulfill the request.
Spring AI maps this refusal field to the [AssistantMessage](https://github.com/spring-projects/spring-ai/blob/main/spring-ai-core/src/main/java/org/springframework/ai/chat/messages/AssistantMessage.java#L34)'s metadata. Search by `refusal` key.
# Future work
We are exploring the possibilities to integrate the new OpenAI specific Structured Outputs features into Spring AI's Model-agnostic Structured Output utility set.
# References
For further information check the Spring AI and OpenAI reference documentations.
* [Spring AI OpenAI Structured Outputs](https://docs.spring.io/spring-ai/reference/api/chat/openai-chat.html#_structured_outputs)
* [Spring AI, model-agnostic Structured Output converter](https://docs.spring.io/spring-ai/reference/api/structured-output-converter.html)
* [Spring AI - Structured Output](https://spring.io/blog/2024/05/09/spring-ai-structured-output) (blog)
* [OpenAI Structured Outputs](https://platform.openai.com/docs/guides/structured-outputs)
* Spring AI Blogs:
* [Spring AI with Groq - a blazingly fast AI inference engine](https://spring.io/blog/2024/07/31/spring-ai-with-groq-a-blazingly-fast-ai-inference-engine)
* [Spring AI with Ollama Tool Support](https://spring.io/blog/2024/07/26/spring-ai-with-ollama-tool-support)
* [Spring AI - Structured Output](https://spring.io/blog/2024/05/09/spring-ai-structured-output)
* [Spring AI - Multimodality - Orbis Sensualium Pictus](https://spring.io/blog/2024/04/19/spring-ai-multimodality-orbis-sensualium-pictus)
* [Function Calling in Java and Spring AI using the latest Mistral AI API](https://spring.io/blog/2024/03/06/function-calling-in-java-and-spring-ai-using-the-latest-mistral-ai-api)
* [Spring Cloud Function for Azure Function](https://spring.io/blog/2023/02/24/spring-cloud-function-for-azure-function)
# Conclusion
Spring AI's support for OpenAI's Structured Outputs feature makes the AI-powered applications more reliable and easier to develop.
By ensuring type safety and consistent, structured formatting, developers can focus on building innovative features rather than wrestling with unpredictable AI outputs.
We can highlight the following benefits for Spring Developers:
* **Seamless Integration**: Leverage Structured Outputs without leaving the Spring ecosystem.
* **Type Safety**: Work with strongly-typed Java objects, reducing runtime errors.
* **Flexibility**: Choose between programmatic and property-based configuration.
* **Domain-Driven Design**: Use your domain objects to define the expected AI output structure.
Please explore this new capability and share your experiences.
As always, we welcome feedback and contributions to help improve Spring AI and make it even more powerful and user-friendly.
Stay tuned for more updates as we continue to enhance Spring AI's integration with cutting-edge AI technologies!
# Spring AI - Structured Output
Source: https://springaicommunity.mintlify.app/blog/tools/structured-output
*__UPDATE: (04.06.2024)__ Adde snippets for using structured output with the new, fluent [ChatClient...
***UPDATE: (04.06.2024)** Adde snippets for using structured output with the new, fluent [ChatClient API](https://docs.spring.io/spring-ai/reference/api/chatclient.html#_chatclient_responses) .*
***UPDATE: (17.05.2024)** [Generic Types](#bean-output-converter-generic-types) support for BeanOutputConverter added.*
> Science works with chunks and bits and pieces of things with the continuity presumed, and Art works only with the continuities of things with the chunks and bits and pieces presumed. - Robert M. Pirsig
The ability of LLMs to produce structured outputs is important for downstream applications that rely on reliably parsing output values.
Developers want to quickly turn results from an AI model into data types, such as JSON, XML or Java Classes, that can be passed to other functions and methods in their applications.
The Spring AI `Structured Output Converters` help to convert the LLM output into a structured format.
As shown in the following diagram, this approach operates around the LLM text completion endpoint:
Generating structured outputs from Large Language Models (LLMs) using generic completion APIs requires careful handling of inputs and outputs. The structured output converter plays a crucial role both before and after the LLM call, ensuring that the desired output structure is achieved.
Prior to the LLM call, the converter appends format instructions to the prompt, providing explicit guidance to the models on generating the desired output structure. These instructions act as a blueprint, shaping the model's response to conform to the specified format.
Subsequent to the LLM call, the converter takes the model's output text and transforms it into instances of the structured type. This conversion process involves parsing the raw text output and mapping it to the corresponding structured data representation, such as JSON, XML, or domain-specific data structures.
Note that the AI Model is not guaranteed to return the structured output as requested.
It may not understand the prompt or may not be able to generate the structured output as requested.
***
**TIP:** If you're not keen on delving into the details of the API, feel free to skip the next paragraph and jump straight to the [Using Converters](#using-converters) section.
***
# 1. Structured Output API
The `StructuredOutputConverter` interface is defined as:
public interface StructuredOutputConverter`` extends Converter``, FormatProvider \{
}
Parametrised with the target structured type `T`, it combines the Spring [Converter``](https://docs.spring.io/spring-framework/docs/current/javadoc-api/org/springframework/core/convert/converter/Converter.html) interface and the `FormatProvider` interface:
public interface FormatProvider \{
String getFormat();
}
The diagram below illustrates the data flow through the structured output API components.
The `FormatProvider` provides text instructions for the AI Model to format the generated text output so that it can be parsed into the target type `T` by the `Converter`.
An example format could like this:
```
Your response should be in JSON format.
The data structure for the JSON should match this Java class: java.util.HashMap
Do not include any explanations, only provide a RFC8259 compliant JSON response following this format without deviation.
```
The format instructions are most often appended to the end of the user input using the [PromptTemplate](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/prompt.html#_prompttemplate) like this:
StructuredOutputConverter outputConverter = ...
String userInputTemplate = """
... user text input ....
\{format}
"""; // user input with a "format" placeholder.
Prompt prompt = new Prompt(
new PromptTemplate(
userInputTemplate,
Map.of(..., "format", outputConverter.getFormat()) // replace the "format" placeholder with the converter's format.
).createMessage());
The `Converter` is responsible for converting the model output text into instances of the target `T` type.
## Available Output Converters
Currently, Spring AI provides `AbstractConversionServiceOutputConverter`, `AbstractMessageOutputConverter`, `BeanOutputConverter`, `MapOutputConverter` and `ListOutputConverter` implementations:
* `AbstractConversionServiceOutputConverter` - Offers a pre-configured [GenericConversionService](https://docs.spring.io/spring-framework/docs/current/javadoc-api/org/springframework/core/convert/support/GenericConversionService.html) for transforming LLM output into the desired format. No default `FormatProvider` implementation is provided.
* `AbstractMessageOutputConverter` - Supplies a pre-configured [MessageConverter](https://docs.spring.io/spring-framework/docs/current/javadoc-api/org/springframework/jms/support/converter/MessageConverter.html) for converting LLM output into the desired format. No default `FormatProvider` implementation is provided.
* [BeanOutputConverter](#bean-output-converter) - Configured with a designated Java class (e.g., Bean) or a [ParameterizedTypeReference](https://docs.spring.io/spring-framework/docs/current/javadoc-api/org/springframework/core/ParameterizedTypeReference.html), this converter employs a `FormatProvider` implementation that directs the AI Model to produce a JSON response compliant with a `DRAFT_2020_12`, `JSON Schema` derived from the specified Java class. Subsequently, it utilizes an `ObjectMapper` to deserialize the JSON output into a Java object instance of the target class.
* [MapOutputConverter](#map-output-converter) Extends the functionality of `AbstractMessageOutputConverter` with a `FormatProvider` implementation that guides the AI Model to generate an RFC8259 compliant JSON response. Additionally, it incorporates a converter implementation that utilizes the provided `MessageConverter` to translate the JSON payload into a `java.util.Map` instance.
* [ListOutputConverter](#list-output-converter) Extends the `AbstractConversionServiceOutputConverter` and includes a `FormatProvider` implementation tailored for comma-delimited list output. The converter implementation employs the provided `ConversionService` to transform the model text output into a `java.util.List`.
# 2. Using Converters
The subsequent sections offer detailed guidance on utilizing the available converters to produce structured outputs.
The source code is available in the [spring-ai-structured-output-demo](https://github.com/tzolov/spring-ai-structured-output-demo) repository.
## Bean Output Converter
Following example shows how to use `BeanOutputConverter` to generate the filmography for an actor.
The target record representing actor's filmography:
record ActorsFilms(String actor, List`` movies) \{
}
Here is how to leverage the BeanOutputConverter using the new, fluent ChatClient API:
ActorsFilms actorsFilms = ChatClient.create(chatModel).prompt()
.user(u -> u.text("Generate the filmography of 5 movies for \{actor}.")
.param("actor", "Tom Hanks"))
.call()
.entity(ActorsFilms.class);
or using the low-level, ChatModel API directly:
String userInputTemplate = """
Generate the filmography of 5 movies for \{actor}.
\{format}
""";
BeanOutputConverter`` beanOutputConverter = new BeanOutputConverter`<>`(ActorsFilms.class);
String format = beanOutputConverter.getFormat();
String actor = "Tom Hanks";
Prompt prompt = new Prompt(
new PromptTemplate(userInputTemplate, Map.of("actor", actor, "format", format)).createMessage());
Generation generation = chatClient.call(prompt).getResult();
ActorsFilms actorsFilms = beanOutputConverter.convert(generation.getOutput().getContent());
#### Support Generic Bean Types
Use the `ParameterizedTypeReference` constructor to specify a more complex target class structure. For example, to represent a list of actors and their filmographies:
List`` actorsFilms = ChatClient.create(chatModel).prompt()
.user("Generate the filmography of 5 movies for Tom Hanks and Bill Murray.")
.call()
.entity(new ParameterizedTypeReference``>() \{
});
or using the low-level, ChatModel API directly:
BeanOutputConverter``> outputConverter = new BeanOutputConverter`<>`(
new ParameterizedTypeReference``>() \{ });
String format = outputConverter.getFormat();
String template = """
Generate the filmography of 5 movies for Tom Hanks and Bill Murray.
\{format}
""";
Prompt prompt = new Prompt(new PromptTemplate(template, Map.of("format", format)).createMessage());
Generation generation = chatClient.call(prompt).getResult();
List`` actorsFilms = outputConverter.convert(generation.getOutput().getContent());
## Map Output Converter
Following sniped shows how to use `MapOutputConverter` to generate a list of numbers.
Map`` result = ChatClient.create(chatModel).prompt()
.user(u -> u.text("Provide me a List of \{subject}")
.param("subject", "an array of numbers from 1 to 9 under they key name 'numbers'"))
.call()
.entity(new ParameterizedTypeReference``>() \{
});
or using the low-level, ChatModel API directly:
MapOutputConverter mapOutputConverter = new MapOutputConverter();
String format = mapOutputConverter.getFormat();
String userInputTemplate = """
Provide me a List of \{subject}
\{format}
""";
PromptTemplate promptTemplate = new PromptTemplate(userInputTemplate,
Map.of("subject", "an array of numbers from 1 to 9 under they key name 'numbers'", "format", format));
Prompt prompt = new Prompt(promptTemplate.createMessage());
Generation generation = chatClient.call(prompt).getResult();
Map`` result = mapOutputConverter.convert(generation.getOutput().getContent());
## List Output Converter
Following snippet shows how to use `ListOutputConverter` to generate a list of ice cream flavours.
List`` flavors = ChatClient.create(chatModel).prompt()
.user(u -> u.text("List five \{subject}")
.param("subject", "ice cream flavors"))
.call()
.entity(new ListOutputConverter(new DefaultConversionService()));
or using the low-level, ChatModel API directly:
ListOutputConverter listOutputConverter = new ListOutputConverter(new DefaultConversionService());
String format = listOutputConverter.getFormat();
String userInputTemplate = """
List five \{subject}
\{format}
""";
PromptTemplate promptTemplate = new PromptTemplate(userInputTemplate,\
Map.of("subject", "ice cream flavors", "format", format));
Prompt prompt = new Prompt(promptTemplate.createMessage());
Generation generation = this.chatClient.call(prompt).getResult();
List`` list = listOutputConverter.convert(generation.getOutput().getContent());
# 3. References
* For further information please consult the Spring AI [Structured Output Converter](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/structured-output-converter.html) documentation.
* For code examples check the [spring-ai-structured-output-demo](https://github.com/tzolov/spring-ai-structured-output-demo) GitHub repository.
* [AI Models](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/structured-output-converter.html#_supported_ai_models) supported by the Structured Output API.
* [Models](https://docs.spring.io/spring-ai/reference/1.0-SNAPSHOT/api/structured-output-converter.html#_build_in_json_mode) with build-in JSON mode support.
# 4. Conclusions
The ability of LLMs to produce structured outputs enables the developers for seamless integration with downstream applications. The `Structured Output Converters` facilitate this process, ensuring reliable parsing of model outputs into structured formats like JSON or Java Classes.
This post provides practical usage examples of converters like `BeanOutputConverter`, `MapOutputConverter`, and `ListOutputConverter`, showcasing the generation structured outputs for diverse data types.
In summary, Spring AI's Structured Output Converters offer a robust solution for developers seeking to harness the power of LLMs while ensuring compatibility and reliability in their applications through structured output formats.
# Explainable AI Agents: Capture LLM Tool Call Reasoning with Spring AI
Source: https://springaicommunity.mintlify.app/blog/tools/tool-argument-augmenter
When building AI agents with tool calling capabilities, developers often need insights into **why** an LLM chose a particular tool—not just which tool it...
![]() When building AI agents with tool calling capabilities, developers often need insights into **why** an LLM chose a particular tool—not just which tool it selected. Understanding the model's reasoning process is important for debugging, observability, and building trustworthy AI systems.
Spring AI now (2.0.0-SNAPSHOT/1.1.3-SNAPSHOT) includes the [Tool Argument Augmenter](https://docs.spring.io/spring-ai/reference/2.0-SNAPSHOT/api/tools.html#tool-argument-augmentation) feature that enables **dynamic augmentation of tool input schemas** with additional arguments before sending tool definitions to the LLM. This allows AI applications to capture extra information from the model—such as reasoning, inner thoughts, confidence levels, or metadata—that can be used by the application itself without affecting the underlying tool implementation.
This technique is useful for:
* **Memory Enhancement**: Capture the LLM's internal reasoning and insights to store in long-term memory—these "inner thoughts" become valuable context that improves the model's reasoning capabilities across extended conversations
* **Observability & Debugging**: Capture the LLM's step-by-step reasoning before each tool execution
> **💡 Quick Start and Demo**: For a quick start, jump directly to the [Quick Start](#quick-start) section below. For a complete working example, check out the [tool-argument-augmenter-demo](https://github.com/spring-projects/spring-ai-examples/tree/main/advisors/tool-argument-augmenter-demo) demo project and reference documentation: [Tool Argument Augmentation](https://docs.spring.io/spring-ai/reference/2.0-SNAPSHOT/api/tools.html#tool-argument-augmentation).
#### Tool Calling
The [Tool calling](https://docs.spring.io/spring-ai/reference/api/tools.html) (also known as function calling) allows LLMs to request the execution of external functions or APIs when they need to perform actions or retrieve information beyond their training data.
The Spring AI Tool Calling flow when using the `ToolCallAdvisor` is:
![]() 1. User asks a question
2. Spring AI's Tool Call Advisor sends available tool definitions with their original schemas to the LLM
3. LLM analyzes the request, decides which tool to call, and returns a tool call request with required arguments
4. Tool Management dispatches and invokes the actual tool
5. Result is sent back to the LLM
6. LLM generates the final response incorporating the tool's result
#### The Problem
Tools are defined with fixed input parameters, but AI applications often need **additional context or metadata** from the LLM—such as reasoning or insights—alongside standard tool inputs. These extra fields are needed by the application layer, not the tool itself. Modifying every tool to accept them would violate separation of concerns, create tight coupling, and require changes across many existing tools or even be impossible for external (MCP) tools.
#### The Tool Argument Augmenter Solution
The Tool Argument Augmenter solves this elegantly by:
1. **Dynamically extending** the tool's JSON Schema with additional fields (defined as Java Records)
2. **Intercepting tool calls** to extract and process the augmented arguments
3. **Optionally removing** the augmented arguments before passing input to the original tool
This creates a transparent layer where the LLM sees an augmented schema and provides the extra information used by the AI application, while the underlying tool remains unchanged.
The complete flow works as follows:
![]() 1. **User Request:** User asks "What to wear in Amsterdam today?"
2. **Tool Definition:** Tool Call Advisor adds the tool definitions with their original schemas to the request
3. **Tool Definition Interception:** Before being sent to the LLM, the Tool Argument Augmenter intercepts the tool definition and augments its schema with additional (provided) arguments (e.g., `innerThoughts: String`, `memoryNotes: List`)
4. **LLM Response:** The LLM sees this enriched schema and provides both the original tool arguments (`location: "Amsterdam"`) AND the augmented arguments (`innerThoughts: "I need to check the weather to suggest appropriate clothing..."`)
5. **Argument Processing**: When the tool call request returns, the augmenter extracts the augmented arguments and passes them to a **Consumer** for processing (logging, memory storage, analytics, etc.)
6. **Tool Execution**: The original tool receives only its expected arguments—completely unaware of the augmentation
> **MCP Compatible:** This technique works seamlessly with both local tools (e.g., `@Tool`) and MCP tools (e.g., `@McpTool`).
## Quick Start
#### Requirements
* **Java 17** or higher
* **Spring AI 2.0.0-SNAPSHOT+** or **Spring AI 1.1.3-SNAPSHOT+**
The Tool Argument Augmenter is included in Spring AI's core module (`spring-ai-model`), so no additional dependencies are required beyond the standard Spring AI dependency.
#### 1. Define Augmented Arguments
The most powerful use case is adding an "inner thinking" field that captures the LLM's reasoning. Define your augmented arguments as a Java Record with `@ToolParam` annotations:
```java theme={null}
import org.springframework.ai.tool.annotation.ToolParam;
public record AgentThinking(
@ToolParam(description = "Your step-by-step reasoning for why you're calling this tool and what you expect", required = true)
String innerThought,
@ToolParam(description = "Confidence level (low, medium, high) in this tool choice", required = false)
String confidence,
@ToolParam(description = "Key insights to remember for future interactions", required = true)
List memoryNotes
) {}
```
#### 2. Wrap Your Existing Tools
Use the `AugmentedToolCallbackProvider` builder to wrap your existing tools:
```java theme={null}
import org.springframework.ai.tool.augment.AugmentedToolCallbackProvider;
// Your existing tool defined using Spring AI @Tool annotation
public class WeatherTool {
@Tool(description = "Get the current weather for a given location")
public String weather(String location) {
return "The current weather in " + location + " is sunny with a temperature of 25°C.";
}
}
// Wrap with augmented arguments
AugmentedToolCallbackProvider provider =
AugmentedToolCallbackProvider.builder()
.toolObject(new WeatherTool())
.argumentType(AgentThinking.class)
.argumentConsumer(event -> {
// Access the augmented arguments via event.arguments()
AgentThinking thinking = event.arguments();
// Log the LLM's reasoning - great for debugging and observability
log.info("Tool: {}, LLM Reasoning: {}, Confidence: {}",
event.toolDefinition().name(), thinking.innerThought(), thinking.confidence());
// Store insights in memory for future context
thinking.memoryNotes().forEach(note ->
memorySystem.store(note)
);
})
.build();
// Use with Spring AI ChatClient
ChatClient chatClient = ChatClient.builder(chatModel)
.defaultToolCallbacks(provider)
.build();
```
#### 3. Wrap Your Existing ToolCallbackProviders
You can wrap existing providers (including `MCP` tool providers) instead of individual tool objects:
```java theme={null}
AugmentedToolCallbackProvider provider =
AugmentedToolCallbackProvider.builder()
.delegate(existingProvider) // Wrap an existing provider
.argumentType(AgentThinking.class)
.argumentConsumer(event -> processThinking(event.arguments()))
.build();
// Use with Spring AI ChatClient
ChatClient chatClient = ChatClient.builder(chatModel)
.defaultToolCallbacks(provider)
.build();
```
#### 4. What the LLM Sees
When the LLM receives the tool definition, it sees the **augmented schema** with your additional fields:
```json theme={null}
{
"type": "object",
"properties": {
"location": {
"type": "string",
"description": "The location to get weather for"
},
"innerThought": {
"type": "string",
"description": "Your step-by-step reasoning for why you're calling this tool and what you expect"
},
"confidence": {
"type": "string",
"description": "Confidence level (low, medium, high) in this tool choice"
},
"memoryNotes": {
"type": "array",
"items": { "type": "string" },
"description": "Key insights to remember for future interactions"
}
},
"required": ["location", "innerThought", "memoryNotes"]
}
```
#### 5. LLM Response with Reasoning
The LLM will now provide its reasoning along with the tool call:
```json theme={null}
{
"location": "Amsterdam",
"innerThought": "The user is asking about what to wear in Amsterdam today. I need to check the current weather conditions to provide appropriate clothing recommendations.",
"confidence": "high",
"memoryNotes": [
"User is planning an outing in Amsterdam",
"May need follow-up with specific activity questions"
]
}
```
Your consumer receives the `AgentThinking` record with all the reasoning, while the original tool receives only `{"location": "Amsterdam"}`.
#### 6. Include Reasoning in Final Response (Optional)
You can also include the LLM's reasoning in the final response using Spring AI's [Structured Output](https://docs.spring.io/spring-ai/reference/api/structured-output-converter.html). This is useful when you want to expose the model's thinking to users or downstream systems—not just capture it during tool calls.
```java theme={null}
public record ResponseWithReasoning(
String response,
AgentThinking thinking
) {}
var answer = chatClient
.prompt("What should I wear in Amsterdam today?")
.call()
.entity(ResponseWithReasoning.class); // structured response
// Access both the response and the reasoning
System.out.println("Answer: " + answer.response());
System.out.println("Reasoning: " + answer.thinking().innerThought());
```
## Advanced Use Cases
You can leverage this technique for various AI agent patterns.
The following examples demonstrate how to build memory-enhanced agents, capture chain-of-thought reasoning, collect analytics, and coordinate multi-agent systems.
### AI Agent Memory Systems
Combine Tool Argument Augmenter with Spring AI's advisor chain to build intelligent agents with memory. The captured inner thoughts become valuable context that improves reasoning across conversations:
```java theme={null}
import org.springframework.ai.tool.augment.AugmentedToolCallbackProvider;
AugmentedToolCallbackProvider provider = AugmentedToolCallbackProvider
.builder()
.toolObject(new MyTools())
.argumentType(AgentThinking.class)
.build();
MessageWindowChatMemory chatMemory = MessageWindowChatMemory.builder()
.maxMessages(100)
.build();
ChatClient chatClient = chatClientBuilder
.defaultToolCallbacks(provider)
.defaultAdvisors(
ToolCallAdvisor.builder()
.advisorOrder(BaseAdvisor.HIGHEST_PRECEDENCE + 300)
.conversationHistoryEnabled(false).build(),
MessageChatMemoryAdvisor.builder(chatMemory)
.order(Ordered.HIGHEST_PRECEDENCE + 1000).build())
.build();
var answer = chatClient
.prompt("What is current weather in Paris?")
.call()
.entity(MyResponse.class);
```
This provides **tool-level reasoning capture**, **conversation continuity** via memory advisor, and **full observability** into LLM decision-making.
> **Note:** Disable `ToolCallAdvisor`'s conversation history and ensure `MessageChatMemoryAdvisor` runs after it in the advisor chain.
### Chain of Thought Reasoning
Capture detailed step-by-step reasoning for complex tasks:
```java theme={null}
public record ChainOfThought(
@ToolParam(description = "Break down your reasoning into numbered steps", required = true)
List reasoningSteps,
@ToolParam(description = "What alternative approaches did you consider?", required = false)
List alternatives,
@ToolParam(description = "Final conclusion that led to this tool choice", required = true)
String conclusion
) {}
// Process the reasoning chain
Consumer> cotProcessor = event -> {
ChainOfThought cot = event.arguments();
log.info("=== Chain of Thought for {} ===", event.toolDefinition().name());
for (int i = 0; i < cot.reasoningSteps().size(); i++) {
log.info("Step {}: {}", i + 1, cot.reasoningSteps().get(i));
}
log.info("Conclusion: {}", cot.conclusion());
// Store for analysis or fine-tuning data collection
reasoningStore.save(cot);
};
```
### Tool Usage Analytics
Track and analyze tool usage patterns for optimization and insights:
```java theme={null}
public record ToolAnalytics(
@ToolParam(description = "Why did you choose this specific tool?", required = true)
String toolSelectionReason,
@ToolParam(description = "What result do you expect from this tool?", required = false)
String expectedOutcome,
@ToolParam(description = "User intent classification", required = true)
String userIntent
) {}
Consumer> analyticsProcessor = event -> {
ToolAnalytics analytics = event.arguments();
String toolName = event.toolDefinition().name();
metricsCollector.recordToolSelection(
toolName,
analytics.userIntent(),
analytics.toolSelectionReason()
);
if (analytics.expectedOutcome() != null) {
// Compare expected vs actual outcomes for quality metrics
outcomeTracker.recordExpectation(toolName, analytics.expectedOutcome());
}
};
```
### Multi-Agent Coordination
Enable communication and coordination between multiple AI agents:
```java theme={null}
public record AgentCoordination(
@ToolParam(description = "Your agent ID", required = true)
String agentId,
@ToolParam(description = "Agents that should be notified of this action", required = false)
List notifyAgents,
@ToolParam(description = "Shared context for other agents", required = false)
String sharedContext,
@ToolParam(description = "Priority level for coordination (low, normal, high, critical)", required = false)
String priority
) {}
Consumer> coordinationProcessor = event -> {
AgentCoordination coord = event.arguments();
String toolName = event.toolDefinition().name();
if (coord.notifyAgents() != null && !coord.notifyAgents().isEmpty()) {
Message notification = Message.builder()
.from(coord.agentId())
.toolAction(toolName)
.content(coord.sharedContext())
.priority(coord.priority() != null ? coord.priority() : "normal")
.build();
coord.notifyAgents().forEach(targetAgent ->
messageBus.send(targetAgent, notification)
);
}
};
```
## Best Practices
* **Keep augmented arguments focused**: Define only the fields you actually need to capture. Too many additional fields can increase token consumption and confuse the model.
* **Use descriptive field descriptions**: The `@ToolParam` description is what the LLM sees. Clear, specific descriptions lead to better quality responses.
* **Consider required vs optional**: Mark fields as `required = true` only when you absolutely need them. Optional fields give the LLM flexibility.
* **Monitor token usage**: Augmented schemas increase prompt size. Monitor token consumption, especially with many tools.
## Conclusion
The Tool Argument Augmenter provides a powerful, non-invasive way to capture LLM reasoning and metadata during tool execution. By dynamically extending tool schemas, you gain visibility into **why** an LLM makes decisions—not just what decisions it makes.
This feature integrates seamlessly with Spring AI's existing tool calling infrastructure, working with both local `@Tool` methods and MCP tools without requiring any changes to the underlying implementations.
> **🚀 Try It Yourself**: The complete runnable demo is available in the [recursive-advisor-with-memory](https://github.com/spring-projects/spring-ai-examples/tree/main/advisors/recursive-advisor-with-memory) example project.
## Related Blog Posts
* [Create Self-Improving AI Agents Using Spring AI Recursive Advisors](https://spring.io/blog/2025/11/04/spring-ai-recursive-advisors) - Learn how to build self-improving AI agents using recursive advisor patterns
* [LLM-as-a-Judge Evaluation with Spring AI](https://spring.io/blog/2025/11/10/spring-ai-llm-as-judge-blog-post) - Use LLMs to evaluate and assess AI response quality
* [Tool Response Formats in Spring AI](https://spring.io/blog/2025/11/25/spring-ai-tool-response-formats) - Control and customize how tool results are formatted and returned to the LLM
* [Semantic Tool Search in Spring AI](https://spring.io/blog/2025/12/11/spring-ai-tool-search-tools-tzolov) - Dynamically discover and select the right tools using semantic search
## Resources
* [**Tool Argument Augmentation**](https://docs.spring.io/spring-ai/reference/2.0-SNAPSHOT/api/tools.html#tool-argument-augmentation)
* **Example Project**: [tool-argument-augmenter-demo](https://github.com/spring-projects/spring-ai-examples/tree/main/advisors/tool-argument-augmenter-demo)
* **Spring AI Tool Calling**: [Tools API Documentation](https://docs.spring.io/spring-ai/reference/api/tools.html)
* **Spring AI Chat Client**: [ChatClient Documentation](https://docs.spring.io/spring-ai/reference/api/chatclient.html)
* **Spring AI Advisors**: [Advisors API Guide](https://docs.spring.io/spring-ai/reference/api/advisors.html)
# Beyond JSON: Converting Spring AI Tool Response Formats to TOON, XML, CSV, YAML, ...
Source: https://springaicommunity.mintlify.app/blog/tools/tool-response-formats
JSON is the go-to format for LLM tool responses, but recent discussions around alternative formats like [TOON](https://github.com/toon-format/toon)...
![]() JSON is the go-to format for LLM tool responses, but recent discussions around alternative formats like [TOON](https://github.com/toon-format/toon) (Token-Oriented Object Notation) claim potential benefits in token efficiency and performance.
While the debate continues—with [critical analyses](https://www.improvingagents.com/blog/toon-benchmarks) pointing to [context-dependent results](https://www.towardsdeeplearning.com/toon-benchmarks-a-critical-analysis-of-different-results-d2a74563adca)—the question is: how to experiment with these formats in your own Spring AI applications?
This article demonstrates **how** to configure Spring AI to convert tool responses between `JSON`, `TOON`, `XML`, `CSV`, and `YAML`, enabling you to decide what works best for your specific use case.
## Spring AI Tool Calling: A Quick Overview
Let's briefly review how [Spring AI Tool Calling](https://docs.spring.io/spring-ai/reference/api/tools.html#_overview) works:
![]() 1. Tool definitions (name, description, parameters schema) are added to the chat request.
2. When the model decides to call a tool, it sends the tool name and input parameters.
3. Spring AI identifies and executes the tool with the provided parameters.
4. Spring AI handles the tool result.
5. Spring AI sends the tool result back to the model as part of the conversation history.
6. The model generates the final response using the tool result as additional context.
The [ToolCallback](https://github.com/spring-projects/spring-ai/blob/main/spring-ai-model/src/main/java/org/springframework/ai/tool/ToolCallback.java) interface is at the heart of this process. Each tool is wrapped in a `ToolCallback` that handles the serialization and execution logic.
We can intercept and convert the response format at two key points:
* **Tool Result level**: After the tool executes but before JSON serialization (Approach 1)
* **Response level**: After JSON serialization, transforming JSON to another format (Approach 2)
Both approaches have their merits, and the choice depends on your specific requirements. Let's explore each in detail.
## Approach 1: Custom ToolCallResultConverter Configuration
> **Important**: Applicable only for local tool implementations such as `@Tool`, `FunctionToolCallback` and `MethodToolCallback`. Currently it is not supported by the MCP Tools.
The [ToolCallResultConverter](https://docs.spring.io/spring-ai/reference/api/tools.html#_result_conversion) interface provides fine-grained control over individual tool formats.
The DefaultToolCallResultConverter serializes the result to JSON, but you can customize the serialization process by providing your own ToolCallResultConverter implementation.
For example, a custom ToonToolCallResultConverter can look like this:
```java theme={null}
public static class ToonToolCallResultConverter implements ToolCallResultConverter {
private ToolCallResultConverter delegate = new DefaultToolCallResultConverter();
@Override
public String convert(@Nullable Object result, @Nullable Type returnType) {
// First convert to JSON using the default converter
String json = this.delegate.convert(result, returnType);
// Then convert JSON to TOON
return JToon.encodeJson(json);
}
}
```
It uses the default JSON converter, then converts to TOON using libraries such as [JToon](https://github.com/toon-format/toon-java) or [toon4j](https://github.com/ricken07/toon4j).
**Register with @Tool:**
```java theme={null}
@Tool(description = "Get random titanic passengers",
resultConverter = ToonToolCallResultConverter.class) // (1)
public List randomTitanicToon(
@ToolParam(description = "Number of records to return") int count) {
return TitanicData.getRandomTitanicPassengers(count);
}
```
Uses the `resultConverter` attribute to set the custom ToonToolCallResultConverter.
**Execution flow:** Tool executes → Default converter creates JSON → TOON converter transforms JSON → LLM receives TOON response.
You can also register the ToolCallResultConverter with the [FunctionToolCallback](https://docs.spring.io/spring-ai/reference/api/tools.html#_programmatic_specification_functiontoolcallback) and [MethodToolCallback](https://docs.spring.io/spring-ai/reference/api/tools.html#_programmatic_specification_methodtoolcallback) builders programmatically.
**Limitations:**
* ❌ **MCP incompatible**: Doesn't work with `@McpTool` (Model Context Protocol tools)
* ❌ **Repetitive**: Must implement and register for each tool needing conversion
* ❌ **Maintenance overhead**: Changes require updating multiple tool definitions
The [Application2.java](https://github.com/tzolov/spring-ai-tool-response-format-demo/blob/main/src/main/java/com/example/trfd/Application2.java) provides an implementation example.
## Approach 2: Global Tool Response Configuration
Apply format conversion globally using a custom `ToolCallbackProvider` that wraps existing providers with delegator pattern:
```
Original ToolCallbackProvider
↓ wrapped by
DelegatorToolCallbackProvider
↓ creates wrapped callbacks
DelegatorToolCallback (for each tool)
↓ intercepts call() method
↓ converts response
JSON → Target Format (TOON/XML/CSV/YAML)
```
#### Component 1: [DelegatorToolCallbackProvider](https://github.com/tzolov/spring-ai-tool-response-format-demo/blob/main/src/main/java/com/example/trfd/DelegatorToolCallbackProvider.java)
```java theme={null}
public class DelegatorToolCallbackProvider implements ToolCallbackProvider {
private final ToolCallbackProvider delegate;
private final ResponseConverter.Format format;
public DelegatorToolCallbackProvider(ToolCallbackProvider delegate,
ResponseConverter.Format format) {
this.delegate = delegate;
this.format = format;
}
@Override
public ToolCallback[] getToolCallbacks() {
return Stream.of(this.delegate.getToolCallbacks())
.map(callback -> new DelegatorToolCallback(callback, this.format))
.toArray(ToolCallback[]::new);
}
}
```
This provider wraps an existing `ToolCallbackProvider` and creates a `DelegatorToolCallback` wrapper for each tool callback. The format parameter specifies which format to convert to.
#### Component 2: [DelegatorToolCallback](https://github.com/tzolov/spring-ai-tool-response-format-demo/blob/370bb149c4fcfa83c4f9d117879bbdf18c0d2e71/src/main/java/com/example/trfd/DelegatorToolCallbackProvider.java#L47)
```java theme={null}
public static class DelegatorToolCallback implements ToolCallback {
private final ToolCallback delegate;
private final ResponseConverter.Format format;
public DelegatorToolCallback(ToolCallback delegate,
ResponseConverter.Format format) {
this.delegate = delegate;
this.format = format;
}
@Override
public ToolDefinition getToolDefinition() {
return this.delegate.getToolDefinition();
}
@Override
public String call(String toolInput) {
// Call the original tool to get JSON response
String jsonResponse = this.delegate.call(toolInput);
// Convert to target format
return ResponseConverter.convert(jsonResponse, this.format);
}
}
```
The callback wrapper intercepts the `call()` method, allowing the original tool to execute normally, then converts its JSON response to the desired format.
#### Component 3: [ResponseConverter](https://github.com/tzolov/spring-ai-tool-response-format-demo/blob/main/src/main/java/com/example/trfd/ResponseConverter.java) Utility
```java theme={null}
public class ResponseConverter {
public enum Format {
TOON, YAML, XML, CSV, JSON
}
public static String convert(String json, Format format) {
switch (format) {
case TOON: return jsonToToon(json);
case YAML: return jsonToYaml(toJsonNode(json));
case XML: return jsonToXml(toJsonNode(json));
case CSV: return jsonToCsv(toJsonNode(json));
case JSON: return json;
}
throw new IllegalStateException("Unsupported format: " + format);
}
private static String jsonToToon(String jsonString) {...}
private static String jsonToYaml(JsonNode jsonNode) {...}
private static String jsonToXml(JsonNode jsonNode) {...}
private static String jsonToCsv(JsonNode jsonNode) {...}
}
```
The [ResponseConverter](https://github.com/tzolov/spring-ai-tool-response-format-demo/blob/main/src/main/java/com/example/trfd/ResponseConverter.java) provides conversion methods for each supported format, handling the specific requirements of each (like wrapping arrays for XML or building dynamic schemas for CSV).
**Usage example:**
```java theme={null}
@SpringBootApplication
public class Application {
public static void main(String[] args) {
SpringApplication.run(Application.class, args);
}
@Bean
CommandLineRunner commandLineRunner(ChatClient.Builder chatClientBuilder,
ToolCallbackProvider toolCallbackProvider) {
// Wrap the provider with format conversion
var provider = new DelegatorToolCallbackProvider(
toolCallbackProvider,
ResponseConverter.Format.TOON
);
// Configure ChatClient with the wrapped provider
var chatClient = chatClientBuilder
.defaultToolCallbacks(provider)
.build();
return args -> {
var response = chatClient
.prompt("Please show me 10 Titanic passengers?")
.call()
.chatResponse();
System.out.println(String.format("""
RESPONSE: %s
USAGE: %s
""",
response.getResult().getOutput().getText(),
response.getMetadata().getUsage()));
};
}
@Bean
MethodToolCallbackProvider methodToolCallbackProvider() {
return MethodToolCallbackProvider.builder()
.toolObjects(new MyTools())
.build();
}
static class MyTools {
@Tool(description = "Get titanic passengers")
public List randomTitanicToon(
@ToolParam(description = "Number of records to return") int count) {
return TitanicData.getTitanicPassengersInRange(30, count);
}
}
}
```
**Execution flow:** User prompt → LLM calls tool → Wrapper intercepts → Tool executes → JSON created → Format converter transforms → LLM receives converted response.
The [Application](https://github.com/tzolov/spring-ai-tool-response-format-demo/blob/main/src/main/java/com/example/trfd/Application.java) example leverages the [ToolCallAdvisor](https://docs.spring.io/spring-ai/reference/api/advisors-recursive.html#_toolcalladvisor) (e.g. moving the tool execution as part of the Advisor chain) and a custom logging advisor `MyLogAdvisor` that helps to see the actual tool responses in different formats.
This advisor will print out the tool responses, allowing you to see the target format output.
### Format Conversion Details
Let's examine each supported format and see what the output looks like.
#### JSON (default)
```json theme={null}
[{"PassengerId":"31","Survived":"0","Pclass":"1","Name":"Uruchurtu, Don. Manuel E","Sex":"male","Age":40,"SibSp":"0","Parch":"0","Ticket":"PC 17601","Fare":27.7208,"Cabin":null,"Embarked":"C"},
{"PassengerId":"32","Survived":"1","Pclass":"1","Name":"Spencer, Mrs. William Augustus (Marie Eugenie)","Sex":"female","Age":null,"SibSp":"1","Parch":"0","Ticket":"PC 17569","Fare":146.5208,"Cabin":"B78","Embarked":"C"},
{"PassengerId":"33","Survived":"1","Pclass":"3","Name":"Glynn, Miss. Mary Agatha","Sex":"female","Age":null,"SibSp":"0","Parch":"0","Ticket":"335677","Fare":7.75,"Cabin":null,"Embarked":"Q"},
{"PassengerId":"34","Survived":"0","Pclass":"2","Name":"Wheadon, Mr. Edward H","Sex":"male","Age":66,"SibSp":"0","Parch":"0","Ticket":"C.A. 24579","Fare":10.5,"Cabin":null,"Embarked":"S"},
{"PassengerId":"35","Survived":"0","Pclass":"1","Name":"Meyer, Mr. Edgar Joseph","Sex":"male","Age":28,"SibSp":"1","Parch":"0","Ticket":"PC 17604","Fare":82.1708,"Cabin":null,"Embarked":"C"}]
```
#### TOON
```toon theme={null}
[5]{PassengerId,Survived,Pclass,Name,Sex,Age,SibSp,Parch,Ticket,Fare,Cabin,Embarked}:
"31","0","1","Uruchurtu, Don. Manuel E",male,40,"0","0",PC 17601,27.7208,null,C
"32","1","1","Spencer, Mrs. William Augustus (Marie Eugenie)",female,null,"1","0",PC 17569,146.5208,B78,C
"33","1","3","Glynn, Miss. Mary Agatha",female,null,"0","0","335677",7.75,null,Q
"34","0","2","Wheadon, Mr. Edward H",male,66,"0","0",C.A. 24579,10.5,null,S
"35","0","1","Meyer, Mr. Edgar Joseph",male,28,"1","0",PC 17604,82.1708,null,C
```
#### XML
```xml theme={null}
3101Uruchurtu, Don. Manuel Emale4000PC 1760127.7208C
3211Spencer, Mrs. William Augustus (Marie Eugenie)female10PC 17569146.5208B78C
3313Glynn, Miss. Mary Agathafemale003356777.75Q
3402Wheadon, Mr. Edward Hmale6600C.A. 2457910.5S
3501Meyer, Mr. Edgar Josephmale2810PC 1760482.1708C
```
#### YAML
```yaml theme={null}
---
- PassengerId: "31"
Survived: "0"
Pclass: "1"
Name: "Uruchurtu, Don. Manuel E"
Sex: "male"
Age: 40
SibSp: "0"
Parch: "0"
Ticket: "PC 17601"
Fare: 27.7208
Cabin: null
Embarked: "C"
...
- PassengerId: "35"
Survived: "0"
Pclass: "1"
Name: "Meyer, Mr. Edgar Joseph"
Sex: "male"
Age: 28
SibSp: "1"
Parch: "0"
Ticket: "PC 17604"
Fare: 82.1708
Cabin: null
Embarked: "C"
```
#### CSV
```csv theme={null}
PassengerId,Survived,Pclass,Name,Sex,Age,SibSp,Parch,Ticket,Fare,Cabin,Embarked
31,0,1,"Uruchurtu, Don. Manuel E",male,40,0,0,"PC 17601",27.7208,,C
32,1,1,"Spencer, Mrs. William Augustus (Marie Eugenie)",female,,1,0,"PC 17569",146.5208,B78,C
33,1,3,"Glynn, Miss. Mary Agatha",female,,0,0,335677,7.75,,Q
34,0,2,"Wheadon, Mr. Edward H",male,66,0,0,"C.A. 24579",10.5,,S
35,0,1,"Meyer, Mr. Edgar Joseph",male,28,1,0,"PC 17604",82.1708,,C
```
![]() The **[Tool Search Tool](https://www.anthropic.com/engineering/advanced-tool-use)** pattern, pioneered by Anthropic, addresses this: instead of loading all tool definitions upfront, the model discovers tools on-demand. It receives only a search tool initially, queries for capabilities when needed, and gets relevant tool definitions expanded into context. This achieves **significant token savings** while maintaining access to hundreds of tools.
**The key insight:** While Anthropic introduced this pattern for Claude, we can implement the same approach for **any LLM** using Spring AI's **[Recursive Advisors](https://docs.spring.io/spring-ai/reference/api/advisors-recursive.html)**.
Spring AI provides a portable abstraction that makes dynamic tool discovery work across OpenAI, Anthropic, Gemini, Ollama, Azure OpenAI, and any other LLM provider supported by Spring AI.
**Our preliminary benchmarks show Spring AI's Tool Search Tool implementation achieves 34-64% token reduction** across OpenAI, Anthropic, and Gemini models while maintaining full access to hundreds of tools.
> The Spring AI Tool Search Tool project is available on: [spring-ai-tool-search-tool](https://github.com/spring-ai-community/spring-ai-tool-search-tool).
## How Tool Calling Works
First, let's understand how Spring AI's [tool calling](https://docs.spring.io/spring-ai/reference/api/tools.html) works when using the [ToolCallAdvisor](https://docs.spring.io/spring-ai/reference/api/advisors-recursive.html#_toolcalladvisor) - a special recursive advisor that:
![]() 1. **Intercepts the ChatClient request** before it reaches the LLM
2. **Includes tool definitions** in the prompt sent to the model - for all registered tools!
3. **Detects tool call requests** in the model's response
4. **Executes the requested tools** using the `ToolCallingManager`
5. **Loops back** with tool results until the model provides a final answer
The tool execution happens in a **recursive loop** - the advisor keeps calling the LLM until no more tool calls are requested.
## The Problem
The standard tool calling flow (such as `ToolCallAdvisor`) sends **all tool definitions** to the LLM upfront. This creates three major issues with large tool collections:
* **Context bloat** - Massive token consumption before any conversation begins
* **Tool confusion** - Models struggle to choose correctly when facing 30+ similar tools
* **Higher costs** - Paying for unused tool definitions in every request
## The Tool Search Tool Solution
By extending Spring AI's `ToolCallAdvisor`, we've created a `ToolSearchToolCallAdvisor` that implements dynamic tool discovery. It intercepts the tool calling loop to selectively inject tools based on what the model discovers it needs:
![]() The flow works as follows:
1. **Indexing**: At conversation start, all registered tools are indexed in the `ToolSearcher` (but NOT sent to the LLM)
2. **Initial Request**: Only the **Tool Search Tool (TST)** definition is sent to the LLM - saving context
3. **Discovery Call**: When the LLM needs capabilities, it calls the TST with a search query
4. **Search & Expand**: The `ToolSearcher` finds matching tools (e.g., "Tool XYZ") and their definitions are added to the next request
5. **Tool Invocation**: The LLM now sees both TST and the discovered tool definitions, and can call the actual tool
6. **Tool Execution**: The discovered tool is executed and results returned to the LLM
7. **Response**: The LLM generates the final answer using the tool results
In code, this looks like this:
```java theme={null}
var toolSearchToolCallAdvisor = ToolSearchToolCallAdvisor.builder()
.toolSearcher(toolSearcher)
.maxResults(5)
.build();
ChatClient chatClient = chatClientBuilder
.defaultTools(new MyTools()) // 100s of tools registered but NOT sent to LLM initially
.defaultAdvisors(toolSearchToolCallAdvisor) // Activate Tool Search Tool
.build();
```
### Pluggable Search Strategies
The `ToolSearcher` interface abstracts the search implementation, supporting multiple strategies (see [tool-searchers](https://github.com/spring-ai-community/spring-ai-tool-search-tool/tree/main/tool-searchers) for implementations):
| Strategy | Implementation | Best For |
| ------------ | -------------------- | ---------------------------------------- |
| **Semantic** | `VectorToolSearcher` | Natural language queries, fuzzy matching |
| **Keyword** | `LuceneToolSearcher` | Exact term matching, known tool names |
| **Regex** | `RegexToolSearcher` | Tool name patterns (`get_*_data`) |
## Getting Started
The project's GitHub repository is: [spring-ai-tool-search-tool](https://github.com/spring-ai-community/spring-ai-tool-search-tool).
For detailed setup instructions and code examples, see the [Quick Start guide (v1.x)](https://github.com/spring-ai-community/spring-ai-tool-search-tool/tree/1.0.x?tab=readme-ov-file#quick-start) and the related [example application (v1.x)](https://github.com/spring-ai-community/spring-ai-tool-search-tool/tree/1.0.x/examples/tool-search-tool-demo).
**Maven Central (1.0.1):**
```xml theme={null}
org.springaicommunity
tool-search-tool
1.0.1
org.springaicommunity
tool-searcher-lucene
1.0.1
```
*Version [v1.0.x](https://github.com/spring-ai-community/spring-ai-tool-search-tool/tree/1.0.x) is Spring AI 1.1.x / Spring Boot 3 compatible and [v2.0.x](https://github.com/spring-ai-community/spring-ai-tool-search-tool) is Spring AI 2.x / Spring Boot 4 compatible.*
**Example Usage**
```java theme={null}
@SpringBootApplication
public class Application {
@Bean
CommandLineRunner demo(ChatClient.Builder builder, ToolSearcher toolSearcher) {
return args -> {
var advisor = ToolSearchToolCallAdvisor.builder()
.toolSearcher(toolSearcher)
.build();
ChatClient chatClient = builder
.defaultTools(new MyTools())
.defaultAdvisors(advisor)
.build();
var answer = chatClient.prompt("""
Help me plan what to wear today in Amsterdam.
Please suggest clothing shops that are open right now.
""").call().content();
System.out.println(answer);
};
}
static class MyTools {
@Tool(description = "Get the weather for a given location at a given time")
public String weather(String location,
@ToolParam(description = "YYYY-MM-DDTHH:mm") String atTime) {...}
@Tool(description = "Get clothing shop names for a given location at a given time")
public List clothing(String location,
@ToolParam(description = "YYYY-MM-DDTHH:mm") String openAtTime) {...}
@Tool(description = "Current date and time for a given location")
public String currentTime(String location) {...}
// ... potentially hundreds more tools
}
}
```
For the example above, the flow would be:
1. **User Request**: *"Help me plan what to wear today in Amsterdam. Please suggest clothing shops that are open right now."*
2. **Initialization**: Index all tools: `weather`, `clothing`, `currentTime` (+ potentially 100s more)
3. **First LLM Call** - LLM sees only `toolSearchTool`
* LLM calls `toolSearchTool(query="current time date")` → `["currentTime"]`
4. **Second LLM Call** - LLM sees `toolSearchTool` + `currentTime`
* LLM calls `currentTime("Amsterdam")` → `"2025-12-08T11:30"`
* LLM calls `toolSearchTool(query="weather location")` → `["weather"]`
5. **Third LLM Call** - LLM sees `toolSearchTool` + `currentTime` + `weather`
* LLM calls `weather("Amsterdam")` → `"Sunny, 15°C"`
* LLM calls `toolSearchTool(query="clothing shops")` → `["clothing"]`
6. **Fourth LLM Call** - LLM sees `toolSearchTool` + `currentTime` + `weather` + `clothing`
* LLM calls `clothing("Amsterdam", "2025-12-08T11:30")` → `["H&M", "Zara", "Uniqlo"]`
7. **Final Response**: *"Based on the sunny 15°C weather in Amsterdam, I recommend light layers. Here are clothing shops open now: H\&M, Zara, ..."*
## Performance Measurements
> ⚠️ **Disclaimer:** These are preliminary, manual measurements taken after a few runs. They are not averaged across multiple iterations and should be considered illustrative rather than representative.
To quantify the token savings, we ran preliminary benchmarks using the [demo application](https://github.com/spring-ai-community/spring-ai-tool-search-tool/tree/main/examples/tool-search-tool-demo) with the following setup:
* **Task**: *"Help me plan what to wear today in Amsterdam. Please suggest clothing shops that are open right now."*
* **28 total tools**: 3 relevant tools (`weather`, `clothing`, `currentTime`) + 25 unrelated "dummy" tools, deliberately **not relevant** to the weather/clothing task, demonstrating how the tool search efficiently discovers only the needed tools among many unrelated options.
* **Search strategies**: Lucene (keyword-based) and VectorStore (semantic)
* **Models tested**: Gemini (`gemini-3-pro-preview`), OpenAI (`gpt-5-mini-2025-08-07`), Anthropic (`claude-sonnet-4-5-20250929`)
The measurements are collected using a custom [TokenCounterAdvisor](https://github.com/spring-ai-community/spring-ai-tool-search-tool/blob/main/examples/tool-search-tool-demo/src/main/java/org/springaicommunity/tool/search/TokenCounterAdvisor.java) that tracks and aggregates the token usage.
#### Results with Lucene Search
| Model | Approach | Total Tokens | Prompt Tokens | Completion Tokens | Requests | **Savings** |
| ------------- | ----------- | ------------ | ------------- | ----------------- | -------- | ----------- |
| **Gemini** | With TST | 2,165 | 1,412 | 231 | 4 | **60%** |
| | Without TST | 5,375 | 4,800 | 176 | 3 | — |
| **OpenAI** | With TST | 4,706 | 2,770 | 1,936 | 5 | **34%** |
| | Without TST | 7,175 | 5,765 | 1,410 | 3 | — |
| **Anthropic** | With TST | 6,273 | 5,638 | 635 | 5 | **64%** |
| | Without TST | 17,342 | 16,752 | 590 | 4 | — |
#### Results with VectorStore Search
| Model | Approach | Total Tokens | Prompt Tokens | Completion Tokens | Requests | **Savings** |
| ------------- | ----------- | ------------ | ------------- | ----------------- | -------- | ----------- |
| **Gemini** | With TST | 2,214 | 1,502 | 234 | 4 | **57%** |
| | Without TST | 5,122 | 4,767 | 73 | 3 | — |
| **OpenAI** | With TST | 3,697 | 2,109 | 1,588 | 4 | **47%** |
| | Without TST | 6,959 | 5,771 | 1,188 | 3 | — |
| **Anthropic** | With TST | 6,319 | 5,642 | 677 | 5 | **63%** |
| | Without TST | 17,291 | 16,744 | 547 | 4 | — |
#### Key Observations
* **Significant token savings across all models**: The Tool Search Tool pattern achieved **34-64% reduction** in total token consumption depending on the model and search strategy.
* **Prompt tokens are the key driver**: The savings come primarily from reduced prompt tokens - with TST, only discovered tool definitions are included rather than all 28 tools upfront.
* **Trade-off: More requests, fewer tokens**: TST requires 4-5 requests vs 3-4 without, but the total token cost is significantly lower.
* **Both search strategies perform similarly**: Lucene and VectorStore produced comparable results, with VectorStore showing slightly better efficiency for OpenAI in this test.
* **All models successfully completed the task**: All three models (Gemini, OpenAI, Anthropic) figured out that they needed to call `currentTime` before invoking the other tools, demonstrating correct reasoning about tool dependencies.
* **Different tool discovery strategies**: Models exhibited varying approaches—some managed to request all necessary tools upfront, while others discovered them one by one. However, all models leveraged parallel tool calling when possible to optimize execution.
* **Older models may struggle**: The older model versions may have difficulty with the tool search pattern, potentially missing required tools or making suboptimal discovery decisions. Consider adding a custom [systemMessageSuffix](https://github.com/spring-ai-community/spring-ai-tool-search-tool/tree/main/tool-search-tool#toolsearchtoolcalladvisorbuilder) to provide additional guidance to the model, experiment with different tool-searcher configurations or pair this approach with the [LLM as Judge pattern](https://spring.io/blog/2025/11/10/spring-ai-llm-as-judge-blog-post) to ensure reliable and consistent behavior across different models.
## When to Use
| Tool Search Tool Approach | Traditional Approach |
| -------------------------------------------------- | ------------------------------------------ |
| 20+ tools in your system | Small tool library (\<20 tools) |
| Tool definitions consuming >5K tokens | All tools frequently used in every session |
| Building MCP-powered systems with multiple servers | Very compact tool definitions |
| Experiencing tool selection accuracy issues | |
## Next Steps
As the [Tool Search Tool project](https://github.com/spring-ai-community/spring-ai-tool-search-tool) matures and proves its value within the [Spring AI Community](https://github.com/spring-ai-community), we may consider adding it to the core Spring AI project.
For **deterministic tool selection without LLM involvement**, explore the [Pre-Select Tool Demo](https://github.com/spring-ai-community/spring-ai-tool-search-tool/tree/main/examples/pre-select-tool-demo) and the experimental [`PreSelectToolCallAdvisor`](https://github.com/spring-ai-community/spring-ai-tool-search-tool/blob/main/examples/pre-select-tool-demo/src/main/java/org/springaicommunity/tool/search/PreSelectToolCallAdvisor.java).
Unlike the agentic `ToolSearchToolCallAdvisor`, this advisor pre-selects tools based on message content **before** the LLM call—ideal for **Chain of Thought patterns** where a preliminary reasoning step explicitly names the required tools.
Also, you can consider combining the Tool Search Tool with [LLM-as-a-Judge patterns](https://spring.io/blog/2025/11/10/spring-ai-llm-as-judge-blog-post) to ensure discovered tools actually fulfill the user's task. A judge model could evaluate whether the dynamically selected tools produced satisfactory results and improve the tool discovery if needed.
Try the current implementation and provide feedback to help shape its evolution into a first-class Spring AI feature.
## Conclusion
The Tool Search Tool pattern is a step toward scalable AI agents. By combining Anthropic's innovative approach with Spring AI's **portable abstraction**, we can build systems that efficiently manage thousands of tools while maintaining high accuracy **across any LLM provider**.
**The power of Spring AI's recursive advisor architecture** is that it allows us to implement sophisticated tool discovery workflows that work universally - whether you're using OpenAI's GPT models, Anthropic's Claude, local Ollama models, or any other LLM supported by Spring AI. You get the same dynamic tool discovery benefits without being locked into a specific provider's native implementation.
## References
* **Anthropic Tool Search Tool Pattern**: [Advanced Tool Use](https://www.anthropic.com/engineering/advanced-tool-use)
* **Spring AI Tool Search Tool Implementation**: [GitHub Repository](https://github.com/spring-ai-community/spring-ai-tool-search-tool)
* **Spring AI Tools Documentation**: [Tools API Reference](https://docs.spring.io/spring-ai/reference/api/tools.html)
* **Spring AI Recursive Advisors**: [Advisors API Reference](https://docs.spring.io/spring-ai/reference/api/advisors-recursive.html)
* **Spring AI Recursive Advisors Blog**: [Spring AI Recursive Advisors](https://spring.io/blog/2025/11/04/spring-ai-recursive-advisors)
# Claude Agent SDK for Java
Source: https://springaicommunity.mintlify.app/claude-agent-sdk/index
A Java SDK for integrating with Claude Code CLI, enabling programmatic control of Claude as an AI coding agent.
This project has moved to [markpollack/claude-agent-sdk-java](https://github.com/markpollack/claude-agent-sdk-java).
Current documentation is at [lab.pollack.ai/projects/claude-agent-sdk](https://lab.pollack.ai/projects/claude-agent-sdk).
The content below may be outdated.
A Java SDK for integrating with Claude Code CLI, enabling programmatic control of Claude as an AI coding agent.
## Overview
The Claude Agent SDK allows Java applications to:
* Execute queries and receive responses from Claude
* Maintain multi-turn conversation sessions
* Control tool permissions and safety settings
* Integrate with MCP (Model Context Protocol) servers
* Intercept and customize tool execution with hooks
## Three-API Architecture
| API | Class | Programming Style | Best For |
| ------------ | ------------------- | ----------------- | ----------------------------------------------- |
| **One-shot** | `Query` | Static methods | CLI tools, scripts, simple queries |
| **Blocking** | `ClaudeSyncClient` | Iterator-based | Traditional applications, synchronous workflows |
| **Reactive** | `ClaudeAsyncClient` | Flux/Mono | Non-blocking applications, high concurrency |
Both `ClaudeSyncClient` and `ClaudeAsyncClient` support the full feature set: multi-turn conversations, hooks, MCP integration, and permission callbacks. They differ only in programming paradigm (blocking vs non-blocking).
## Quick Start
Add the dependency to your project:
```xml theme={null}
org.springaicommunity
claude-code-sdk
1.0.0-SNAPSHOT
```
### Simple Query
```java theme={null}
import org.springaicommunity.claude.agent.sdk.Query;
String answer = Query.text("What is 2 + 2?");
System.out.println(answer); // "4"
```
### Multi-Turn Conversation
Both clients support multi-turn conversations with full context preservation. Choose based on your programming paradigm preference:
```java theme={null}
import org.springaicommunity.claude.agent.sdk.ClaudeClient;
import org.springaicommunity.claude.agent.sdk.ClaudeSyncClient;
import java.nio.file.Path;
try (ClaudeSyncClient client = ClaudeClient.sync()
.workingDirectory(Path.of("."))
.build()) {
String response1 = client.connectText("My favorite color is blue.");
System.out.println(response1);
String response2 = client.queryText("What is my favorite color?");
System.out.println(response2); // "blue"
String response3 = client.queryText("Spell it backwards.");
System.out.println(response3); // "eulb"
}
```
```java theme={null}
import org.springaicommunity.claude.agent.sdk.ClaudeClient;
import org.springaicommunity.claude.agent.sdk.ClaudeAsyncClient;
import java.nio.file.Path;
ClaudeAsyncClient client = ClaudeClient.async()
.workingDirectory(Path.of("."))
.build();
// Multi-turn with elegant flatMap chaining
client.connect("My favorite color is blue.").text()
.doOnSuccess(System.out::println)
.flatMap(r1 -> client.query("What is my favorite color?").text())
.doOnSuccess(System.out::println) // "blue"
.flatMap(r2 -> client.query("Spell it backwards.").text())
.doOnSuccess(System.out::println) // "eulb"
.subscribe(); // Non-blocking
```
## Documentation
Complete API documentation for all classes, methods, and types
Step-by-step guide from basics to advanced patterns
## Resources
* [GitHub Repository](https://github.com/spring-ai-community/claude-agent-sdk-java) - Source code and examples
* [Claude Code Documentation](https://docs.anthropic.com/en/docs/agents-and-tools/claude-code/overview) - Official Claude Code docs
# Contributors
Source: https://springaicommunity.mintlify.app/community/contributors
The people behind Spring AI Community projects
## Project Leads
Spring AI Community projects are driven by passionate developers from around the world. Each project is typically led by individual contributors who maintain and evolve their integrations and tools.
***
## Get Involved
Interested in leading a Spring AI Community project? Check out our [Project Guide](/community/project-guide) to learn how to propose and create new integrations.
# Governance
Source: https://springaicommunity.mintlify.app/community/governance
Lightweight governance structure emphasizing autonomy and rapid decision-making
## Governance Model
The Spring AI Community governance model is designed to be lightweight and developer-friendly, emphasizing autonomy for project owners while providing just enough structure to ensure coherence within the ecosystem. This model prioritizes flexibility, rapid decision-making, and minimizes bureaucracy.
Our goal is to enable project owners to have the most say in how their projects develop while ensuring basic compatibility with Spring AI's core values and technical approach.
## Spring AI Community Leads
The Spring AI Community Leads consist of **Thomas Vitale, Sergi Almar, and Adib Saikali**. These leads help oversee the community organization and provide guidance when needed.
While there is no fixed term for these positions, the group should ideally maintain an odd number of members to prevent tied votes in decision-making processes.
## IP Ownership
Project contributors **retain ownership of their intellectual property**. All contributions must be made under the Apache 2.0 license to ensure compatibility with the Spring ecosystem, but Broadcom (the owner of Spring) takes no control of the IP for projects within this process.
## Lightweight Governance Structure
The Spring AI Community follows a technical leadership model focused on rapid decision-making and technical excellence:
* **Project Technical Leads** have full authority over technical decisions within their project (in compliance with code of conduct and security guidelines)
## Project Acceptance
Project acceptance into the spring-ai-community requires **unanimous approval from all Spring AI Community Leads**
Discussions and voting for project acceptance take place within the GitHub issue that's automatically created when a new project submission form is filled out
If unanimous approval cannot be reached, the project may be reconsidered after addressing feedback
Decisions are made within 2 weeks of submission when possible
## Project Guidance
* Projects are intended to be as **autonomous as possible** with Technical Leads driving their direction
* Technical disagreements within projects should first be addressed by Project Technical Leads
* If assistance is needed, Project Leads can mention Spring AI Community Leads in a GitHub issue on their project repository
* The Spring AI Community Leads serve as a resource for mediation if requested and as the final escalation path for significant technical disagreements
* Decisions made during conflict resolution require majority agreement among Community Leads
## Project Communication
Each project uses the following communication channels:
For technical decisions and community interaction within their own repository
For bug reports and feature requests within the project repository
For project leads to discuss administrative matters
# Spring AI Community
Source: https://springaicommunity.mintlify.app/community/index
Creating an easy path for people to contribute Spring AI related projects
## Welcome to the Spring AI Community
The main goal of the Spring AI Community GitHub organization is to create an easy path for people to contribute Spring AI related projects. The need for a GitHub organization stems from the Spring AI project receiving many pull requests for additional features and functionality that the core team can't easily maintain or nurture.
By creating this GitHub organization, we hope that an ecosystem of community-driven projects can develop to fill this gap. Having a known 'hub' for Spring AI related projects will help foster discovery and encourage more features and projects to be developed.
This community describes the process to create a project, how projects are managed, and how the Spring AI project will incorporate these community projects in a manner similar to other community projects in the Spring ecosystem, such as those for the Spring Cloud and Spring Data projects.
## Propose a New Project
We're always looking to support new integrations and community needs.
To propose a new subproject or integration:
Create a new issue in the community repository to get started
## Explore Our Projects
Explore our complete catalog of community projects
## Learn More
Lightweight governance model and community leads
Requirements and process for creating projects
Join our community and contribute
# Spring AI Integration
Source: https://springaicommunity.mintlify.app/community/integration
How community projects are promoted alongside the main Spring AI project
## Official Spring AI Community Projects
Much like with Spring Cloud and Spring Data, there is a known set of stable community projects that are promoted alongside the main project. These appear on the project page on spring.io and are also incorporated into the reference documentation.
The Spring AI team will decide which community projects will be officially recognized. The goal is to establish a quality bar so that users don't encounter outdated projects.
## Bill of Materials (BOM) Policy
Based on feedback from previous community project experiences, **community projects will not be listed in the Spring AI BOM** (bill of materials).
This decision ensures that the Spring AI core team maintains control over compatibility guarantees while still supporting the community ecosystem.
## Requirements for Official Listing
Projects seeking to be listed as official Spring AI Community projects on the Spring AI website and documentation must demonstrate ongoing health and activity.
### Evaluation Criteria
* Review by the Spring AI team (typically quarterly)
* Public GitHub activity metrics (commits, issue responses, PR reviews)
**Build & Testing**
* Passing CI pipeline with unit and/or integration tests
**Documentation**
* Up-to-date project documentation that follows Spring AI's format and standards
**Compatibility**
* Compatibility with the latest Spring AI release
* Alignment with Spring AI's architecture, coding standards, and integration patterns
Code quality and structure must meet Spring team standards for potential inclusion in the core project, including:
* Proper use of Spring abstractions
* Consistent error handling
* Alignment with Spring's programming model
### No Formal Reporting Required
No formal reporting is required from project maintainers beyond what is publicly visible in repositories. The Spring AI team will use these public indicators to determine which community projects to promote.
## Project Lifecycle Management
### Active Projects
Projects that remain active and meet quality standards will continue to be promoted on:
* Spring AI project page on spring.io
* Spring AI reference documentation
* Spring AI community listings
### Inactive Projects
Projects that remain inactive for extended periods (6+ months) or fall below quality standards may be:
* Removed from official listings
* Remain in the spring-ai-community organization
* Potentially become candidates for archival
This ensures that users always find maintained, high-quality projects when browsing official Spring AI Community recommendations.
# Project Creation Guide
Source: https://springaicommunity.mintlify.app/community/project-guide
Requirements and process for creating a Spring AI Community project
## Project Creation Process
You can apply to create a new project using the community Issue Form in the community repository. After submission, a GitHub issue will be automatically created where the Spring AI Community Leads will discuss your proposal with you. This discussion will help determine if your project meets the necessary requirements for inclusion.
Create a new issue in the community repository
## Project Requirements
A functioning implementation that uses artifacts (dependencies, libraries) from the Spring AI project and demonstrates integration with Spring AI's core APIs. The code should show clear value to the Spring AI ecosystem and solve a real problem that other developers face.
Projects must provide a clear, concise description of their purpose, scope, and goals. This should include:
* What problems the project solves
* Who the intended users are
* How it fits within the Spring AI ecosystem
This helps prevent scope creep and ensures alignment with Spring AI's mission.
Projects must have at least one committed developer.
Documentation must clearly explain what the project does, how to get started, and basic usage examples. While it doesn't need to be exhaustive at this stage, it should be sufficient for other developers to understand and begin using the project. All documentation must be in English to ensure accessibility to the global Spring community.
The project must include a basic suite of integration tests that demonstrate proper functionality and integration with Spring AI. These tests should verify the core features and integration points, ensuring reliability and making it easier to identify breaking changes.
Maintainers must agree to follow the Spring AI code of conduct. This ensures alignment with Spring AI's values and practices while fostering a collaborative community environment.
This is for maximum license compatibility with the Spring ecosystem.
All development must occur in a public repository with transparent processes for contributions and issue tracking. This can all occur on GitHub. This ensures community visibility and encourages collaboration while building trust in the project's development process.
The project should define contribution guidelines. Can use existing contribution guidelines such as the [Spring Framework Contributing Guide](https://github.com/spring-projects/spring-framework/blob/main/CONTRIBUTING.md) as a basis. The guidelines need to be clear and welcoming to new contributors.
## Versioning Requirements
Projects must follow semantic versioning (MAJOR.MINOR.PATCH):
```text Non-stable versions theme={null}
0.x versions (pre-1.0)
Example: 0.1.0, 0.2.5, 0.9.3
```
```text Stable versions theme={null}
1.x or higher
Example: 1.0.0, 2.3.1, 3.0.0
```
## Project Naming and Package Guidelines
### Naming
Project names typically follow the pattern `spring-ai-[key-feature]`
Examples: `spring-ai-swarm`, `spring-ai-vectorstore`
Projects aren't strictly limited to this pattern, but should be descriptive and relevant
Names must not be offensive or inappropriate
All projects should follow common Spring naming conventions/patterns for classes
Final project name is handled on a case-by-case basis during the submission process.
### Packaging
You have two options for publishing to Maven Central:
Publish using GitHub's process for projects in an org to release into Maven Central using `io.github.spring-ai-community` as the groupId
Publish to Maven Central in your own bespoke manner with your own groupId
* Free choice of the Java root package name
## Commercial and Organizational Structure
**Commercial projects are welcome!**
* Commercial ownership/control is acceptable
* Single-vendor projects are welcome
* Projects should be transparent about their commercial relationships
# Project Lead Guide
Source: https://springaicommunity.mintlify.app/community/project-lead-guide
Step-by-step setup for CI/CD, snapshots, and releases using shared community workflows
This guide walks project leads through adopting the shared [community-workflows](https://github.com/spring-ai-community/community-workflows) infrastructure for CI, snapshot publishing, and Maven Central releases.
## Prerequisites
Before starting, ensure you have:
* A repository under the `spring-ai-community` GitHub organization
* Maven wrapper (`./mvnw`) in your repository root — if missing, run `mvn wrapper:wrapper` to generate it
* Standard Maven project structure
* Repository admin access (for configuring secrets)
## Step 1: Add CI Workflow
Create `.github/workflows/ci.yml` in your repository:
```yaml theme={null}
name: CI Build
on:
push:
branches: [main]
pull_request:
branches: [main]
jobs:
build:
uses: spring-ai-community/community-workflows/.github/workflows/ci-build.yml@main
```
This runs `clean verify -B` on every push and PR. Optional inputs:
| Input | Default | Description |
| --------------------- | ----------------- | ------------------------------------ |
| `java-version` | `17` | Java version |
| `java-distribution` | `temurin` | Java distribution |
| `maven-goals` | `clean verify -B` | Maven goals to run |
| `skip-tests` | `false` | Skip tests |
| `upload-test-results` | `true` | Upload Surefire reports as artifacts |
## Step 2: Add Snapshot Publishing
Create `.github/workflows/publish-snapshot.yml`:
```yaml theme={null}
name: Publish Snapshot
on:
push:
branches: [main]
jobs:
publish:
uses: spring-ai-community/community-workflows/.github/workflows/publish-snapshot.yml@main
secrets:
MAVEN_USERNAME: ${{ secrets.MAVEN_USERNAME }}
MAVEN_PASSWORD: ${{ secrets.MAVEN_PASSWORD }}
```
Every push to `main` publishes a SNAPSHOT to Maven Central. This requires the `MAVEN_USERNAME` and `MAVEN_PASSWORD` secrets (see [Secrets Configuration](#secrets-configuration)).
## Step 3: Add Release Workflow
Create `.github/workflows/release.yml`:
```yaml theme={null}
name: Release
on:
workflow_dispatch:
inputs:
version:
description: 'Release version (e.g., 0.1.0)'
required: true
jobs:
release:
uses: spring-ai-community/community-workflows/.github/workflows/maven-central-release.yml@main
with:
version: ${{ inputs.version }}
secrets:
MAVEN_USERNAME: ${{ secrets.MAVEN_USERNAME }}
MAVEN_PASSWORD: ${{ secrets.MAVEN_PASSWORD }}
GPG_SECRET_KEY: ${{ secrets.GPG_SECRET_KEY }}
GPG_PASSPHRASE: ${{ secrets.GPG_PASSPHRASE }}
```
The release workflow:
1. Sets the POM version to the specified release version
2. Verifies no SNAPSHOT dependencies remain
3. Builds and runs tests
4. Deploys to Maven Central with GPG signing (using the `release` profile)
5. Creates a Git tag (e.g., `v0.1.0`) and GitHub Release
Optional inputs:
| Input | Default | Description |
| -------------- | ------- | ---------------------------------------- |
| `java-version` | `17` | Java version |
| `skip-tests` | `false` | Skip tests |
| `create-tag` | `true` | Create and push a Git tag |
| `tag-prefix` | `v` | Tag prefix (e.g., `v` produces `v0.1.0`) |
## Secrets Configuration
### Organization-Level Secrets (Already Configured)
These secrets are set at the GitHub organization level. Your repository needs to be granted access to them (ask an org admin if they aren't available):
| Secret | Description |
| ---------------- | -------------------------------- |
| `MAVEN_USERNAME` | Sonatype Central Portal username |
| `MAVEN_PASSWORD` | Sonatype Central Portal token |
| `GPG_SECRET_KEY` | ASCII-armored GPG private key |
| `GPG_PASSPHRASE` | GPG key passphrase |
### Repository-Level Secrets
If your project uses CLI tools for integration tests, set these at the **repository** level (Settings → Secrets and variables → Actions):
| Secret | Description | Required By |
| ------------------- | -------------------------------- | ------------------------- |
| `ANTHROPIC_API_KEY` | Anthropic API key for Claude CLI | Projects using Claude CLI |
| `GEMINI_API_KEY` | Google API key for Gemini CLI | Projects using Gemini CLI |
Repository-level secrets keep API keys scoped per-project for billing and access control. Do not set API keys at the organization level.
## POM Requirements
The release workflow deploys with `-Prelease`, which activates a Maven profile that handles Central Publishing, GPG signing, and source/javadoc JAR generation.
If your project inherits from `community-parent`, the `release` profile is already provided. Just add the parent to your POM:
```xml theme={null}
org.springaicommunity
spring-ai-community-parent
1.0.0-SNAPSHOT
```
This gives you the full release profile automatically — `central-publishing-maven-plugin`, `maven-gpg-plugin`, `maven-source-plugin`, and `maven-javadoc-plugin` are all preconfigured. It also provides `distributionManagement` for snapshot publishing.
You must add the Central snapshots repository so Maven can resolve the parent POM:
```xml theme={null}
central-snapshots
Maven Central Snapshots
https://central.sonatype.com/repository/maven-snapshots/
true
false
```
If your project does not use `community-parent`, add a `release` profile to your root `pom.xml` manually:
```xml theme={null}
release
org.sonatype.central
central-publishing-maven-plugin
0.9.0
true
central
true
org.apache.maven.plugins
maven-gpg-plugin
3.2.7
sign-artifacts
verify
sign
--pinentry-mode
loopback
```
You must also include `maven-source-plugin` and `maven-javadoc-plugin` in the release profile — Maven Central requires source and javadoc JARs.
You also need `distributionManagement` for snapshot publishing:
```xml theme={null}
central
https://central.sonatype.com/repository/maven-snapshots/
```
## Performing a Release
### Option A: GitHub Actions UI (workflow\_dispatch)
This is the primary release method:
Go to your repository on GitHub and click the **Actions** tab.
In the left sidebar, click **Release**.
Click **Run workflow**, enter the release version (e.g., `0.1.0`), and click **Run workflow**.
Watch the workflow run. It will set the version, build, deploy to Maven Central, create a Git tag, and publish a GitHub Release.
### Option B: Release Script (CLI)
For command-line releases, use the release script from the `community-workflows` repository:
```bash theme={null}
# Dry run first
python3 spring-ai-community-release.py my-project 0.1.0 --dry-run
# Actual release
python3 spring-ai-community-release.py my-project 0.1.0
```
The script performs a fresh checkout, sets the version, builds, tags, pushes, and optionally triggers the GitHub Actions release workflow.
### Option C: PR-Based Releases (Optional)
For projects that prefer PR-driven releases, copy `.github/project.yml.template` from `community-workflows` to `.github/project.yml` in your repository:
```yaml theme={null}
name: my-project
release:
current-version: "0.1.0-SNAPSHOT"
next-version: "0.2.0-SNAPSHOT"
integration:
uses-reusable-workflows: true
pr-based-releases: false # Set to true to enable
java-version: "17"
```
When `pr-based-releases` is set to `true`, merging a PR that changes `release.current-version` to a non-SNAPSHOT version (e.g., `0.1.0`) automatically triggers the release workflow.
## Projects Using Shared Workflows
| Project | Description | Workflow Type |
| ------------------------------------------------------------------------------------- | ----------------------------------------- | ------------- |
| [agent-sandbox](https://github.com/spring-ai-community/agent-sandbox) | Sandbox for secure code execution | Simple |
| [agent-judge](https://github.com/spring-ai-community/agent-judge) | Judge framework for evaluating AI outputs | Simple |
| [agent-client](https://github.com/spring-ai-community/spring-ai-agents) | Agent client for Spring AI | With CLI |
| [claude-agent-sdk-java](https://github.com/spring-ai-community/claude-agent-sdk-java) | Claude Code SDK for Java | With CLI |
| [spring-ai-replicate](https://github.com/spring-ai-community/spring-ai-replicate) | Spring AI integration for Replicate | Simple |
## CLI Tools Variant
Projects that require CLI tools (Claude, Gemini, Vendir) for integration tests should use the `-with-cli` workflow variants. These add:
* Node.js setup and CLI installation
* API keys passed as environment variables to Maven
* Optional commit message validation (blocks AI attribution markers)
Example CI with CLI tools:
```yaml theme={null}
name: CI Build
on:
push:
branches: [main]
pull_request:
branches: [main]
jobs:
build:
uses: spring-ai-community/community-workflows/.github/workflows/ci-build-with-cli.yml@main
with:
install-claude-cli: true
install-gemini-cli: true
install-vendir-cli: true
validate-commits: true
secrets:
ANTHROPIC_API_KEY: ${{ secrets.ANTHROPIC_API_KEY }}
GEMINI_API_KEY: ${{ secrets.GEMINI_API_KEY }}
```
The `-with-cli` variants are available for all three workflows: `ci-build-with-cli.yml`, `publish-snapshot-with-cli.yml`, and `maven-central-release-with-cli.yml`.
Additional inputs for CLI variants:
| Input | Default | Description |
| -------------------- | -------- | ---------------------------------------- |
| `install-claude-cli` | `false` | Install Claude Code CLI |
| `install-gemini-cli` | `false` | Install Gemini CLI |
| `install-vendir-cli` | `false` | Install Vendir CLI |
| `vendir-version` | `0.44.0` | Vendir version to install |
| `validate-commits` | `false` | Check commits for AI attribution markers |
## Troubleshooting
Organization-level secrets must be explicitly granted access to your repository. Ask an org admin to add your repository to the secret's access list under **Organization Settings → Secrets → Repository access**.
If CI fails with `Non-resolvable parent POM for ... spring-ai-community-parent`, your POM is missing the Central snapshots repository. Add it to your `repositories` section:
```xml theme={null}
central-snapshots
https://central.sonatype.com/repository/maven-snapshots/
true
false
```
The release workflow checks that no POM files contain SNAPSHOT references after setting the release version. If you have SNAPSHOT dependencies on other community projects, those projects must be released first.
Ensure the `GPG_SECRET_KEY` secret contains the full ASCII-armored private key. Export it with:
```bash theme={null}
gpg --armor --export-secret-keys KEY_ID > private-key.asc
```
The entire contents of `private-key.asc` (including the `BEGIN` and `END` lines) should be the secret value.
Verify your credentials work by logging in at [central.sonatype.com](https://central.sonatype.com). Try publishing a SNAPSHOT first to confirm the credentials are valid.
Ensure you're using the `-with-cli` workflow variant and have set the `install-*` inputs to `true`. Check that the corresponding API key secrets are configured at the repository level.
# Release Management
Source: https://springaicommunity.mintlify.app/community/releases
Guidelines for releasing Spring AI Community projects
Looking for hands-on setup instructions? See the [Project Lead Guide](/community/project-lead-guide) for step-by-step CI/CD, snapshot, and release workflow configuration.
## Release Strategy
Releases may align with:
* Spring AI OSS releases
* Commercial product releases
* Independent schedules
Projects have full flexibility in their release timing and strategy.
## Spring AI Team Support
The Spring AI Team can assist with:
Bootstrapping initial repositories
Providing a standardized project template
Setting up CI/CD workflows using GitHub Actions
## Release Requirements
All projects must follow a clear [Semantic Versioning](https://semver.org/) (semver) scheme:
* **MAJOR**: Breaking changes
* **MINOR**: New features (backwards compatible)
* **PATCH**: Bug fixes (backwards compatible)
All tests and quality checks must pass before release
Documentation must reflect any new features, changes, or deprecations
A well-structured changelog describing what has changed
## Maven Central Publication
### Preferred Path
The preferred release path is via GitHub Actions in the community repository
Publish to Maven Central using GitHub-based publishing conventions
Artifacts should use the groupId `io.github.springaicommunity`
### Artifact Naming
* Artifact IDs (e.g., `spring-ai-rag-helper`) may include dashes and should follow standard naming patterns
* Root Java package names are flexible and up to the contributor, though they should follow common Spring conventions
This naming suggestion is specific to the GitHub-based Maven Central process. Project owners can use their own bespoke process and their own artifact IDs to publish to a public Maven repository.
The release templates for community-hosted repositories **cannot use Spring's internal Maven Central credentials** — credential sharing is not permitted.
# Get Involved
Source: https://springaicommunity.mintlify.app/get-involved/index
Join the Spring AI Community and contribute to the ecosystem
## Ways to Contribute
The Spring AI Community thrives on contributions from developers, organizations, and enthusiasts. Here's how you can get involved:
Have an idea for a Spring AI integration or tool? Submit a project proposal to join our ecosystem.
Browse our projects and contribute code, documentation, or ideas to existing initiatives.
Help us improve by sharing your experience, suggestions, and use cases.
Write blog posts, create tutorials, or present at conferences about Spring AI Community projects.
## Proposing a New Project
Ready to add your project to the Spring AI Community? Follow these steps:
Read the [Project Creation Guide](/community/project-guide) to understand what's needed
Ensure you have:
* A working proof of concept
* Clear project scope and description
* Basic documentation in English
* Unit and integration tests
* Apache 2.0 license
Create an issue using our project proposal template:
Create a new issue in the community repository
The three Community Leads will review your proposal and discuss with you in the GitHub issue
Projects require **unanimous approval** from all three Community Leads to be accepted
## Contributing to Existing Projects
All Spring AI Community projects welcome contributions. Here's how to get started:
1. **Find a project** - Browse our [project catalog](/projects)
2. **Fork the repository** - Create your own fork on GitHub
3. **Make changes** - Follow the project's contribution guidelines
4. **Submit a PR** - Open a pull request with your changes
5. **Collaborate** - Work with maintainers to refine your contribution
* Improve existing documentation
* Add examples and tutorials
* Translate documentation (if project supports it)
* Fix typos and clarify confusing sections
* Write additional tests
* Report bugs with reproduction steps
* Test pre-release versions
* Improve test coverage
* Answer questions in GitHub Discussions
* Help triage issues
* Review pull requests
* Mentor new contributors
## Communication Channels
Each project has its own GitHub Discussions for:
* Technical discussions
* Feature requests
* Community Q\&A
* Project announcements
Use GitHub Issues for:
* Bug reports
* Feature requests
* Project proposals
* Documentation improvements
Project leads have access to a Slack workspace for:
* Administrative discussions
* Cross-project coordination
* Community governance
## Community Guidelines
All participants in the Spring AI Community are expected to follow our guidelines:
Follow the Spring AI code of conduct in all interactions
Each project has specific contribution guidelines—please review them before contributing
All contributions must be compatible with the Apache 2.0 license
All development happens in public repositories with open discussions
## Recognition
We value all contributions to the Spring AI Community:
All code contributors are recognized in project repositories
Lead maintainers have full autonomy over their projects
Exceptional contributors may be invited to join as Community Leads
High-quality projects may be promoted on the Spring AI website and documentation
## Questions?
Have questions about getting involved?
Visit our main community repository
Open an issue to ask questions or get clarification
***
**Thank you for your interest in the Spring AI Community!** We look forward to your contributions and collaboration.
# Moonshot
Source: https://springaicommunity.mintlify.app/projects/attic/moonshot
Java client for Moonshot AI API with Spring AI integration
![]() This project is no longer actively maintained.
[GitHub](https://github.com/spring-ai-community/moonshot) • [Maven](https://central.sonatype.com/artifact/org.springframework.ai.moonshot/moonshot-core)
## Overview
The Moonshot AI Java Client provides a comprehensive Java implementation for the Moonshot AI API. It is based on the Spring AI project's Moonshot integration and has been extracted to be used as a standalone library.
Moonshot AI provides powerful Chinese language models with varying context windows to suit different use cases.
## Features
Comprehensive implementation supporting moonshot-v1-8k, moonshot-v1-32k, and moonshot-v1-128k
Extensive customization options including temperature, max tokens, and top-p sampling
Support for token-by-token streaming for interactive applications
Register custom Java functions that Moonshot models can intelligently invoke
Built-in retry mechanism with configurable exponential backoff
Integration with Micrometer for metrics collection and performance monitoring
## Quick Start
### Add Dependency
```xml theme={null}
org.springframework.ai.moonshot
moonshot-core
0.1.0-SNAPSHOT
```
### Basic Usage
```java theme={null}
// Create the Moonshot API client
MoonshotApi moonshotApi = new MoonshotApi("your-api-key");
// Create the chat model
MoonshotChatModel chatModel = new MoonshotChatModel(moonshotApi);
// Create a prompt
UserMessage userMessage = new UserMessage("Tell me a joke about programming");
Prompt prompt = new Prompt(List.of(userMessage));
// Get the response
ChatResponse response = chatModel.call(prompt);
String content = response.getResult().getOutput().getContent();
System.out.println(content);
```
## Project Structure
This is a multi-module Maven project:
* **`moonshot-parent`** - Parent POM with dependency management
* **`moonshot-core`** - Core implementation of the Moonshot AI client
* **`docs`** - Documentation module built with Antora
## Requirements
* Java 17 or higher
* Maven 3.6.3 or higher
## Resources
View source code and contribute
Full documentation (will be published to GitHub Pages)
## License
This project is licensed under the [Apache License 2.0](https://github.com/spring-ai-community/moonshot/blob/main/LICENSE).
# QianFan
Source: https://springaicommunity.mintlify.app/projects/attic/qianfan
Spring AI integration with Baidu's QianFan AI platform
![Attic Status]() This project is no longer actively maintained.
## Overview
Spring AI QianFan provides integration with Baidu's QianFan AI platform, offering a comprehensive suite of AI capabilities including chat models, embedding models, and image generation.
## Features
Access to QianFan's conversational AI models for building intelligent chatbots and assistants
Generate text embeddings for semantic search and text similarity analysis
Create AI-generated images using QianFan's CogView model
## Requirements
* Java 17 or later
* Maven 3.6+
* QianFan API credentials (API Key and Secret Key)
## Quick Start
### Add Dependency
```xml theme={null}
org.springframework.ai
spring-ai-qianfan
1.0.0-SNAPSHOT
```
```groovy theme={null}
dependencies {
implementation 'org.springframework.ai:spring-ai-qianfan:1.0.0-SNAPSHOT'
}
```
### Configuration
Set your QianFan credentials via environment variables:
```bash theme={null}
export SPRING_AI_QIANFAN_API_KEY=
export SPRING_AI_QIANFAN_SECRET_KEY=
```
Or configure in `application.properties`:
```properties theme={null}
spring.ai.qianfan.api-key=YOUR_API_KEY
spring.ai.qianfan.secret-key=YOUR_SECRET_KEY
```
## Building from Source
```bash theme={null}
# Using Maven
mvn clean install
# Using Maven wrapper
./mvnw clean install
```
### Building Documentation
To build the documentation site:
```bash theme={null}
./mvnw -pl docs antora
```
This will generate the documentation site in `/docs/target/antora/site`.
## Resources
View source code and contribute
Full documentation (will be published to GitHub Pages)
## License
This project is licensed under the Apache License 2.0 - see the [LICENSE](https://github.com/spring-ai-community/qianfan/blob/main/LICENSE) file for details.
# Agent Bench
Source: https://springaicommunity.mintlify.app/projects/incubating/agent-bench
Benchmarking framework for AI coding agents on enterprise Java tasks
This project has moved to [markpollack/agent-bench](https://github.com/markpollack/agent-bench).
Current documentation is at [lab.pollack.ai/projects/agent-bench](https://lab.pollack.ai/projects/agent-bench).
The content below may be outdated.
![]() [GitHub](https://github.com/spring-ai-community/agent-bench) • [Agent Judge](https://github.com/spring-ai-community/agent-judge) • [Agent Client](https://github.com/spring-ai-community/agent-client)
## Overview
Agent Bench defines benchmarks as YAML, launches any CLI agent in an isolated workspace, and grades results with cascaded judge tiers from [Agent Judge](https://github.com/spring-ai-community/agent-judge).
The filesystem is the contract. The bench writes `INSTRUCTION.md` to the workspace. The agent reads it and modifies files. Any CLI tool — Claude Code, Gemini CLI, Amazon Q, a shell script — can compete.
## How It Works
```
provide → setup scripts → agent → post scripts → grade → result.json
```
1. **Provide** copies the workspace template and writes `INSTRUCTION.md`
2. **Setup** scripts prepare the workspace (clone repo, compile, measure baseline)
3. **Agent** runs — any command that reads `INSTRUCTION.md` and modifies files
4. **Post** scripts finalize (run tests, generate coverage reports)
5. **Grade** evaluates with a cascaded jury
## Benchmark Format
```
benchmarks/code-coverage/
├── benchmark.yaml # jury config: cascaded judge tiers
├── prompts/ # judge prompts
└── tasks/
└── spring-petclinic/
└── task.yaml # instruction, setup/post scripts, metadata
```
### benchmark.yaml — Jury Configuration
```yaml theme={null}
schema: bench.benchmark.v1
name: code-coverage
version: "1.0"
default-timeout: PT45M
jury:
tiers:
- name: build
policy: REJECT_ON_ANY_FAIL
checks:
- type: maven-build
goals: [clean, test]
- name: coverage-improvement
policy: ACCEPT_ON_ALL_PASS
checks:
- type: coverage-improvement
min: 50.0
```
### task.yaml — Task Definition
```yaml theme={null}
schema: bench.task.v1
id: spring-petclinic
instruction: |
Write JUnit tests for this Spring Boot project to maximize code coverage.
Use narrow test slices (@WebMvcTest, @DataJpaTest) over @SpringBootTest.
timeout: PT45M
metadata:
baselineCoverage: 0.0
setup:
- "git init && git remote add origin ... && git fetch --depth 1 origin edf4db28affc && git checkout FETCH_HEAD"
- "./mvnw clean compile -q"
post:
- "./mvnw clean test jacoco:report -q"
```
### Agent Config
Agents are defined by a command and a timeout:
```yaml theme={null}
# agents/claude-code.yaml
command: claude --print --dangerously-skip-permissions 'Read INSTRUCTION.md and follow the instructions precisely.'
timeout: PT45M
```
## CLI
| Command | Purpose |
| ---------------------------------------------------------------- | ------------------------- |
| `bench list` | List available benchmarks |
| `bench tasks --benchmark ` | List tasks in a benchmark |
| `bench provide --benchmark --task --workspace ` | Set up workspace |
| `bench grade --benchmark --task --workspace ` | Evaluate agent's work |
| `bench run --benchmark --agent ` | Full pipeline |
## Bring Your Own Agent
```bash theme={null}
# 1. Set up workspace
bench provide --benchmark code-coverage --task spring-petclinic --workspace /tmp/petclinic
# 2. Run any agent
cd /tmp/petclinic && your-agent "$(cat INSTRUCTION.md)"
# 3. Grade
bench grade --benchmark code-coverage --task spring-petclinic --workspace /tmp/petclinic
```
## Built-in Judge Types
| Type | What it checks |
| ----------------------- | ----------------------------------------- |
| `file-exists` | File exists at path |
| `file-content` | File content matches expected |
| `maven-build` | Maven build succeeds |
| `coverage-preservation` | JaCoCo coverage not dropped from baseline |
| `coverage-improvement` | JaCoCo coverage exceeds threshold |
Custom types registered via `JudgeFactory.register()`.
## Benchmarks
| Benchmark | Tasks | Description |
| --------------- | -------------------- | ----------------------------------------------------------------------------------- |
| `hello-world` | 1 | Smoke test for validating the harness — submit your own agent to verify it works |
| `code-coverage` | 1 (spring-petclinic) | Write JUnit tests from scratch to maximize JaCoCo coverage, graded by a 4-tier jury |
The code-coverage benchmark was validated in a [29-run experiment](https://github.com/markpollack/experiment-code-coverage-v2) testing 7 prompt/knowledge variants with Claude Sonnet 4.6 on spring-petclinic. See the [blog post](https://blog.pollack.ai/i-read-my-agents-diary/) for analysis.
## Architecture
Two modules: `agent-bench-core` (CLI, catalog, judge factory, result model) and `agent-bench-agents` (LLM-based judges). Module layering enforced by ArchUnit.
## Resources
Source code and benchmarks
Cascaded judge framework (core dependency)
29-run benchmark study with variant analysis
Analysis of the code-coverage experiment results
## License
Apache License 2.0
# Agent Client
Source: https://springaicommunity.mintlify.app/projects/incubating/agent-client
Portable Java API for autonomous CLI agents — Claude Code, Codex, Gemini, Amazon Q, and Amp
This project has moved to [markpollack/agent-client](https://github.com/markpollack/agent-client).
Current documentation is at [lab.pollack.ai/projects/agent-client](https://lab.pollack.ai/projects/agent-client).
The content below may be outdated.
![Incubating Status]() [GitHub](https://github.com/spring-ai-community/agent-client) • [Maven Central](https://central.sonatype.com/search?q=g:org.springaicommunity.agents) • [Tutorial](https://github.com/spring-ai-community/agent-client-tutorial)
**Version 0.16.0** — Available on [Maven Central](https://central.sonatype.com/search?q=g:org.springaicommunity.agents)
## What's New in 0.16.0
* **Framework-independent core** — `agent-client-core` has zero Spring Boot dependencies. Use from plain Java, Quarkus, or Micronaut.
* **`AgentApi` replaces `AgentModel`** — new name reflects that implementations wrap CLI runtimes, not AI models. `AgentModel` is deprecated with a shim.
* **New property prefix `agent-client.*`** — replaces `spring.ai.agents.*` to properly distance from Spring AI namespace. Example: `agent-client.claude.model` instead of `spring.ai.agents.claude-code.model`.
* **LOOSE mode sandbox bypass** — Codex LOOSE now derives `dangerouslyBypassSandbox=true`, fixing bwrap sandbox failures.
* **Codex model default** — updated to `gpt-5.4-mini` (replaces retired `gpt-5-codex`).
* **Gemini working directory fix** — request working directory now properly propagated to CLI process.
### Previous (0.15.0)
* **AgentClientMode** (LOOSE/STRICT) — portable enum controlling default permissiveness.
* **Provider Parity TCK** — `@ProviderCapability` annotation with JUnit Assumptions.
* **Reference documentation** — complete configuration reference for all providers.
* **Tutorial repository** — progressive examples at [agent-client-tutorial](https://github.com/spring-ai-community/agent-client-tutorial).
## Overview
**What ChatClient did for completion endpoints, AgentClient does for agent CLIs.**
Agent Client provides a portable Java API for autonomous CLI agents. Build a model, create a client, run a goal — provider selection happens at construction time, everything after is portable.
```java theme={null}
// Provider-specific: build the model
ClaudeAgentModel model = ClaudeAgentModel.builder()
.defaultOptions(ClaudeAgentOptions.builder()
.model("claude-sonnet-4-5")
.yolo(true)
.build())
.build();
// Portable: works with any provider
AgentClient client = AgentClient.create(model);
AgentClientResponse response = client.run("Create hello.txt with 'Hello!'");
```
No Spring Boot required. Optional Spring Boot starters provide auto-configuration for those who want it.
## Supported Providers
Anthropic's autonomous coding agent — 18 configuration options
OpenAI's code generation agent — LOOSE mode for frictionless setup
Google's Gemini models via CLI
AWS developer assistant (beta)
Sourcegraph's AI coding assistant (beta)
Implement `AgentModel` for any CLI agent
## Documentation
Plain Java quick start — create your first agent task
Step-by-step lessons from first task to multi-provider
Configuration options, precedence rules, mode system
Run the same task with different providers using Maven profiles
## Key Features
`AgentClient.create(model)` works with any provider. Switch by swapping the model.
Control default permissiveness. LOOSE works anywhere, STRICT requires opt-in.
Persistent multi-turn conversations with session lifecycle management.
Define MCP servers once, run on any provider. Client resolves, model translates.
Interception points for context engineering, evaluation, security, and observability.
Optional auto-configuration with `agent-starter-claude`, `agent-starter-codex`, etc.
## Quick Start
```xml theme={null}
org.springaicommunity.agents
agent-claude
0.15.0
```
```java theme={null}
ClaudeAgentModel model = ClaudeAgentModel.builder()
.defaultOptions(ClaudeAgentOptions.builder()
.model("claude-sonnet-4-5")
.yolo(true)
.build())
.build();
AgentClient client = AgentClient.create(model);
AgentClientResponse response = client.run("Fix the failing test in UserServiceTest");
```
See the [Getting Started](/agent-client/howto/getting-started) guide for all three providers and the Spring Boot path.
## Portable MCP Servers
Define MCP servers once in a portable format. Agent Client translates to each provider's native configuration at execution time.
```java theme={null}
McpServerCatalog catalog = McpServerCatalog.fromJson(Path.of("mcp-servers.json"));
AgentClient client = AgentClient.builder(model)
.mcpServerCatalog(catalog)
.defaultMcpServers("weather")
.build();
// Per-request MCP server selection
client.goal("Research recent Spring AI releases")
.mcpServers("brave-search")
.run();
```
| Provider | Native mechanism |
| -------- | ------------------------------------------------------------ |
| Claude | `--mcp-config ` — temporary JSON config file |
| Gemini | `.gemini/settings.json` — settings file in working directory |
## Agent Advisors
The same advisor pattern as Spring AI's ChatClient — powerful interception for context engineering, evaluation, and security:
```java theme={null}
AgentClient client = AgentClient.builder(model)
.defaultAdvisor(new WorkspaceContextAdvisor())
.defaultAdvisor(JudgeAdvisor.builder().judge(coverageJudge).build())
.build();
```
## Related Projects
Standalone evaluation framework — Judge, Jury, and Score APIs
Isolated execution — Local, Docker, and E2B backends
Low-level Java SDK for Claude Code CLI
Benchmarking framework for agent evaluation
## License
Apache 2.0 — [View on GitHub](https://github.com/spring-ai-community/agent-client/blob/main/LICENSE)
# Agent Judge
Source: https://springaicommunity.mintlify.app/projects/incubating/agent-judge
Agent-agnostic evaluation framework with deterministic, command, and LLM judges
This project has moved to [markpollack/agent-judge](https://github.com/markpollack/agent-judge).
Current documentation is at [lab.pollack.ai/projects/agent-judge](https://lab.pollack.ai/projects/agent-judge).
The content below may be outdated.
![Incubating Status]() [GitHub](https://github.com/spring-ai-community/agent-judge) • [Maven Central](https://central.sonatype.com/search?q=org.springaicommunity.judge)
## Overview
Agent Judge is an **agent-agnostic evaluation framework** for verifying AI agent task completion. It provides a pluggable architecture with deterministic rules, command execution, and LLM-powered evaluation - all with zero coupling to any specific agent implementation.
The library follows a clean separation of concerns: `agent-judge-core` has zero external dependencies, while specialized modules add capabilities like process execution (`agent-judge-exec`) and LLM evaluation (`agent-judge-llm`).
## Core Abstractions
Functional interface for evaluation logic - takes JudgmentContext, returns Judgment
Result containing Score, JudgmentStatus, reasoning, and granular Checks
Sealed interface: BooleanScore, NumericalScore, or CategoricalScore
Multi-judge aggregation with configurable voting strategies
## Module Structure
| Module | Description | Dependencies |
| --------------------- | ------------------------------- | ---------------------- |
| `agent-judge-core` | Core Judge API and abstractions | None (zero deps) |
| `agent-judge-exec` | Command execution judges | agent-sandbox, zt-exec |
| `agent-judge-llm` | LLM-powered evaluation | spring-ai-client-chat |
| `agent-judge-agent` | Agent-as-judge bridge interface | Core only |
| `agent-judge-advisor` | AgentClient advisors | spring-ai-agent-client |
| `agent-judge-bom` | Bill of Materials | N/A |
## Quick Start
### Maven BOM
```xml theme={null}
org.springaicommunity.judge
agent-judge-bom
0.9.1
pom
import
org.springaicommunity.judge
agent-judge-core
```
## Judge Interface
The core `Judge` interface is a functional interface for lambda support:
```java theme={null}
@FunctionalInterface
public interface Judge {
Judgment judge(JudgmentContext context);
}
```
**Async and Reactive Variants:**
```java theme={null}
// For CompletableFuture-based async
public interface AsyncJudge {
CompletableFuture judgeAsync(JudgmentContext context);
}
// For Spring WebFlux / Project Reactor
public interface ReactiveJudge {
Mono judge(JudgmentContext context);
}
```
## Judgment Context
Complete evaluation input with all context an agent execution:
```java theme={null}
JudgmentContext context = JudgmentContext.builder()
.goal("Increase test coverage to 80%")
.workspace(Path.of("/project"))
.executionTime(Duration.ofMinutes(5))
.startedAt(Instant.now())
.agentOutput("Added 15 test cases...")
.status(ExecutionStatus.SUCCESS)
.build();
```
**ExecutionStatus values:** `SUCCESS`, `FAILED`, `TIMEOUT`, `CANCELLED`, `UNKNOWN`
## Judgment Results
```java theme={null}
Judgment result = judge.judge(context);
// Result properties
Score score = result.score(); // BooleanScore, NumericalScore, or CategoricalScore
JudgmentStatus status = result.status(); // PASS, FAIL, ABSTAIN, or ERROR
String reasoning = result.reasoning(); // Human-readable explanation
List checks = result.checks(); // Granular sub-assertions
```
**JudgmentStatus values:** `PASS`, `FAIL`, `ABSTAIN`, `ERROR`
### Checks (Sub-Assertions)
Provide granular failure reporting:
```java theme={null}
Judgment.builder()
.score(BooleanScore.FAIL)
.status(JudgmentStatus.FAIL)
.reasoning("2 of 3 checks failed")
.check(Check.passed("file-exists", "output.txt exists"))
.check(Check.failed("content-valid", "Missing required header"))
.check(Check.failed("format-correct", "Invalid JSON structure"))
.build();
```
## Score Types
Simple pass/fail scoring:
```java theme={null}
BooleanScore.PASS // true
BooleanScore.FAIL // false
```
Continuous scoring with bounds and normalization:
```java theme={null}
// Score with min/max bounds
NumericalScore score = NumericalScore.of(85.0, 0.0, 100.0);
// Auto-normalizes to [0.0, 1.0]
double normalized = score.normalized(); // 0.85
```
Discrete categories from an allowed set:
```java theme={null}
CategoricalScore score = CategoricalScore.of(
"GOOD",
Set.of("EXCELLENT", "GOOD", "FAIR", "POOR")
);
```
The `Scores` utility class converts between score types for heterogeneous aggregation.
## Built-in Judges
### Deterministic Judges (agent-judge-core)
Verifies file existence:
```java theme={null}
FileExistsJudge judge = FileExistsJudge.of("target/output.txt");
Judgment result = judge.judge(context);
```
Verifies file content with match modes:
```java theme={null}
// Exact match
FileContentJudge.exact("config.json", expectedContent);
// Contains substring
FileContentJudge.contains("output.log", "BUILD SUCCESS");
// Regex pattern
FileContentJudge.regex("version.txt", "\\d+\\.\\d+\\.\\d+");
```
Build rule-based judges:
```java theme={null}
DeterministicJudge judge = DeterministicJudge.builder()
.name("config-valid")
.check(ctx -> validateConfig(ctx.workspace()))
.build();
```
### Command Judges (agent-judge-exec)
Execute shell commands and evaluate results:
```java theme={null}
CommandJudge judge = CommandJudge.builder()
.name("maven-tests")
.command("mvn", "test", "-q")
.expectedExitCode(0)
.timeout(Duration.ofMinutes(5))
.build();
```
Specialized for build tools with wrapper auto-detection:
```java theme={null}
// Maven - auto-detects mvnw wrapper
BuildSuccessJudge maven = BuildSuccessJudge.maven("clean", "verify");
// Gradle - auto-detects gradlew wrapper
BuildSuccessJudge gradle = BuildSuccessJudge.gradle("build", "test");
```
Default timeout: 10 minutes.
### LLM Judges (agent-judge-llm)
Uses LLM to evaluate if the agent accomplished its goal:
```java theme={null}
CorrectnessJudge judge = CorrectnessJudge.builder()
.chatClient(chatClient)
.build();
// Returns YES/NO with reasoning
Judgment result = judge.judge(context);
```
Uses template method pattern for customization.
Build custom LLM-powered evaluation:
```java theme={null}
LLMJudge judge = new LLMJudge(chatClient) {
@Override
protected String buildPrompt(JudgmentContext ctx) {
return "Evaluate code quality for: " + ctx.goal();
}
@Override
protected Judgment parseResponse(String response, JudgmentContext ctx) {
// Parse LLM response into Judgment
}
};
```
### Agent Judges (agent-judge-agent)
Delegate evaluation to an AI agent using a bridge interface:
```java theme={null}
public interface JudgeAgentClient {
JudgeAgentResponse execute(String goal, Path workspace);
}
// Adapt any agent client without hard dependencies
JudgeAgentClient adapter = (goal, workspace) ->
myAgentClient.run(goal, workspace);
```
## Judge Composition
The `Judges` utility class provides composition operators:
```java theme={null}
// Logical AND (short-circuit)
Judge combined = Judges.and(fileExistsJudge, contentValidJudge);
// Logical OR (short-circuit)
Judge either = Judges.or(primaryJudge, fallbackJudge);
// Combine multiple judges
Judge all = Judges.allOf(judge1, judge2, judge3);
Judge any = Judges.anyOf(judge1, judge2, judge3);
// Test judges
Judge pass = Judges.alwaysPass("Skipped in test mode");
Judge fail = Judges.alwaysFail("Feature not implemented");
// Add metadata to any judge
Judge named = Judges.named(myJudge, "my-judge", "Description", JudgeType.DETERMINISTIC);
```
## Jury System
Combine multiple judges with voting strategies:
```java theme={null}
SimpleJury jury = SimpleJury.builder()
.name("comprehensive-check")
.judge(fileJudge)
.judge(testJudge, 2.0) // Weight of 2.0
.judge(codeQualityJudge)
.votingStrategy(VotingStrategy.majority())
.parallel(true) // Execute judges in parallel (default)
.build();
Verdict verdict = jury.vote(context);
// Access results
Judgment aggregated = verdict.aggregated();
List individual = verdict.individual();
Map byName = verdict.individualByName();
Map weights = verdict.weights();
```
### Voting Strategies
| Strategy | Description | Pass Condition |
| ------------------------- | ----------------------- | --------------------- |
| `MajorityVotingStrategy` | Majority vote | passCount > failCount |
| `ConsensusStrategy` | Unanimous agreement | All judges agree |
| `AverageVotingStrategy` | Simple average | average >= 0.5 |
| `WeightedAverageStrategy` | Weighted average | weighted avg >= 0.5 |
| `MedianVotingStrategy` | Median (outlier-robust) | median >= 0.5 |
**Majority Voting Policies:**
```java theme={null}
MajorityVotingStrategy.builder()
.tiePolicy(TiePolicy.FAIL) // PASS, FAIL, or ABSTAIN on ties
.errorPolicy(ErrorPolicy.TREAT_AS_FAIL) // How to handle ERROR judgments
.build();
```
### Jury Utilities
```java theme={null}
// Create jury from judges with auto-naming
Jury jury = Juries.fromJudges(VotingStrategy.majority(), judge1, judge2, judge3);
// Combine juries into meta-jury
Jury metaJury = Juries.combine(jury1, jury2, VotingStrategy.consensus());
// Create meta-jury from multiple juries
Jury combined = Juries.allOf(VotingStrategy.average(), jury1, jury2, jury3);
```
## Utilities
### MavenTestRunner
Run Maven tests with wrapper auto-detection:
```java theme={null}
ExecResult result = MavenTestRunner.run(projectPath, Duration.ofMinutes(10));
if (result.exitCode() == 0) {
// Tests passed
}
```
### JaCoCoReportParser
Parse JaCoCo XML reports for coverage metrics:
```java theme={null}
CoverageMetrics metrics = JaCoCoReportParser.parse(
projectPath.resolve("target/site/jacoco/jacoco.xml")
);
double lineCoverage = metrics.linePercentage(); // e.g., 85.5
double branchCoverage = metrics.branchPercentage(); // e.g., 72.3
double methodCoverage = metrics.methodPercentage(); // e.g., 90.1
```
## Spring AI Agents Integration
Agent Judge powers the evaluation system in [Agent Client](/projects/incubating/agent-client):
```java theme={null}
CoverageJudge judge = new CoverageJudge(80.0);
AgentClientResponse response = agentClient
.goal("Increase test coverage to 80%")
.advisors(JudgeAdvisor.builder().judge(judge).build())
.run();
```
## Resources
Source code and contribution guidelines
Published artifacts
## License
Agent Judge is Open Source software released under the [Apache 2.0 license](https://github.com/spring-ai-community/agent-judge/blob/main/LICENSE).
# Agent Sandbox
Source: https://springaicommunity.mintlify.app/projects/incubating/agent-sandbox
Isolated command execution API - Local, Docker, and E2B cloud backends
This project has moved to [markpollack/agent-sandbox](https://github.com/markpollack/agent-sandbox).
Current documentation is at [lab.pollack.ai/projects/agent-sandbox](https://lab.pollack.ai/projects/agent-sandbox).
The content below may be outdated.
![Incubating Status]() [GitHub](https://github.com/spring-ai-community/agent-sandbox) • [Maven Central](https://central.sonatype.com/search?q=org.springaicommunity.sandbox)
## Overview
Agent Sandbox provides a **unified API for isolated command execution** across multiple backends. Whether you need local process isolation, Docker container security, or cloud-based E2B microVMs, the same interface works everywhere.
The library emphasizes clean design: interface segregation (separate concerns for execution vs file operations), Liskov substitution (backends are interchangeable), and a JDK 21 baseline for modern Java features.
## Core API
Main interface for isolated command execution with workspace management
Command specification with timeout, environment, and shell support
Execution result with exit code, stdout, stderr, and utilities
Fluent API for file operations within the sandbox workspace
## Module Structure
| Module | Description | Dependencies |
| ---------------------- | --------------------------------- | ------------------- |
| `agent-sandbox-core` | Core Sandbox API and LocalSandbox | zt-exec |
| `agent-sandbox-docker` | Docker container sandbox | testcontainers |
| `agent-sandbox-e2b` | E2B cloud microVM sandbox | jackson, awaitility |
| `agent-sandbox-bom` | Bill of Materials | N/A |
## Implementations
Local process execution using zt-exec. Fast, no isolation overhead.
Container-based isolation using Testcontainers. Full filesystem/network isolation.
Cloud microVM execution via E2B. Maximum isolation with MCP support.
## Quick Start
### Maven Dependency
```xml theme={null}
org.springaicommunity.sandbox
agent-sandbox-core
0.9.1
```
### Basic Execution
```java theme={null}
try (Sandbox sandbox = LocalSandbox.builder()
.tempDirectory("test-")
.build()) {
ExecResult result = sandbox.exec(ExecSpec.of("echo", "Hello"));
if (result.success()) {
System.out.println(result.stdout()); // "Hello"
}
}
```
## Sandbox Interface
```java theme={null}
public interface Sandbox extends AutoCloseable {
ExecResult exec(ExecSpec spec); // Execute command
Process startInteractive(ExecSpec spec); // Start interactive process
Path workDir(); // Get working directory
SandboxFiles files(); // Access file operations
boolean isClosed(); // Check if closed
boolean shouldCleanupOnClose(); // Auto-delete on close?
}
```
## ExecSpec (Command Specification)
Build command specifications with fluent API:
```java theme={null}
// Simple command
ExecSpec spec = ExecSpec.of("mvn", "test");
// Full builder
ExecSpec spec = ExecSpec.builder()
.command("java", "-jar", "app.jar")
.env("JAVA_OPTS", "-Xmx512m")
.env("DEBUG", "true")
.timeout(Duration.ofMinutes(5))
.build();
// Shell command (platform-aware: bash -c on Unix, cmd /c on Windows)
ExecSpec spec = ExecSpec.builder()
.shellCommand("echo $HOME && ls -la")
.timeout(Duration.ofSeconds(30))
.build();
// Modify existing spec
ExecSpec modified = spec.toBuilder()
.timeout(Duration.ofMinutes(10))
.build();
```
## ExecResult (Execution Result)
Rich result object with utilities for AI analysis:
```java theme={null}
ExecResult result = sandbox.exec(spec);
// Basic properties
int exitCode = result.exitCode();
String stdout = result.stdout();
String stderr = result.stderr();
Duration duration = result.duration();
// Convenience methods
boolean ok = result.success(); // exitCode == 0
boolean failed = result.failed(); // exitCode != 0
// Output utilities
String merged = result.mergedLog(); // stdout + stderr (for LLM analysis)
boolean hasOut = result.hasOutput(); // stdout or stderr non-empty
boolean hasStdout = result.hasStdout();
boolean hasStderr = result.hasStderr();
int length = result.outputLength(); // Combined length
// Logging-friendly summary (no full output)
String summary = result.summary(); // "ExecResult[exitCode=0, duration=PT1.234S]"
```
## SandboxFiles (File Operations)
Fluent API for file management with `.and()` to chain back to sandbox:
```java theme={null}
try (Sandbox sandbox = LocalSandbox.create()) {
// Create files and directories
sandbox.files()
.create("pom.xml", pomContent)
.create("src/main/java/App.java", sourceCode)
.createDirectory("target")
.and() // Return to Sandbox
.exec(ExecSpec.of("mvn", "compile"));
// Read files
String content = sandbox.files().read("target/output.txt");
// Check existence
boolean exists = sandbox.files().exists("target/classes/App.class");
// Delete files
sandbox.files()
.delete("target/temp.txt")
.delete("target/generated", true); // recursive
// List directory contents
List entries = sandbox.files().list("src");
List deep = sandbox.files().list("src", 3); // maxDepth=3
}
```
### Batch File Setup
```java theme={null}
List files = List.of(
FileSpec.of("pom.xml", pomContent),
FileSpec.of("src/main/java/App.java", code),
FileSpec.of("README.md", docs)
);
sandbox.files().setup(files);
```
### FileEntry (File Metadata)
```java theme={null}
List entries = sandbox.files().list("src");
for (FileEntry entry : entries) {
String name = entry.name(); // Filename
String path = entry.path(); // Relative path
FileType type = entry.type(); // FILE or DIRECTORY
long size = entry.size(); // Bytes (0 for dirs)
Instant modified = entry.modifiedTime(); // Last modified
if (entry.isFile()) {
String content = sandbox.files().read(entry.path());
}
}
```
## ExecSpecCustomizer
Inject cross-cutting concerns (auth, logging, etc.) before every execution:
```java theme={null}
// Add authentication to all commands
ExecSpecCustomizer addAuth = spec -> spec.toBuilder()
.env("AUTH_TOKEN", System.getenv("TOKEN"))
.build();
// Conditional customization
ExecSpecCustomizer debugMode = ExecSpecCustomizer.when(
spec -> spec.command().contains("test"),
spec -> spec.toBuilder().env("DEBUG", "true").build()
);
// Chain multiple customizers
ExecSpecCustomizer combined = ExecSpecCustomizer.chain(addAuth, debugMode);
// Apply to sandbox
LocalSandbox sandbox = LocalSandbox.builder()
.customizer(combined)
.build();
```
## LocalSandbox
Fast local execution without container overhead:
```java theme={null}
// Use current directory
try (Sandbox sandbox = LocalSandbox.create()) {
sandbox.exec(ExecSpec.of("ls", "-la"));
}
// Use specific directory
try (Sandbox sandbox = new LocalSandbox(Path.of("/project"))) {
sandbox.exec(ExecSpec.of("mvn", "test"));
}
// Builder with temp directory (auto-cleanup)
try (Sandbox sandbox = LocalSandbox.builder()
.tempDirectory("myapp-")
.withFile("config.json", configContent)
.withFiles(List.of(
FileSpec.of("src/App.java", code),
FileSpec.of("pom.xml", pom)
))
.customizer(myCustomizer)
.build()) {
sandbox.exec(ExecSpec.of("mvn", "compile"));
}
// Temp directory deleted on close
```
### Interactive Processes
For bidirectional I/O (stdin/stdout streaming):
```java theme={null}
Process proc = sandbox.startInteractive(ExecSpec.of("bash"));
try {
proc.getOutputStream().write("echo hello\n".getBytes());
proc.getOutputStream().flush();
// Read from proc.getInputStream()
} finally {
proc.destroy();
}
```
## DockerSandbox
Container isolation for untrusted code:
```java theme={null}
// Default image
try (Sandbox sandbox = DockerSandbox.create()) {
sandbox.exec(ExecSpec.of("python", "--version"));
}
// Custom image
try (Sandbox sandbox = DockerSandbox.builder()
.image("maven:3.9-eclipse-temurin-21")
.withFile("pom.xml", pomContent)
.customizer(myCustomizer)
.build()) {
ExecResult result = sandbox.exec(ExecSpec.of("mvn", "test"));
}
```
Default image: `ghcr.io/spring-ai-community/agents-runtime:latest`
Working directory: `/work`
## E2BSandbox
Cloud-based Firecracker microVM for maximum isolation:
```java theme={null}
// Basic usage (uses E2B_API_KEY env var)
try (Sandbox sandbox = E2BSandbox.builder()
.template("base")
.timeout(Duration.ofMinutes(2))
.build()) {
ExecResult result = sandbox.exec(ExecSpec.of("python", "script.py"));
}
// Full configuration
try (Sandbox sandbox = E2BSandbox.builder("your-api-key")
.template("python-3.11")
.timeout(Duration.ofMinutes(5))
.env("API_KEY", "secret") // Sandbox-level env
.env(Map.of("DEBUG", "true"))
.withFile("script.py", code)
.build()) {
sandbox.exec(ExecSpec.of("python", "script.py"));
}
```
Working directory: `/home/user`
### Session Reconnection
Reconnect to existing E2B sandbox for persistent sessions:
```java theme={null}
// Create and get sandbox ID
E2BSandbox sandbox = E2BSandbox.builder().build();
String sandboxId = sandbox.getSandboxId();
sandbox.close();
// Later: reconnect to same sandbox
try (Sandbox reconnected = E2BSandbox.connect(sandboxId)) {
// Files and state preserved
reconnected.exec(ExecSpec.of("ls", "-la"));
}
```
E2B sandboxes support MCP (Model Context Protocol) for AI agent integration. See the [E2B documentation](https://e2b.dev/docs) for details.
## Exceptions
```java theme={null}
try {
sandbox.exec(ExecSpec.builder()
.command("long-running-task")
.timeout(Duration.ofSeconds(5))
.build());
} catch (TimeoutException e) {
Duration timeout = e.getTimeout(); // The timeout that was exceeded
// Handle timeout
} catch (SandboxException e) {
// General sandbox errors (I/O, process failures, etc.)
}
```
## Design Principles
The `Sandbox` interface focuses on command execution, while `SandboxFiles` handles file operations. This separation allows implementations to optimize each concern independently.
```java theme={null}
// Execution
ExecResult result = sandbox.exec(spec);
// File operations via accessor
sandbox.files().create("test.txt", content);
```
All sandbox implementations are interchangeable. Code written for `LocalSandbox` works identically with `DockerSandbox` or `E2BSandbox`:
```java theme={null}
void runTests(Sandbox sandbox) {
// Works with any implementation
ExecResult result = sandbox.exec(ExecSpec.of("mvn", "test"));
}
// Choose isolation level at runtime
Sandbox sandbox = requiresIsolation
? DockerSandbox.create()
: LocalSandbox.create();
```
Built for modern Java with:
* Virtual threads for concurrent operations
* Pattern matching and sealed classes
* Modern NIO file APIs
* Try-with-resources for automatic cleanup
## Used By
Agent Sandbox is used by:
* **[Agent Judge](/projects/incubating/agent-judge)** - The `agent-judge-exec` module uses sandboxes for command-based evaluation
* **[Agent Client](/projects/incubating/agent-client)** - Provides isolated execution environments for autonomous agents
## Resources
Source code and contribution guidelines
E2B cloud sandbox platform
## License
Agent Sandbox is Open Source software released under the [Apache 2.0 license](https://github.com/spring-ai-community/agent-sandbox/blob/main/LICENSE).
# GitHub Collector
Source: https://springaicommunity.mintlify.app/projects/incubating/github-collector
Collect GitHub issues, PRs, and releases for research and analysis
This project has moved to [markpollack/github-collector](https://github.com/markpollack/github-collector).
The content below may be outdated.
![]() [GitHub](https://github.com/markpollack/github-collector)
## Overview
GitHub Collector is a command-line tool for collecting GitHub repository data — issues, pull requests, releases, and collaborators. It outputs structured JSON files suitable for analysis in Python, R, or any data processing tool.
Designed for researchers who need to mine software repositories without dealing with GitHub API pagination, rate limits, or JSON parsing.
## Quick Start
No Java installation required. JBang handles everything.
### 1. Install JBang
```bash theme={null}
curl -s "https://get.sdkman.io" | bash
source "$HOME/.sdkman/bin/sdkman-init.sh"
sdk install jbang
```
```bash theme={null}
brew install jbang
```
```powershell theme={null}
iex "& { $(iwr -useb https://ps.jbang.dev) } app setup"
```
```bash theme={null}
curl -Ls https://sh.jbang.dev | bash -s - app setup
```
### 2. Set your GitHub token
Create a [personal access token](https://github.com/settings/tokens) with `repo` scope.
```bash theme={null}
export GITHUB_TOKEN=ghp_your_token_here
```
### 3. Collect data
```bash theme={null}
jbang collect@spring-ai-community/github-collector --repo spring-projects/spring-ai --type issues
```
Output appears in `issues/raw/open/spring-projects/spring-ai/`:
```
batch_001_issues.json
batch_002_issues.json
...
```
## Common Use Cases
### Collect all closed issues
```bash theme={null}
jbang collect@spring-ai-community/github-collector \
--repo owner/repo \
--type issues \
--state closed
```
### Collect merged PRs
```bash theme={null}
jbang collect@spring-ai-community/github-collector \
--repo owner/repo \
--type prs \
--pr-state merged
```
### Collect issues from a date range
```bash theme={null}
jbang collect@spring-ai-community/github-collector \
--repo owner/repo \
--type issues \
--state all \
--created-after 2024-01-01 \
--created-before 2025-01-01
```
### Collect releases
```bash theme={null}
jbang collect@spring-ai-community/github-collector \
--repo owner/repo \
--type releases
```
### Collect repository collaborators
```bash theme={null}
jbang collect@spring-ai-community/github-collector \
--repo owner/repo \
--type collaborators
```
### Verify and deduplicate batch files
If you collected data in multiple runs, duplicates may exist across batches:
```bash theme={null}
# Check for problems
jbang collect@spring-ai-community/github-collector \
--type issues \
--verify \
--verify-dir path/to/batch/files
# Fix duplicates automatically
jbang collect@spring-ai-community/github-collector \
--type issues \
--deduplicate \
--verify-dir path/to/batch/files
```
## Output Format
Each batch file contains a metadata header and an array of items:
```json theme={null}
{
"metadata": {
"batch_index": 1,
"item_count": 100,
"collection_type": "issues",
"repository": "owner/repo",
"state": "open",
"timestamp": "2026-02-04T15:30:45"
},
"issues": [
{
"number": 123,
"title": "Bug in feature X",
"body": "Description...",
"state": "OPEN",
"created_at": "2025-06-15T10:30:00",
"updated_at": "2025-06-16T14:22:00",
"closed_at": null,
"url": "https://github.com/owner/repo/issues/123",
"author": { "login": "username" },
"labels": [
{ "name": "bug", "color": "d73a4a" }
],
"assignees": [],
"comments_count": 5,
"label_events": [
{
"event": "labeled",
"label": "bug",
"actor": "maintainer",
"created_at": "2025-06-15T11:00:00"
}
]
}
]
}
```
### Loading in Python
```python theme={null}
import json
from pathlib import Path
def load_batches(directory):
"""Load all batch files from a directory."""
items = []
for batch_file in sorted(Path(directory).glob("batch_*.json")):
with open(batch_file) as f:
data = json.load(f)
# Get the collection type (issues, prs, releases, etc.)
for key in data:
if key != "metadata" and isinstance(data[key], list):
items.extend(data[key])
return items
issues = load_batches("issues/raw/closed/spring-projects/spring-ai")
print(f"Loaded {len(issues)} issues")
```
## CLI Reference
```
Usage: jbang collect@spring-ai-community/github-collector [OPTIONS]
REQUIRED:
-r, --repo REPO Repository in format owner/repo
COLLECTION TYPE:
-t, --type TYPE issues, prs, releases, collaborators (default: issues)
-s, --state STATE Issue state: open, closed, all (default: open)
--pr-state STATE PR state: open, closed, merged, all (default: open)
DATE FILTERING:
--created-after DATE Items created on or after DATE (YYYY-MM-DD)
--created-before DATE Items created before DATE (YYYY-MM-DD)
OUTPUT:
-b, --batch-size SIZE Items per batch file (default: 100)
--single-file Output all items to one file instead of batches
-o, --output FILE Output file path (with --single-file)
VERIFICATION:
--verify Check batch files for duplicates and issues
--deduplicate Remove duplicates from batch files
--verify-dir DIR Directory containing batch files to verify
OTHER:
-d, --dry-run Show what would be collected without doing it
-v, --verbose Enable verbose logging
-h, --help Show help message
```
## Rate Limits
GitHub API allows 5,000 requests per hour for authenticated users. The collector handles rate limiting automatically — it will pause and resume when limits reset.
For large repositories (10,000+ issues), consider:
* Using date ranges to split collection across multiple runs
* Running overnight when you won't need the token for other work
## Troubleshooting
### "GITHUB\_TOKEN environment variable is required"
Set your token:
```bash theme={null}
export GITHUB_TOKEN=ghp_your_token_here
```
### "API rate limit exceeded"
The collector waits automatically. For immediate needs, check your [rate limit status](https://api.github.com/rate_limit) (requires authentication).
### JBang not found after install
Restart your terminal or run:
```bash theme={null}
source ~/.bashrc # or ~/.zshrc
```
### Duplicates in collected data
Run verification and deduplication:
```bash theme={null}
jbang collect@spring-ai-community/github-collector \
--type issues \
--deduplicate \
--verify-dir path/to/your/data
```
# MCP Annotations
Source: https://springaicommunity.mintlify.app/projects/incubating/mcp-annotations
Annotation-based method handling for Model Context Protocol servers in Java
![]()
![]() [GitHub](https://github.com/spring-ai-community/mcp-annotations) • [Maven](https://central.sonatype.com/artifact/org.springaicommunity/mcp-annotations)
## Overview
The MCP Annotations project provides annotation-based method handling for [Model Context Protocol (MCP)](https://github.com/modelcontextprotocol/spec) servers in Java. It simplifies the creation and registration of MCP server methods through a clean, declarative approach using Java annotations.
## Features
Simplifies creation and registration of MCP methods
Support for both synchronous and asynchronous operations
Full server exchange or lightweight transport context
Automatic JSON schema generation from method signatures
Handle dynamic schemas at runtime via CallToolRequest
Full Java type safety with comprehensive validation
## Key Components
### Server Annotations
Annotates methods that implement MCP tools with automatic JSON schema generation
Annotates methods that provide access to resources via URI templates
Annotates methods that generate prompt messages
Annotates methods that provide completion functionality for prompts or URI templates
### Client Annotations
Handle logging message notifications from MCP servers
Handle sampling requests from MCP servers
Handle progress notifications for long-running operations
Handle elicitation requests to gather additional information from users
## Quick Start
### Installation
```xml theme={null}
org.springaicommunity
mcp-annotations
...
```
And the Java MCP SDK:
```xml theme={null}
io.modelcontextprotocol.sdk
mcp
...
```
### Simple Tool Example
```java theme={null}
public class CalculatorToolProvider {
@McpTool(name = "add", description = "Add two numbers together")
public int add(
@McpToolParam(description = "First number to add", required = true) int a,
@McpToolParam(description = "Second number to add", required = true) int b) {
return a + b;
}
@McpTool(name = "multiply", description = "Multiply two numbers")
public double multiply(
@McpToolParam(description = "First number", required = true) double x,
@McpToolParam(description = "Second number", required = true) double y) {
return x * y;
}
}
```
### Create MCP Server
```java theme={null}
List toolSpecifications =
new SyncMcpToolProvider(List.of(calculatorProvider)).getToolSpecifications();
McpSyncServer syncServer = McpServer.sync(transportProvider)
.serverInfo("calculator-server", "1.0.0")
.capabilities(ServerCapabilities.builder()
.tools(true)
.build())
.tools(toolSpecifications)
.build();
```
## Spring AI MCP Integration
For a complete out-of-the-box experience with Spring Boot, Spring AI provides full MCP support with auto-configurations.
Official Spring AI MCP quick start guide
Complete Spring AI MCP Annotations documentation
Server-side annotation reference
Official Spring AI example project
## Requirements
* Java 17 or higher
* Reactor Core (for async operations)
* MCP Java SDK 0.13.0-SNAPSHOT or higher
## Resources
View source code and contribute
Download releases and snapshots
## License
This project is licensed under the Apache License 2.0 - see the [LICENSE](https://github.com/spring-ai-community/mcp-annotations/blob/main/LICENSE) file for details.
# MCP Security
Source: https://springaicommunity.mintlify.app/projects/incubating/mcp-security
Security support for Model Context Protocol implementations
![Incubating Status]() ## Overview
The MCP Security project provides security support and best practices for implementing secure Model Context Protocol (MCP) servers and clients in Java.
This is an incubating project focused on bringing enterprise-grade security to MCP implementations.
## Project Goals
Secure communication channels for MCP
Authentication mechanisms for MCP servers/clients
Fine-grained access control for MCP operations
Security audit trails for MCP interactions
## Key Features (Planned)
* TLS/SSL support for MCP transports
* Certificate validation and management
* Secure WebSocket connections
* API key authentication
* OAuth2/OIDC integration
* Role-based access control (RBAC)
* Policy-based authorization
* Schema validation for MCP requests
* Parameter sanitization
* Protection against injection attacks
* Request rate limiting
* Resource usage quotas
* DDoS protection
* Security event logging
* Audit trail generation
* Compliance reporting
## Why MCP Security Matters
The Model Context Protocol enables powerful integrations between AI systems and external tools/resources. However, this power requires careful security considerations:
**Security Risks:**
* Unauthorized access to sensitive resources
* Data exfiltration through MCP tools
* Code injection via malicious prompts
* Resource exhaustion attacks
* Privilege escalation
MCP Security aims to provide a comprehensive security framework to mitigate these risks.
## Use Cases
Secure MCP servers for enterprise environments with strict security requirements
Isolate MCP resources and operations across different tenants
Protect public-facing MCP endpoints from abuse and attacks
Meet compliance requirements for healthcare, finance, and government sectors
## Getting Started
This project is currently in the incubation phase. Documentation and examples will be added as features are implemented.
## Roadmap
* Core security abstractions
* Basic authentication support
* TLS/SSL transport security
* RBAC implementation
* Policy engine integration
* Resource-level permissions
* Rate limiting and throttling
* Audit logging framework
* Security monitoring and alerting
* Spring Security integration
* OAuth2/OIDC support
* Enterprise identity provider integration
## Resources
View source code and contribute
## Contributing
We welcome contributions! Areas where we need help:
* Security architecture and design
* Implementation of authentication mechanisms
* Security testing and vulnerability assessment
* Documentation and best practices
## License
This project is licensed under the Apache License 2.0.
# Spring AG-UI
Source: https://springaicommunity.mintlify.app/projects/incubating/spring-agui
AG-UI protocol implementation for Spring AI
![Incubating Status]()
![Recently Approved]() ## Overview
Spring AI AG-UI provides an implementation of the AG-UI protocol for Spring AI applications. AG-UI is a protocol designed to enable seamless integration between AI agents and user interfaces, allowing for rich, interactive AI-powered applications.
This project was recently approved and is in the process of being migrated to the spring-ai-community organization.
## What is AG-UI?
AG-UI (Agent-UI) is a protocol that bridges the gap between AI agents and user interfaces, providing a standardized way for agents to interact with UI components, handle user interactions, and manage application state.
## Key Features
Full implementation of the AG-UI protocol specification
Native integration with Spring AI's agent capabilities
Built for Java developers using familiar Spring patterns
Strongly-typed interfaces for reliable agent-UI communication
## Use Cases
Build applications where AI agents can dynamically interact with UI components
Coordinate multiple AI agents with shared UI state and interactions
Enable agents to provide real-time feedback through UI updates
Support for text, images, and other media types in agent-UI communication
## Getting Started
### Prerequisites
* Java 17 or later
* Spring Boot 3.x
* Spring AI
### Installation
Maven artifacts will be available once the project is fully migrated to the spring-ai-community organization.
## Development Team
* **Pascal Wilbrink** (@pascalwilbrink) - Project maintainer
## Resources
Official AG-UI protocol documentation
Current repository (will migrate to spring-ai-community)
Original community proposal
## Project Status
This project is currently in the migration phase. The repository will be transferred to the spring-ai-community organization soon.
## License
This project uses the Apache 2.0 license.
# Spring AI Agent Utils
Source: https://springaicommunity.mintlify.app/projects/incubating/spring-ai-agent-utils
Claude Code-inspired tools and agent skills for Spring AI applications
![Incubating Status]() [GitHub](https://github.com/spring-ai-community/spring-ai-agent-utils) • [Maven Central](https://central.sonatype.com/artifact/org.springaicommunity/spring-ai-agent-utils)
## Overview
Spring AI Agent Utils brings [Claude Code](https://code.claude.com/docs/en/overview)-inspired tools and agent skills to Spring AI applications. This library reimplements core Claude Code capabilities as Spring AI tools, enabling sophisticated agentic workflows with file operations, shell execution, web access, task management, and extensible agent skills.
**Version**: 0.4.0 • Requires Spring AI 2.0.0-SNAPSHOT or 2.0.0-M2
## Tool Categories
Read, write, and edit files with precise control
Execute commands with timeout, background processes, and output filtering
Grep and Glob for fast code search and file pattern matching
AI-powered web fetch with caching and Brave search integration
Todo tracking and multi-agent task orchestration
Extensible sub-agents with A2A protocol support
Reusable knowledge modules in Markdown with YAML front-matter
## Quick Start
### Add Dependency
```xml theme={null}
org.springaicommunity
spring-ai-agent-utils
0.4.0
```
### Configure Your Agent
```java theme={null}
ChatClient chatClient = chatClientBuilder
// System prompt with environment context
.defaultSystem(p -> p.text(agentSystemPrompt)
.param(AgentEnvironment.ENVIRONMENT_INFO_KEY, AgentEnvironment.info())
.param(AgentEnvironment.GIT_STATUS_KEY, AgentEnvironment.gitStatus()))
// Core Tools
.defaultTools(
ShellTools.builder().build(),
FileSystemTools.builder().build(),
GrepTool.builder().build(),
GlobTool.builder().build(),
SmartWebFetchTool.builder(chatClient).build(),
BraveWebSearchTool.builder(braveApiKey).build())
// Task Management
.defaultTools(TodoWriteTool.builder().build())
// Skills System
.defaultToolCallbacks(SkillsTool.builder()
.addSkillsDirectory(".claude/skills")
.build())
// Sub-Agents
.defaultToolCallbacks(TaskToolCallbackProvider.builder()
.chatClientBuilder("default", chatClientBuilder.clone())
.subagentReferences(ClaudeSubagentReferences.fromRootDirectory(".claude/agents"))
.build())
.build();
```
## Core Tools
### FileSystemTools
Read, write, and edit files with precise control:
```java theme={null}
FileSystemTools.builder()
.allowedPaths(List.of("/project")) // Restrict access
.build();
```
Operations: `readFile`, `writeFile`, `editFile`, `listDirectory`
### ShellTools
Execute shell commands with timeout control and background process management:
```java theme={null}
ShellTools.builder()
.defaultTimeout(Duration.ofMinutes(2))
.allowBackgroundProcesses(true)
.build();
```
Features: timeout control, background execution, regex output filtering
### GrepTool
Pure Java grep implementation for code search:
```java theme={null}
GrepTool.builder()
.maxResults(100)
.build();
```
Features: regex patterns, glob filtering, multiple output modes (content, files, count)
### GlobTool
Fast file pattern matching:
```java theme={null}
GlobTool.builder().build();
```
Supports patterns like `**/*.java`, `src/**/*.ts`
### SmartWebFetchTool
AI-powered web content summarization with caching:
```java theme={null}
SmartWebFetchTool.builder(chatClient)
.cacheDuration(Duration.ofMinutes(15))
.build();
```
### BraveWebSearchTool
Web search with domain filtering:
```java theme={null}
BraveWebSearchTool.builder(braveApiKey)
.maxResults(10)
.build();
```
## User Interaction
### AskUserQuestionTool
Ask users clarifying questions during agent execution:
```java theme={null}
AskUserQuestionTool.builder()
.questionHandler(questions -> {
// Display questions to user, collect answers
return answers;
})
.build();
```
Supports multiple-choice options and free-form input.
## Task Management
### TodoWriteTool
Structured task management with state tracking:
```java theme={null}
TodoWriteTool.builder().build();
```
Track tasks with states: `pending`, `in_progress`, `completed`
### TaskTools (Sub-Agents)
Extensible sub-agent system for delegating complex tasks to specialized agents:
```java theme={null}
TaskToolCallbackProvider.builder()
.chatClientBuilder("default", chatClientBuilder)
.chatClientBuilder("haiku", haikuBuilder) // Multi-model support
.subagentReferences(ClaudeSubagentReferences.fromRootDirectory(".claude/agents"))
.skillsDirectories(".claude/skills")
.build();
```
**Features:**
* **Multi-model routing** - Use different models for different sub-agents
* **Pluggable backends** - Claude-style, A2A protocol, or custom implementations
* **Background task execution** - Run sub-agents asynchronously
* **Task output retrieval** - Get results from background tasks
### A2A Protocol Support
The sub-agent architecture supports the [A2A (Agent-to-Agent) protocol](https://github.com/a2aprotocol/a2a-spec) for interoperability with external agents:
```java theme={null}
// Custom A2A subagent integration (see subagent-demo example)
public class A2ASubagentExecutor implements SubagentExecutor {
@Override
public String execute(TaskCall taskCall, SubagentDefinition subagent) {
AgentCard agentCard = ((A2ASubagentDefinition) subagent).getAgentCard();
// Send message via A2A protocol
Client client = Client.builder(agentCard)
.withTransport(JSONRPCTransport.class, config)
.build();
client.sendMessage(message);
// ...
}
}
```
The extensible architecture uses three interfaces:
* `SubagentResolver` - Discovers and loads sub-agent definitions
* `SubagentExecutor` - Executes tasks on sub-agents
* `SubagentDefinition` - Describes a sub-agent's capabilities
## Agent Skills
Extend AI capabilities with reusable knowledge modules:
```markdown theme={null}
---
name: code-review
description: Reviews code for best practices
tools: [FileSystemTools, GrepTool]
---
# Code Review Skill
When reviewing code, check for:
1. Security vulnerabilities
2. Performance issues
3. Code style consistency
...
```
Load skills from directories:
```java theme={null}
SkillsTool.builder()
.addSkillsDirectory(".claude/skills")
.addSkillsDirectory("/shared/skills")
.build();
```
## AgentEnvironment
Dynamic context utility for system prompts:
```java theme={null}
.defaultSystem(p -> p.text(systemPrompt)
.param(AgentEnvironment.ENVIRONMENT_INFO_KEY, AgentEnvironment.info())
.param(AgentEnvironment.GIT_STATUS_KEY, AgentEnvironment.gitStatus())
.param(AgentEnvironment.AGENT_MODEL_KEY, "claude-sonnet-4-5")
.param(AgentEnvironment.AGENT_MODEL_KNOWLEDGE_CUTOFF_KEY, "2025-01-01"))
```
Provides: working directory, platform info, git status, model information
## Examples
| Example | Description |
| ------------------------ | --------------------------------------------------------- |
| `code-agent-demo` | Full-featured AI coding assistant with interactive CLI |
| `todo-demo` | Task management with TodoWriteTool and progress tracking |
| `subagent-demo` | Extensible sub-agent system with A2A protocol integration |
| `skills-demo` | Custom skill development with SkillsTool |
| `ask-user-question-demo` | Interactive agent-user communication |
## Requirements
* Java 17+
* Spring Boot 3.x / 4.x
* Spring AI 2.0.0-SNAPSHOT or 2.0.0-M2
## Resources
Source code, examples, and detailed documentation
Original Claude Code documentation (inspiration)
## License
This project is licensed under the [Apache License 2.0](https://github.com/spring-ai-community/spring-ai-agent-utils/blob/main/LICENSE.txt).
# Spring AI Bedrock AgentCore
Source: https://springaicommunity.mintlify.app/projects/incubating/spring-ai-bedrock-agentcore
Spring Boot starter for AWS Bedrock AgentCore Runtime integration
![Incubating Status]() [GitHub](https://github.com/spring-ai-community/spring-ai-bedrock-agentcore) • [Maven Central](https://central.sonatype.com/search?q=org.springaicommunity%20bedrock-agentcore)
## Overview
A Spring Boot starter that enables existing Spring Boot applications to conform to the AWS Bedrock AgentCore Runtime contract with minimal configuration. Simply add the dependency and annotate your agent methods.
**Version**: 1.0.0-RC3
## Modules
| Module | Description |
| ------------------------------------- | ----------------------------------------------------- |
| `spring-ai-bedrock-agentcore-starter` | Core starter for AgentCore Runtime integration |
| `spring-ai-memory-bedrock-agentcore` | Spring AI ChatMemoryRepository using AgentCore Memory |
## Key Features
Automatically sets up AgentCore endpoints when added as dependency
Simple `@AgentCoreInvocation` annotation to mark agent methods
Server-Sent Events support with `Flux` return types
Built-in `/ping` endpoint with Spring Boot Actuator integration
Prevents premature shutdown during background work
Built-in Bucket4j throttling for invocations and ping endpoints
## Quick Start
### 1. Add Dependency
```xml theme={null}
org.springaicommunity
spring-ai-bedrock-agentcore-starter
1.0.0-RC3
```
### 2. Create Agent Method
```java theme={null}
@Service
public class MyAgentService {
@AgentCoreInvocation
public String handleUserPrompt(MyRequest request) {
return "You said: " + request.prompt;
}
}
```
### 3. Run Application
The application will automatically expose:
* `POST /invocations` - Agent processing endpoint
* `GET /ping` - Health check endpoint
## Supported Method Signatures
```java theme={null}
@AgentCoreInvocation
public MyResponse processRequest(MyRequest request) {
return new MyResponse("Processed: " + request.prompt());
}
record MyRequest(String prompt) {}
record MyResponse(String message) {}
```
```java theme={null}
@AgentCoreInvocation
public MyResponse processWithContext(MyRequest request, AgentCoreContext context) {
var sessionId = context.getHeader(AgentCoreHeaders.SESSION_ID);
return new MyResponse("Session " + sessionId + ": " + request.prompt());
}
```
```java theme={null}
@AgentCoreInvocation
public Map processData(Map data) {
return Map.of(
"input", data,
"response", "Processed: " + data.get("message"),
"timestamp", System.currentTimeMillis()
);
}
```
```java theme={null}
@AgentCoreInvocation
public String handlePrompt(String prompt) {
return "Response: " + prompt;
}
```
```java theme={null}
@AgentCoreInvocation
public Flux streamingAgent(String prompt) {
return chatClient.prompt().user(prompt).stream().content();
}
```
## Background Task Tracking
AWS Bedrock AgentCore Runtime monitors agent health and may shut down agents that appear idle. Use `AgentCoreTaskTracker` to communicate active work:
```java theme={null}
@AgentCoreInvocation
public String asyncTaskHandling(MyRequest request, AgentCoreContext context) {
agentCoreTaskTracker.increment(); // Starting background work
CompletableFuture.runAsync(() -> {
// Long-running background work
}).thenRun(agentCoreTaskTracker::decrement); // Work completed
return "Task started";
}
```
The `/ping` endpoint returns:
* **"Healthy"** - Agent is ready, no background tasks
* **"HealthyBusy"** - Agent is healthy but actively processing (prevents shutdown)
* **"Unhealthy"** - Agent has issues (with Actuator integration)
## Health Monitoring
**Without Spring Boot Actuator:**
* Returns static "Healthy" status
* Always responds with HTTP 200
**With Spring Boot Actuator:**
```xml theme={null}
org.springframework.boot
spring-boot-starter-actuator
```
* Integrates with Actuator health checks
* Maps Actuator status: `UP` → "Healthy", `DOWN` → "Unhealthy"
* Tracks status change timestamps
## Custom Controller Override
Override default controllers with custom implementations using marker interfaces:
```java theme={null}
// Override /invocations
@RestController
public class CustomInvocationsController implements AgentCoreInvocationsHandler {
@PostMapping("/invocations")
public ResponseEntity handleInvocations(@RequestBody String request) {
return ResponseEntity.ok("Custom response");
}
}
// Override /ping
@RestController
public class CustomPingController implements AgentCorePingHandler {
@GetMapping("/ping")
public ResponseEntity ping() {
return ResponseEntity.ok(Map.of("status", "Custom Healthy"));
}
}
```
## Configuration
```properties theme={null}
# Rate limits in requests per minute (optional, disabled by default)
agentcore.throttle.invocations-limit=50
agentcore.throttle.ping-limit=200
```
***
## Memory Module
The `spring-ai-memory-bedrock-agentcore` module provides Spring AI `ChatMemoryRepository` integration with AWS Bedrock AgentCore Memory for persistent conversation storage.
### Add Dependency
```xml theme={null}
org.springaicommunity
spring-ai-memory-bedrock-agentcore
1.0.0-RC3
```
### Configure Memory
```yaml theme={null}
agentcore:
memory:
memory-id: your-agentcore-memory-id # Required
total-events-limit: 100 # Max events to retrieve
default-session: default-session # Default session name
page-size: 50 # API pagination size
ignore-unknown-roles: false # Handle unknown roles
```
### Use with Spring AI
```java theme={null}
@Service
public class ChatService {
private final ChatClient chatClient;
private final ChatMemory chatMemory;
public ChatService(ChatClient.Builder chatClientBuilder, ChatMemoryRepository memoryRepository) {
this.chatClient = chatClientBuilder.build();
this.chatMemory = MessageWindowChatMemory.builder()
.chatMemoryRepository(memoryRepository)
.maxMessages(10)
.build();
}
public String chat(String conversationId, String message) {
return chatClient.prompt()
.user(message)
.advisors(chatMemory.getChatMemoryAdvisor(conversationId))
.call()
.content();
}
}
```
### Conversation ID Format
* **Simple**: `user123` → actor: `user123`, session: `default-session`
* **With Session**: `user123:session456` → actor: `user123`, session: `session456`
### Message Type Mapping
| Spring AI Message | AgentCore Role | Supported |
| --------------------- | -------------- | --------- |
| `UserMessage` | `USER` | Yes |
| `AssistantMessage` | `ASSISTANT` | Yes |
| `SystemMessage` | N/A | Filtered |
| `ToolResponseMessage` | N/A | Filtered |
### AWS Permissions
```json theme={null}
{
"Effect": "Allow",
"Action": [
"bedrock-agentcore:ListEvents",
"bedrock-agentcore:CreateEvent",
"bedrock-agentcore:DeleteEvent"
],
"Resource": "arn:aws:bedrock-agentcore:*:*:memory/*"
}
```
## Examples
See the `examples/` directory in the repository:
| Example | Description |
| --------------------------------- | ------------------------------------------------------ |
| `simple-spring-boot-app/` | Minimal AgentCore agent with async task tracking |
| `spring-ai-sse-chat-client/` | SSE streaming with Spring AI and Amazon Bedrock |
| `spring-ai-simple-chat-client/` | Traditional Spring AI integration |
| `spring-ai-override-invocations/` | Custom controller override using marker interfaces |
| `spring-ai-extended-chat-client/` | Extended chat client with JWT and Terraform deployment |
| `spring-ai-memory-integration/` | Memory module integration example |
## Requirements
* Java 17+
* Spring Boot 3.x
* Spring AI 1.1.1+ (for memory module)
## Resources
Source code and contribution guidelines
AWS Bedrock AgentCore documentation
## License
This project is licensed under the [Apache License 2.0](https://github.com/spring-ai-community/spring-ai-bedrock-agentcore/blob/main/LICENSE).
# Spring AI Playground
Source: https://springaicommunity.mintlify.app/projects/incubating/spring-ai-playground
Self-hosted web UI for AI experimentation, RAG workflows, and MCP integrations
![Incubating Status]() [GitHub](https://github.com/spring-ai-community/spring-ai-playground)
## Overview
**Spring AI Playground** is a self-hosted web UI that simplifies AI experimentation and testing. It provides Java developers with an intuitive interface for working with **large language models (LLMs)**, **vector databases**, **prompt engineering**, and **Model Context Protocol (MCP)** integrations.
Built on **Spring AI**, it supports leading model providers and includes comprehensive tools for testing **retrieval-augmented generation (RAG)** workflows and MCP integrations. The goal is to make AI more accessible to developers, helping them quickly prototype **Spring AI-based applications** with enhanced contextual awareness and external tool capabilities.
**Version**: Latest from GitHub
No API keys required when using Ollama - easy to get started!
## Key Features
Unified chat interface with dynamic RAG and MCP integration
Full RAG flows: upload, chunk, embed, search with score details
Register, test, and invoke MCP tools interactively
Progressive Web App for desktop and mobile
Ollama, OpenAI, and OpenAI-compatible servers
Modern, responsive UI built with Vaadin Flow
## Playgrounds
### Chat Playground
A unified chat interface powered by Spring AI's ChatClient that dynamically uses configurations from VectorDB and MCP playgrounds, enabling conversations enriched with retrieval and external tools.
![Chat Playground with MCP]() ### VectorDB Playground
![VectorDB Playground]() Supports full RAG flows with Spring AI's `RetrievalAugmentationAdvisor`:
* **Custom Chunk Input**: Directly input and chunk custom text for embedding
* **Document Uploads**: Upload PDFs, Word documents, and PowerPoint presentations
* **Search and Scoring**: Vector similarity searches with similarity scores (0-1)
* **Filter Expressions**: Metadata-based filtering (e.g., `author == 'John' && year >= 2023`)
### MCP Playground
![MCP Playground]() Comprehensive Model Context Protocol integration:
* **Connection Management**: Configure MCP connections with STREAMABLE HTTP, STDIO, and SSE transports
* **MCP Inspector**: Explore available tools with detailed information on arguments and parameters
* **Interactive Testing**: Execute MCP tools directly with real-time results and execution history
**STREAMABLE HTTP** (MCP v2025-03-26) is a single-endpoint HTTP transport replacing HTTP+SSE. Clients send JSON-RPC via POST to /mcp with optional SSE-style streaming.
## Supported Technologies
* **Ollama** - Local LLM with tool-enabled models
* **OpenAI** - GPT-3.5, GPT-4, and more
* **OpenAI-compatible servers** - llama.cpp, TabbyAPI, LM Studio
* **All Spring AI supported providers** - Anthropic, Google, Amazon, Microsoft
All Spring AI VectorStore implementations including:
* PostgreSQL/PGVector, ChromaDB, Milvus, Qdrant, Redis
* Pinecone, Weaviate, Elasticsearch, MongoDB Atlas
* Neo4j, OpenSearch, Oracle, Azure Cosmos DB
* **STREAMABLE HTTP** - New single-endpoint transport (MCP v2025-03-26)
* **STDIO** - Direct process communication (requires local running)
* **SSE** - Server-Sent Events transport
## Quick Start
### Prerequisites
* Java 21 or later
* Ollama running on your machine
* Docker (optional, but recommended)
### Running with Docker (Recommended)
```bash theme={null}
# Clone the repository
git clone https://github.com/spring-ai-community/spring-ai-playground.git
cd spring-ai-playground
# Build Docker image
./mvnw spring-boot:build-image -Pproduction -DskipTests=true \
-Dspring-boot.build-image.imageName=jmlab/spring-ai-playground:latest
# Run container
docker run -d -p 8282:8282 --name spring-ai-playground \
-e SPRING_AI_OLLAMA_BASE_URL=http://host.docker.internal:11434 \
-v spring-ai-playground:/home \
--restart unless-stopped \
jmlab/spring-ai-playground:latest
```
Access the application at [http://localhost:8282](http://localhost:8282)
**MCP STDIO Transport**: Docker is not suitable for testing MCP STDIO transport as it requires direct process-to-process communication. Use local running instead.
**Linux Users**: `host.docker.internal` may not be available. Use `--network="host"` or replace with your host machine's IP (e.g., `172.17.0.1`).
### Running Locally
```bash theme={null}
./mvnw clean install -Pproduction -DskipTests=true
./mvnw spring-boot:run
```
### PWA Installation
Spring AI Playground supports Progressive Web App installation for a native app-like experience:
1. Open the application at `http://localhost:8282`
2. Look for the browser's PWA install prompt or the "Install PWA" button
3. Follow the installation wizard
## Chat Using RAG
1. **Set Up Vector Database**: Upload documents through the VectorDB Playground
2. **Select Documents**: Choose documents to use as the knowledge base
3. **Chat**: The system retrieves relevant content and generates knowledge-grounded responses
## Chat Using MCP
1. **Configure MCP Servers**: Set up connections in the MCP Playground
2. **Select Connections**: Choose MCP connections in the Chat page
3. **Chat**: The AI automatically uses available MCP tools based on context
When using Ollama, ensure you're using a **tool-enabled model** that supports function calling. Check [Ollama's Tools category](https://ollama.com/search?c=tools) for compatible models.
## Upcoming Features
Build production-ready agents combining MCP, RAG, and Chat in unified workflows
Tools to track and monitor AI performance, usage, and errors
Login and security features to control access
Embedding, image, audio, and moderation models
## Resources
View source code and contribute
Spring AI reference documentation
## License
Spring AI Playground is Open Source software released under the [Apache 2.0 license](https://github.com/spring-ai-community/spring-ai-playground/blob/main/LICENSE).
# Spring AI Replicate
Source: https://springaicommunity.mintlify.app/projects/incubating/spring-ai-replicate
Spring AI integration for Replicate.com with access to hundreds of AI models
![Incubating Status]() [GitHub](https://github.com/spring-ai-community/spring-ai-replicate) • [Replicate.com](https://replicate.com)
## Overview
This project provides Spring AI integration for [Replicate.com](https://replicate.com), enabling access to **hundreds of AI models** for text generation, image/video/audio generation, embeddings, classification, and more.
Replicate hosts a wide variety of AI models with varying input/output schemas. Rather than creating model-specific implementations, this integration provides **four flexible adapter models** that work with any Replicate model:
Conversational LLMs (Claude, GPT, Llama, Grok, etc.)
Media generation (images, video, audio)
String outputs (classifiers, detectors)
Structured outputs (embeddings, JSON responses)
**Version**: 1.0.0-SNAPSHOT
Maven snapshot artifacts are available from [Maven Central Snapshots](https://central.sonatype.com/repository/maven-snapshots/org/springaicommunity/)
## Project Structure
```
spring-ai-replicate/
├── spring-ai-replicate/ # API, Models and Options
├── spring-ai-replicate-spring-boot-autoconfigure/ # Autoconfiguration
└── spring-ai-replicate-spring-boot-starter/ # Starter Dependency
```
## Quick Start
### Add Dependency
```xml theme={null}
org.springaicommunity
spring-ai-replicate-spring-boot-starter
1.0.0-SNAPSHOT
```
### Configure Models
Configure via `application.properties`:
```properties theme={null}
# API Token
spring.ai.replicate.api-token=REPLICATE_TOKEN
# Polling interval for async operations
spring.ai.replicate.retry-fixed-backoff=1000ms
# Chat model (LLMs)
spring.ai.replicate.chat.options.model=meta/meta-llama-3-8b-instruct
spring.ai.replicate.chat.options.input.temperature=0.7
spring.ai.replicate.chat.options.input.max_tokens=500
# Media model (image/video/audio generation)
spring.ai.replicate.media.options.model=black-forest-labs/flux-schnell
spring.ai.replicate.media.options.input.num_outputs=2
# String model (classification/detection)
spring.ai.replicate.string.options.model=falcons-ai/nsfw_image_detection
# Structured model (embeddings)
spring.ai.replicate.structured.options.model=openai/clip
```
All model beans are automatically created and available for injection.
## Usage Examples
### Chat Model (Conversational AI)
```java theme={null}
@RestController
class ChatController {
@Autowired
private ReplicateChatModel chatModel;
@GetMapping("/chat")
public String chat(@RequestParam String message) {
return chatModel.call(message);
}
}
```
**Streaming support:**
```java theme={null}
public void streamingChat() {
Flux responseFlux = chatModel.stream(
new Prompt("Count from 1 to 100")
);
responseFlux.subscribe(chatResponse -> {
String chunk = chatResponse.getResult().getOutput().getText();
System.out.print(chunk);
});
}
```
### Media Model (Image/Video/Audio Generation)
```java theme={null}
@Autowired
private ReplicateMediaModel mediaModel;
public void generateImages() {
ReplicateOptions options = ReplicateOptions.builder()
.model("black-forest-labs/flux-schnell")
.withParameter("prompt", "a cat sitting on a laptop")
.withParameter("num_outputs", 2)
.build();
MediaResponse response = mediaModel.generate(options);
List imageUrls = response.getUris();
imageUrls.forEach(url -> System.out.println("Image URL: " + url));
}
```
### String Model (Classification/Detection)
Two ways to upload resources to Replicate:
**File Upload:**
```java theme={null}
@Autowired
private ReplicateStringModel stringModel;
@Autowired
private ReplicateApi replicateApi;
public void classifyImage() {
FileSystemResource fileResource = new FileSystemResource(
Paths.get("path/to/image.jpg")
);
FileUploadResponse uploadResponse = replicateApi.uploadFile(
fileResource, "image.jpg"
);
String imageUrl = uploadResponse.urls().get();
ReplicateOptions options = ReplicateOptions.builder()
.model("falcons-ai/nsfw_image_detection")
.withParameter("image", imageUrl)
.build();
StringResponse response = stringModel.generate(options);
System.out.println("Classification: " + response.getOutput());
}
```
**Base64 Encoding:**
```java theme={null}
public void classifyWithBase64() {
byte[] imageBytes = Files.readAllBytes(Paths.get("path/to/image.jpg"));
String base64Image = "data:application/octet-stream;base64,"
+ Base64.getEncoder().encodeToString(imageBytes);
ReplicateOptions options = ReplicateOptions.builder()
.model("falcons-ai/nsfw_image_detection")
.withParameter("image", base64Image)
.build();
StringResponse response = stringModel.generate(options);
}
```
### Structured Model (Embeddings)
```java theme={null}
@Autowired
private ReplicateStructuredModel structuredModel;
public void generateEmbeddings() {
ReplicateOptions options = ReplicateOptions.builder()
.model("openai/clip")
.withParameter("text", "spring ai framework")
.build();
StructuredResponse response = structuredModel.generate(options);
Map rawOutput = response.getOutput();
MyClass output = objectMapper.convertValue(rawOutput, MyClass.class);
}
```
## Per-Request Options
Override configuration on a per-request basis:
```java theme={null}
public void chatWithOptions() {
ReplicateChatOptions options = ReplicateChatOptions.builder()
.model("meta/meta-llama-3-8b-instruct")
.withParameter("temperature", 0.8)
.withParameter("max_tokens", 100)
.build();
Prompt prompt = new Prompt("Tell me a joke", options);
ChatResponse response = chatModel.call(prompt);
System.out.println(response.getResult().getOutput().getText());
System.out.println("Tokens used: " +
response.getMetadata().getUsage().getTotalTokens());
}
```
**Chat Model Options**: Use `ReplicateChatOptions` for chat models to integrate with Spring AI conventions. Other models use `ReplicateOptions`.
## Important Notes
**Multi-turn Conversations**: The current implementation does not support multi-turn conversations with conversation history. Each call is independent due to varying model schemas.
### Model Discovery
Visit [Replicate.com/explore](https://replicate.com/explore) to discover available models. Each model has different input parameters - check the model's documentation for specific requirements.
## Resources
View source code and contribute
Explore hundreds of available AI models
Spring AI reference documentation
Replicate API documentation
## License
Spring AI Replicate is Open Source software released under the [Apache 2.0 license](https://github.com/spring-ai-community/spring-ai-replicate/blob/main/LICENSE).
# Spring AI Tool Search Tool
Source: https://springaicommunity.mintlify.app/projects/incubating/spring-ai-tool-search-tool
Dynamic tool discovery and selection for Spring AI, enabling LLMs to work efficiently with large tool libraries
![Incubating Status]() [GitHub](https://github.com/spring-ai-community/spring-ai-tool-search-tool) • [Maven](https://central.sonatype.com/repository/maven-snapshots/org/springaicommunity/)
## Overview
As AI agents connect to more services—Slack, GitHub, Jira, MCP servers—tool libraries grow rapidly. A typical multi-server setup can easily have 50+ tools consuming **55,000+ tokens** before any conversation starts. Tool selection accuracy also degrades when models face 30+ similarly-named tools.
**Tool Search Tool** implements [Anthropic's Tool Search Tool pattern](https://www.anthropic.com/engineering/advanced-tool-use) for Spring AI:
* Model receives only a search tool initially (minimal tokens)
* When capabilities are needed, model searches for relevant tools
* Matching tool definitions are dynamically expanded into context
* Model invokes discovered tools to complete the task
**Result:** Significant token savings (80-90%) while maintaining access to thousands of tools.
![Tool Search Tool Calling Flow]() **Version**: 1.0.0-SNAPSHOT
Maven snapshot artifacts are available from [Maven Central Snapshots](https://central.sonatype.com/repository/maven-snapshots/org/springaicommunity/)
## Key Benefits
Reduced context windows with 80-90% token savings
Models select the right tool when focused on fewer options
Works with any LLM supported by Spring AI
Leverages Spring AI's advisor chain for logging and monitoring
## Project Structure
```
spring-ai-tool-search-tool/
├── tool-search-tool/ # Core advisor implementation
├── tool-searchers/ # Pluggable search strategies
│ ├── tool-searcher-vectorstore/ # Semantic search (embeddings)
│ ├── tool-searcher-lucene/ # Keyword search (full-text)
│ └── tool-searcher-regex/ # Pattern matching
├── tool-search-tool-bom/ # Bill of Materials
└── examples/
├── tool-search-tool-demo/ # Recommended approach
└── pre-select-tool-demo/ # Alternative approach
```
## Search Strategies
| Strategy | Module | Best For |
| ------------ | --------------------------- | ---------------------------------------- |
| **Semantic** | `tool-searcher-vectorstore` | Natural language queries, fuzzy matching |
| **Keyword** | `tool-searcher-lucene` | Exact term matching, known tool names |
| **Regex** | `tool-searcher-regex` | Tool name patterns (`get_*`, `*_api`) |
## How It Works
1. **Indexing**: Tools are indexed in the `ToolSearcher` (not sent to LLM)
2. **Initial Request**: Only `toolSearchTool` definition is sent to LLM
3. **Discovery**: LLM calls `toolSearchTool(query="weather")` to find relevant tools
4. **Expansion**: Discovered tools are added to next request
5. **Execution**: LLM calls discovered tools to complete the task
6. **Response**: Final answer generated
## Quick Start
### 1. Add Dependencies
Add the snapshot repository to your `pom.xml`:
```xml theme={null}
central-snapshots
https://central.sonatype.com/repository/maven-snapshots/
true
```
Then add the dependencies:
```xml theme={null}
org.springaicommunity
tool-search-tool
1.0.0-SNAPSHOT
org.springaicommunity
tool-searcher-lucene
1.0.0-SNAPSHOT
```
### 2. Configure the Advisor
```java theme={null}
@Bean
ToolSearcher toolSearcher() {
return new LuceneToolSearcher(0.4f);
}
@Bean
CommandLineRunner demo(ChatClient.Builder builder, ToolSearcher toolSearcher) {
return args -> {
var advisor = ToolSearchToolCallAdvisor.builder()
.toolSearcher(toolSearcher)
.build();
ChatClient chatClient = builder
.defaultTools(new MyTools()) // 100s of tools - NOT sent to LLM initially
.defaultAdvisors(advisor)
.build();
String answer = chatClient
.prompt("What's the weather in Amsterdam?")
.call()
.content();
};
}
```
## Examples
### Tool Search Tool Demo (Recommended)
LLM actively discovers tools on-demand:
```bash theme={null}
cd examples/tool-search-tool-demo
mvn spring-boot:run
```
### Pre-Select Tool Demo (Alternative)
Pre-selects tools based on conversation context:
```bash theme={null}
cd examples/pre-select-tool-demo
mvn spring-boot:run
```
## Requirements
* Java 17+
* Spring AI 1.1.0-M4+
* Maven 3.6+
## Resources
View source code and contribute
Original pattern documentation
Spring AI's tool calling docs
Recursive advisors documentation
## License
Spring AI Tool Search Tool is Open Source software released under the [Apache 2.0 license](https://github.com/spring-ai-community/spring-ai-tool-search-tool/blob/main/LICENSE.txt).
# Spring AI Vaadin
Source: https://springaicommunity.mintlify.app/projects/incubating/spring-ai-vaadin
Vaadin UIs for Spring AI chat and RAG applications
![]() ## Overview
Spring AI Vaadin provides rich user interface components for building AI-powered chat applications using Vaadin and Spring AI. This project demonstrates how to create interactive AI experiences in Spring Boot applications with modern Java UI components.
## Key Features
Interactive chat UI with file upload support for attachments
Upload and analyze documents to provide context for AI queries
Optional Model Context Protocol integration for enhanced capabilities
## Technologies
* **Vaadin** - Rich Java UI components
* **Spring Boot** - Application framework
* **Spring AI** - AI integration
* **RAG** - Document retrieval and context
## Getting Started
### Prerequisites
* Java 21 or higher
* OpenAI API key
### Quick Start
```bash theme={null}
export OPENAI_API_KEY=your-api-key
./mvnw spring-boot:run
```
The application will be available at [http://localhost:8080](http://localhost:8080).
## Using RAG
Click the gear icon to open the settings panel
Upload relevant documents (PDF, DOCX, TXT, etc.)
Ask questions related to the uploaded content for contextual AI responses
## Alternative Frontend
A React-based frontend using Vaadin [Hilla](https://vaadin.com/docs/latest/hilla/faq) is available on the `hilla` branch.
When switching branches, delete the `src/main/frontend/generated` directory to avoid startup issues.
## Resources
* [GitHub Repository](https://github.com/spring-ai-community/spring-ai-vaadin)
* [Vaadin Documentation](https://vaadin.com/docs)
## Maintainer
Led by [tomivirkki](https://github.com/tomivirkki)
# Our Projects
Source: https://springaicommunity.mintlify.app/projects/index
Spring AI Community projects
**Several projects have moved.** Claude Agent SDK, Agent Client, Agent Judge, Agent Sandbox, Agent Bench, ACP Java SDK, and GitHub Collector are now maintained at [markpollack](https://github.com/markpollack) and documented at [lab.pollack.ai](https://lab.pollack.ai). They were general-purpose agent libraries that did not depend on Spring AI — see the [migration page](https://lab.pollack.ai/docs/migration/spring-ai-community-to-markpollack) for details.
## Flagship
AWS Bedrock AgentCore runtime integration for Spring AI — deploy Spring AI agents to the Amazon Bedrock managed runtime
## Active Projects
Claude Code-inspired tools and agent skills for Spring AI
Dynamic tool discovery with 80-90% token savings
Annotation-based Model Context Protocol server development
Security support for Model Context Protocol implementations
Access hundreds of AI models on Replicate.com
Self-hosted web UI for AI experimentation and testing
AG-UI protocol implementation for Spring AI
Vaadin UIs for Spring AI chat and RAG applications
## Resources
Curated collection of tutorials, examples, and resources for Spring AI
***
**Want to add your project?** See our [Project Creation Guide](/community/project-guide) to learn how to propose a new project.